# friction AI — Full content dump for LLM ingestion
# https://www.frictionai.co
# Contact: support@frictionai.co
#
# This file contains the full markdown body of every published blog post.
# For a structured index (pillars + URLs only), see /llms.txt.
#
# Canonical author for all posts: Joao Da Silva, Co-Founder of friction AI
# (https://www.frictionai.co/about)
#
# Organization: friction AI FZ-LLC (Dubai, UAE). Founded 2025.
# Wikidata: https://www.wikidata.org/wiki/Q139279387
#
# AI Visibility & Recommendation Platform — tracking how ChatGPT, Claude,
# Gemini, Perplexity, and Google AI Overviews recognize and recommend brands.
---
# Scrunch AI Alternatives: 7 Platforms Compared by Use Case (2026)
# URL: https://www.frictionai.co/blog/scrunch-ai-alternatives
# Slug: scrunch-ai-alternatives
# Category: Tool Comparisons
# Published: 2026-08-02
# Author: Joao Da Silva, Co-Founder of friction AI
# Keywords: scrunch ai alternatives, scrunch ai competitors, scrunch ai review, friction ai vs scrunch, ai visibility tools
Scrunch is more than an AI visibility tracker. Core combines prompt monitoring with page audits, while Enterprise adds broader model coverage, crawler data and an Agent Experience Platform that can serve a lightweight version of a site to AI agents. That scope is useful, but it also means a buyer may be comparing Scrunch with very different products depending on the problem: analytics, technical visibility, content action or agent delivery.
One disclosure before the comparison: we build friction AI, one of the products below. We link the vendor pages behind pricing and plan claims, and friction AI is not treated as the automatic winner. Scrunch is the better choice when crawler observability, page diagnostics or agent delivery are central requirements.
*Last verified: August 3, 2026.*

## TL;DR
- **AthenaHQ** offers a free baseline and broad model coverage with a dedicated content-action platform.
- **Profound** fits buyers evaluating a larger enterprise AI-search data and governance suite.
- **HubSpot AEO** is a much cheaper daily tracker for HubSpot-centered marketing teams.
- **friction AI** focuses on recommendation accuracy, competitor diagnosis and prioritized work.
- **Peec AI** provides focused daily analytics with unlimited users on self-serve brand plans.
- **Rankscale** offers broad engine choice, flexible cadence and a low credit-based starting point.
- **Semrush AI Visibility** brings AI measurement into an existing SEO toolkit.
Scrunch remains the strongest fit in this set when the brief includes AI bot traffic, crawl errors, page audits and a path into agent-specific content delivery.
## Scrunch pricing and capabilities at a glance
[Scrunch Core](https://scrunch.com/faqs/category/pricing/) costs **$250 per month** for brands. It includes 125 unique prompts, coverage across ChatGPT, Perplexity, Google AI Overviews and Microsoft Copilot, five page audits per month, one brand workspace and five user licenses.
Scrunch Enterprise uses custom pricing. It expands coverage to nine LLMs and adds full-site audits, custom workspaces and users, SAML or OIDC SSO, a dedicated account team and an enterprise data API. Scrunch's broader product also includes AI bot traffic and crawl diagnostics. Its Agent Experience Platform creates a parallel, compressed site experience intended for AI agents while leaving the human site intact.
A seven-day trial includes 100 prompts, three page audits and one topic for search-volume tracking. A credit card is required, and the account converts to a paid plan unless cancelled.
### What Scrunch does well
- Prompt, topic, citation, competitor and position monitoring
- AI bot traffic and crawl-error visibility
- Page audits and prioritized optimization guidance
- Four LLMs on Core and nine on Enterprise
- A distinct agent-delivery path through AXP
- Enterprise controls, API access and multi-brand scaling
### Why teams consider an alternative
1. **The starting price is higher than many trackers.** Several credible monitoring products begin below $100 per month.
2. **The team may not need agent delivery.** AXP is differentiated, but it is irrelevant when the brief ends at measurement and recommendations.
3. **Four Core models may not match the audience.** Broader coverage requires Enterprise, while some alternatives expose more surfaces in self-serve plans.
4. **Five users or one workspace may be restrictive.** Agency and multi-brand teams should price the full arrangement.
5. **Another product may own the action.** Content, CRM, SEO or recommendation-diagnosis workflows can matter more than crawler observability.
## Quick comparison
These entry prices purchase different amounts of data and workflow. Compare prompts, responses, cadence, models, regions, domains, users and audits together.
| Platform | Published entry point | Entry-plan shape | Best fit |
|---|---:|---|---|
| Scrunch AI | $250/mo | 125 prompts, 4 LLMs, 5 audits and 5 users | Monitoring plus crawler and site diagnostics |
| AthenaHQ | Free; Starter $295/mo | 300 free credits; Starter has 3,600 credits and 9-model visibility | Broad monitoring and content actions |
| Profound | $99/mo billed annually | 50 prompts on ChatGPT at Starter | Broader enterprise AI-search evaluation |
| HubSpot AEO | $50/mo | 25 prompts across ChatGPT, Perplexity and Gemini | Affordable HubSpot-connected monitoring |
| friction AI | $69/mo | Weekly Brand Audit plus daily User Prompts | Recommendation diagnosis and prioritized actions |
| Peec AI | $95/mo | 50 prompts, choose 3 models, unlimited users | Focused daily analytics |
| Rankscale | $20/mo | Credit-based monitoring with flexible cadence | Configurable broad-engine tracking |
| Semrush AI Visibility | $99/mo per domain | 25 prompts plus competitor and prompt research | Existing Semrush teams |

## AthenaHQ: for broad monitoring and content actions
[AthenaHQ](https://athenahq.ai/) offers a free Essential plan with 300 credits across five AI surfaces. Starter costs $295 per month and includes 3,600 credits, visibility across nine models, API access, CSV export, integrations and on-page and off-page actions.
AthenaHQ is the stronger Scrunch alternative when the team wants broad model coverage and a content-action environment but does not need crawler traffic or agent delivery. Its free plan also offers a lower-friction way to examine responses, competitors and sources.
Scrunch Core provides more included prompts than many self-serve products and adds page audits, but covers four LLMs. The enterprise comparison is more nuanced: both vendors add regions, integrations and governance, while Scrunch differentiates through crawl observability and AXP.
## Profound: for an enterprise data suite
[Profound](https://www.tryprofound.com/pricing) lists Starter at $99 per month with annual billing for 50 prompts on ChatGPT. Growth costs $399 per month billed annually and broadens model coverage. Enterprise expands into Profound's wider analytics, data and governance products.
Profound is the better alternative when the procurement process is evaluating a broad AI-search intelligence suite and the organization expects a larger data program. Scrunch is more distinctive when technical teams need to see how AI bots reach the site and potentially control the experience served to those agents.
Neither entry plan represents the enterprise product fully. Ask both vendors to price the same models, markets, prompts, history, exports and support requirements. For a wider shortlist, see [Profound Alternatives](/blog/profound-ai-alternative-affordable-ai-visibility).
## HubSpot AEO: for an affordable marketing workflow
[HubSpot AEO](https://www.hubspot.com/products/aeo/ai-visibility) costs $50 per month for 25 prompts across ChatGPT, Perplexity and Gemini. It refreshes daily and includes competitor visibility, share of voice, citation analysis and recommendations. Marketing Hub Professional and Enterprise customers can connect AEO with HubSpot customer data.
HubSpot is the stronger alternative when the program is owned by a marketing team that already works in HubSpot and does not need Scrunch's technical layer. The price difference is large, though HubSpot includes fewer prompts and answer surfaces than Scrunch Core.
Choose HubSpot when the purpose is a compact visiblity dashboard tied to CRM context. Choose Scrunch when audits, bot traffic, crawl issues or agent delivery belong in the same operating plan.
## Scrunch AI vs friction AI
Scrunch begins with a broad view of the AI customer journey. It monitors prompts and citations, observes AI bots, audits pages and can change how content is delivered to agents through AXP.
friction AI begins with repeated recommendation measurement. User Prompts run daily. The weekly Brand Audit benchmarks recognition, visibility, sentiment and purchase intent against competitors. Improve turns gaps into prioritized work. Growth adds Commerce Prompts, while Professional increases User Prompt capacity and adds controlled prompt experiments. [friction AI pricing](https://www.frictionai.co/pricing) starts at $69 per month.
| Decision factor | Scrunch AI | friction AI |
|---|---|---|
| Starting price | $250/mo | $69/mo |
| Core allowance | 125 prompts across 4 LLMs | Tiered daily prompts plus weekly audit |
| Technical visibility | Bot traffic, crawl errors and page audits | Source and content recommendations through Improve |
| Primary strength | AI customer journey and agent experience | Recommendation accuracy and competitor diagnosis |
| Enterprise direction | Nine LLMs, API, SSO and AXP | More prompts, Commerce, experiments and custom programs |
| Team shape | Brand, web and enterprise platform teams | Brand, growth and AEO teams |
### Choose Scrunch AI when
- AI bot traffic and crawl failures need direct observation.
- Page audits are part of the recurring monitoring workflow.
- The team is evaluating a machine-readable delivery layer for AI agents.
- Enterprise API, SSO and multi-workspace requirements are already in scope.
- One platform should connect answer visibility with technical agent behavior.
### Choose friction AI when
- The first question is whether AI recommends the brand in buying situations.
- Recognition, sentiment and purchase intent require a stable weekly benchmark.
- The team wants a prioritized action queue at a lower starting price.
- Daily customer-defined prompts should coexist with a curated audit.
- Commerce questions or controlled positioning tests are likely to follow.
Scrunch is the more technical and infrastructure-oriented product. friction AI is the more specialized reccomendation and decision-diagnosis product. The right choice depends on whether the program owns the agent's visit to the site or the brand's position inside the answer.
## Peec AI: for focused analytics and unlimited users
[Peec AI](https://peec.ai/pricing) starts at $95 per month for 50 prompts, one project, three selected models, unlimited users and daily tracking. Pro and Advanced increase prompt and project capacity, and Enterprise broadens model and integration options.
Peec is the better Scrunch alternative for a team that wants straightforward daily analytics and broad dashboard access without page audits or agent infrastructure. It costs less and its self-serve plans are easier to scope.
Scrunch wins when the technical and page layer matters. Peec wins when the job is focused tracking with a clear prompt allowance and unlimited users.
## Rankscale: for broad engines and flexible cadence
[Rankscale](https://rankscale.ai/pricing) starts at $20 per month and uses credits. It supports hourly, daily, weekly and monthly schedules across ChatGPT, Gemini, Perplexity, Claude, DeepSeek, Mistral, Grok, Copilot and other engines. Features include competitor benchmarking, citations, sentiment, prompt research, shopping analysis and page audits.
Rankscale is the stronger alternative when the buyer wants control over engine mix and cadence at a much lower initial commitment. Scrunch provides a clearer packaged program with 125 Core prompts, audits and crawler features. Rankscale lets the buyer assemble a narrower or more varied run plan.
Do not compare the $20 and $250 prices without using Rankscale's credit calculator. Several engines, daily cadence and many prompts can change the actual monthly requirement.
## Semrush AI Visibility: for SEO integration
[Semrush AI Visibility](https://www.semrush.com/pricing/ai/) costs $99 per month per domain with annual billing. It includes 25 custom prompts, mentions across ChatGPT, Google AI, Gemini and Perplexity, competitor analysis, prompt research and an AI-readiness site audit.
Semrush is the better Scrunch alternative when AI visibility should stay beside keyword research, technical SEO and established reporting. Scrunch is a dedicated AI-search and agent platform with deeper crawler-specific behavior and a different enterprise path.
The decision is less about wich dashboard has more charts and more about who owns remediation. SEO teams may act faster inside Semrush. Web platform and AI-experience teams may get more from Scrunch.
## How to choose a Scrunch alternative
### 1. Separate monitoring from agent delivery
Write two requirements lists. The first covers prompts, models, citations, competitors and trends. The second covers bot traffic, crawl failures, page transformation and delivery. Many teams need the first list but not the second.
### 2. Price technical features separately
Ask what requires Enterprise: full-site audits, additional models, API access, SSO, workspaces and AXP. Compare the monitoring-only price before assigning value to features the team may not deploy.
### 3. Confirm who can implement the recommendation
A content team, SEO team and platform team will choose different tools from the same evidence. Make the owner of the next action part of the product evaluation.
### 4. Audit raw answers and crawl evidence
Visibility scores need underlying responses. Crawl dashboards need server or edge evidence that can be reconciled with existing logs. Request both during the trial.
### 5. Test in parallel
Run the same prompt and market brief in Scrunch and the leading alternative for at least two cycles. Compare brand resolution, citations, recommendations and data availability before comparing the scores.
## Frequently Asked Questions
### What is the best Scrunch AI alternative?
It depends on the job. AthenaHQ fits broad monitoring and content actions. Profound fits larger enterprise intelligence programs. HubSpot AEO fits affordable CRM-connected monitoring. friction AI fits recommendation diagnosis, Peec fits focused daily analytics, Rankscale fits configurable tracking, and Semrush fits established SEO teams.
### Is there a cheaper alternative to Scrunch?
Yes. Rankscale starts at $20, HubSpot AEO at $50, friction AI at $69, Peec at $95, and Semrush AI Visibility and Profound Starter at $99. AthenaHQ has a free plan, though its paid Starter costs $295. None of those entry plans reproduces Scrunch Core's complete combination of 125 prompts, audits, crawler insight and enterprise path.
### How does Scrunch compare with friction AI?
Scrunch connects answer monitoring with page audits, bot traffic and agent delivery. friction AI combines daily User Prompts with a weekly Brand Audit focused on recognition, recommendations, sentiment and purchase intent, then prioritizes actions. Scrunch fits technical AI-customer-experience programs; friction AI fits recommendation measurement and competitor diagnosis.
### What is Scrunch AXP?
Scrunch describes its Agent Experience Platform as a parallel, lightweight version of a site for AI agents. It preserves the human site while serving structured, compressed content intended to be easier for agents to parse. Buyers should evaluate implementation, governance and measurable crawl or citation effects before treating it as a required feature.
### Is Scrunch still a good choice for monitoring alone?
Yes. Core includes 125 prompts across four LLMs, competitor and citation analysis, page audits and five users. It can be a sensible monitoring purchase when that allowance and the technical insights justify $250 per month, even if the team does not deploy AXP immediately.
## Related guides
- [Peec AI Alternatives: 7 Platforms Compared by Use Case](/blog/peec-ai-alternatives)
- [Best AI Visibility Tools Compared 2026](/blog/best-ai-visibility-tools-compared-2026)
- [How to Compare AI Visibility Platforms](/blog/ai-visibility-platform-comparison-2026)
- [Best AEO Platforms 2026](/blog/best-aeo-platforms-2026)
- [Profound Alternatives: 5 Platforms to Evaluate](/blog/profound-ai-alternative-affordable-ai-visibility)
[](https://www.frictionai.co/pricing)
---
# HubSpot AEO Alternatives: 7 Dedicated AI Visibility Tools (2026)
# URL: https://www.frictionai.co/blog/hubspot-aeo-alternatives
# Slug: hubspot-aeo-alternatives
# Category: Tool Comparisons
# Published: 2026-08-02
# Author: Joao Da Silva, Co-Founder of friction AI
# Keywords: hubspot aeo alternatives, hubspot ai visibility alternatives, hubspot aeo review, ai visibility tools, hubspot aeo competitors
HubSpot AEO has a clear entry proposition: 25 prompts, daily tracking across three answer engines and a $50 monthly price without requiring another HubSpot subscription. For Marketing Hub customers, the case becomes stronger because CRM data can inform which buyer prompts deserve attention. A team considering alternatives is usually deciding whether that ecosystem advantage outweighs broader model coverage, more prompts or a more specialized diagnostic workflow.
One disclosure before the comparison: we build friction AI, one of the products below. We link the vendor pages behind volatile pricing claims and do not place friction AI first automatically. HubSpot AEO is the better purchase when its price, CRM context and three-engine scope match the program.
*Last verified: August 3, 2026.*
## TL;DR
- **AthenaHQ** provides a free baseline and a much broader nine-model paid action platform.
- **Rankscale** supports flexible cadence, broad engine choice and credit-based monitoring.
- **Semrush AI Visibility** joins AI visibility with an established SEO toolkit.
- **friction AI** measures recommendations, recognition, sentiment and purchase intent, then prioritizes actions.
- **Peec AI** provides focused daily analytics with 50 prompts and unlimited users at entry.
- **Scrunch AI** adds site audits, crawler observability and enterprise agent delivery.
- **Writesonic** places monitoring beside content planning and production.
HubSpot AEO remains hard to beat for a small daily program, especially when Marketing Hub already holds the customer context. The alternatives become stronger when three models, 25 prompts or HubSpot's workflow are too narrow.
## HubSpot AEO pricing and capabilities at a glance
[HubSpot AEO](https://www.hubspot.com/products/aeo/ai-visibility) costs **$50 per month** after its free trial, or $45 per month with annual payment. The standalone plan includes 25 prompts and daily visibility tracking across ChatGPT, Perplexity and Gemini. It reports a visibility score, competitor share of voice, citation patterns and recommendations. Additional prompt packs are available.
The standalone product does not require a HubSpot subscription. Marketing Hub Professional and Enterprise include premium AEO capabilities, and HubSpot says CRM data can surface prompts tied to actual buyers. That connection is the product's most defensible difference. It is not only another visibility dashboard when the company already runs its marketing and customer data in HubSpot.
### What HubSpot AEO does well
- A low published monthly price for daily monitoring
- A simple allowance of 25 prompts across three major answer engines
- Competitor visibility, share of voice and citation analysis
- No separate HubSpot subscription requirement for the standalone product
- CRM-informed prompt suggestions for eligible Marketing Hub customers
- A familiar buying and reporting environment for existing HubSpot teams
### Why teams consider an alternative
1. **Three engines may not be enough.** Teams tracking Claude, Copilot, Google AI Overviews or other surfaces need another configuration.
2. **Twenty-five prompts can become tight.** Several products begin with 50 or more prompts, or use credits that allow a different mix.
3. **The team may not use HubSpot.** Without CRM and Marketing Hub context, the ecosystem advantage shrinks.
4. **Visibility may be too broad a metric.** Some teams need recommendation accuracy, purchase intent, crawler behavior or page-level technical evidence.
5. **Enterprise requirements vary.** APIs, regions, languages, SSO, raw exports and data retention need to be compared separately.
## Quick comparison
The entry prices below do not buy equivalent answer volume. Normalize prompts, models, regions, frequency, domains and users before deciding.
| Platform | Published entry point | Entry-plan shape | Best fit |
|---|---:|---|---|
| HubSpot AEO | $50/mo | 25 prompts across ChatGPT, Perplexity and Gemini | HubSpot users and compact daily programs |
| AthenaHQ | Free; Starter $295/mo | 300 free credits; Starter has 3,600 credits and 9-model visibility | Broad model coverage and content actions |
| Rankscale | $20/mo | Credit-based monitoring with flexible cadence | Configurable, budget-sensitive monitoring |
| Semrush AI Visibility | $99/mo per domain | 25 prompts plus AI competitor and prompt research | AI visibility inside an SEO stack |
| friction AI | $69/mo | Weekly Brand Audit plus daily User Prompts | Recommendation diagnosis and prioritized actions |
| Peec AI | $95/mo | 50 prompts, choose 3 models, unlimited users | Focused daily analytics |
| Scrunch AI | $250/mo | 125 prompts, 4 LLMs, 5 audits and 5 users | Monitoring plus crawler and site diagnostics |
| Writesonic | $79/mo | 50 tracked prompts plus content workflows | Content planning and production teams |
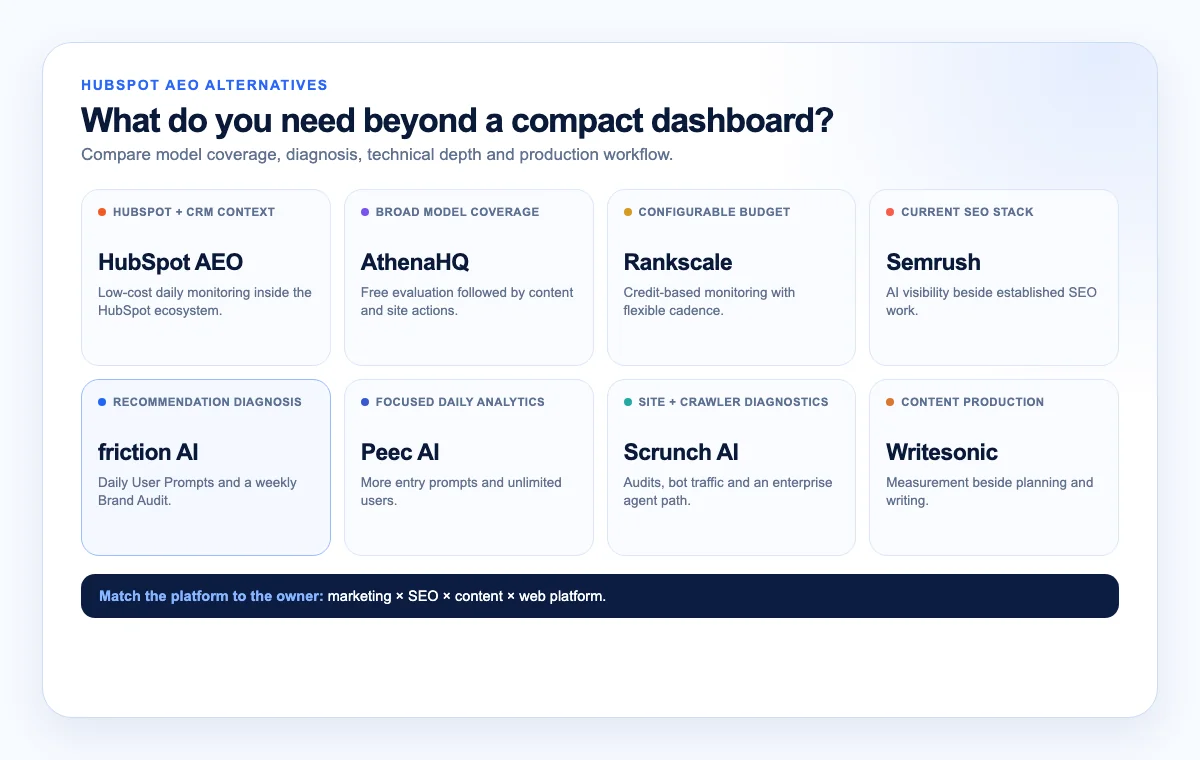
## AthenaHQ: for broader model coverage and actions
[AthenaHQ](https://athenahq.ai/) has a free Essential tier with 300 credits across ChatGPT, Perplexity, Google AI Overviews, Gemini and Claude. Starter costs $295 per month and includes 3,600 credits, nine-model visibility, API access, CSV export, integrations and on-page and off-page actions.
AthenaHQ is the stronger HubSpot AEO alternative when the program needs more answer surfaces or a dedicated action environment. The free plan can also test five surfaces before the team commits to Starter. HubSpot's advantage is price and CRM proximity. Its standalone plan costs much less and has a simpler 25-prompt brief.
Choose AthenaHQ when the wider model set and content action layer are the point of the purchase. Choose HubSpot when ChatGPT, Perplexity and Gemini cover the audience and the team values a compact daily workflow.
## Rankscale: for configuration control
[Rankscale](https://rankscale.ai/pricing) starts at $20 per month and uses credits. Teams can schedule terms hourly, daily, weekly or monthly across a broad engine list that includes ChatGPT, Gemini, Perplexity, Claude, DeepSeek, Mistral, Grok and Copilot. The product includes visibility tracking, competitor benchmarks, citation and sentiment analysis, prompt research and page audits.
Rankscale is the better alternative when the buyer wants to tune engines and cadence instead of accepting HubSpot's fixed three-engine daily package. Its low entry price is attractive, though the final bill depends on credit use and the selected models.
HubSpot is easier when 25 daily prompts are enough and the team wants one fixed monthly price. Rankscale deserves a closer look when the program spans less common engines, several cadences or many regions.
## Semrush AI Visibility: for SEO teams
[Semrush AI Visibility](https://www.semrush.com/pricing/ai/) costs $99 per month per domain with annual billing. It tracks 25 custom prompts and reports mentions from ChatGPT, Google AI, Gemini and Perplexity. Competitor analysis, prompt research and an AI-readiness site audit are included.
Semrush and HubSpot solve the same integration question from different sides. HubSpot connects AI visibility to CRM and marketing operations. Semrush connects it to SEO research, site audits and reporting. A team already working daily in one of those platforms may save more time through ecosystem fit than it gains from a longer standalone feature list.
Semrush covers a Google AI surface in addition to the three named by HubSpot, but it prices per domain and may add user or reporting costs. Compare the whole account, not only the AI add-on.
## HubSpot AEO vs friction AI
HubSpot AEO gives a team a daily visibility layer with a low entry price. It measures whether the brand appears, how it compares with competitors and which sources are cited. Marketing Hub customers can relate that work to there CRM and buyer data.
friction AI starts from recommendation behavior. User Prompts run daily. A separate weekly Brand Audit uses a repeated buying-oriented prompt set to measure recognition, visibility, sentiment and purchase intent against competitors. Improve translates detected gaps into prioritized work. Growth adds Commerce Prompts. Professional raises the User Prompt allowance and adds controlled prompt experiments. The [friction AI pricing page](https://www.frictionai.co/pricing) lists Starter at $69 per month, Growth at $299 and Professional at $699.
| Decision factor | HubSpot AEO | friction AI |
|---|---|---|
| Starting price | $50/mo | $69/mo |
| Included answer surfaces | ChatGPT, Perplexity and Gemini | Five answer surfaces listed across the product |
| Prompt cadence | 25 prompts refreshed daily | Daily User Prompts plus weekly Brand Audit |
| Existing-data advantage | HubSpot CRM and Marketing Hub | Consistent competitor and recommendation diagnostics |
| Primary strength | Affordable visibility in a marketing ecosystem | Measurement-to-action loop for recommendations |
| Higher-tier direction | Marketing Hub features and prompt add-ons | More prompts, Commerce and controlled experiments |
### Choose HubSpot AEO when
- The team already works in HubSpot and wants CRM-informed prompt suggestions.
- Twenty-five daily prompts across three engines cover the initial measurement plan.
- A $50 fixed monthly entry is more useful than a broader diagnostic product.
- Visibility, share of voice and citation analysis are the main requirements.
### Choose friction AI when
- The team needs to separate being mentioned from being recommended.
- Recognition, sentiment and purchase intent need a repeated competitor benchmark.
- Findings should become a prioritized queue rather than a general recommendation feed.
- Commerce visibility or controlled positioning experiments are likely to enter the program.
- The team wants daily custom questions beside a stable weekly brand baseline.
HubSpot has the better ecosystem argument. friction AI has the more specialized recommendation-diagnosis argument. A team centered on inbound marketing and CRM data may get more from HubSpot even when another tool has more AI-specific features.
## Peec AI: for more prompts and unlimited users
[Peec AI](https://peec.ai/pricing) starts at $95 per month with 50 prompts, one project, three selected models, unlimited users and daily tracking. Higher self-serve plans increase prompts and projects, while Enterprise adds the broadest model and integration options.
Peec is the stronger HubSpot alternative when 25 prompts are not enough and many colleagues need access without seat management. Both products offer a focused daily monitoring experience. HubSpot costs less and connects to it's marketing ecosystem; Peec begins with twice the prompt allowance and unlimited users.
The model choice is different rather than simply larger. Peec lets the buyer select three models from its available set. HubSpot fixes the standalone coverage to ChatGPT, Perplexity and Gemini.
## Scrunch AI: for site audits and AI crawlers
[Scrunch AI](https://scrunch.com/faqs/category/pricing/) Core costs $250 per month. It includes 125 prompts, four LLMs, five page audits, one brand workspace and five users. Enterprise expands to nine LLMs and adds full-site audits, SSO, a data API and the Agent Experience Platform, which serves a lightweight machine-readable site experience to AI agents.
Scrunch is the better alternative when the problem extends from answer monitoring into bot traffic, crawl errors, page diagnostics or agent delivery. HubSpot remains the lighter and cheaper tool for marketing teams that primarily want daily visibility and competitor context.
The products can also coexist. HubSpot may own marketing and CRM reporting while Scrunch is evaluated by web, technical SEO or platform teams. Consolidation only helps if the same group owns both jobs.
## Writesonic: for content execution
[Writesonic](https://writesonic.com/pricing) combines AI visibility tracking with content strategy and production. Its entry GEO package has been listed at $79 per month with 50 tracked prompts across ChatGPT, Gemini and Google AI Overviews. Higher tiers expand monitoring and content features.
Writesonic is the stronger alternative when the team wants to move directly from a visibility gap into research, drafting and optimization. HubSpot provides recommendations and CRM context, but it is not primarily an article production platform.
Choose Writesonic when content throughput is the bottleneck. Choose HubSpot when the team cares more about buyer context, marketing operations and a compact visibility dashboard.
## How to choose a HubSpot AEO alternative
### 1. Test whether CRM context changes the prompts
Ask HubSpot to show which prompts came from actual buyer and customer data. If those suggestions are meaningfully better than the team's own prompt research, the ecosystem advantage is real. If not, compare HubSpot as a standalone 25-prompt tracker.
### 2. List the answer surfaces that matter
Do not buy model count for its own sake. Identify where customers ask buying questions and whether Google AI Overviews, Claude, Copilot or other surfaces need seperate measurement.
### 3. Price the next six months
Include prompt add-ons, domains, users, markets, API access and reporting. A low starting price can remain low, but only when the entry plan matches the operating brief.
### 4. Compare raw answers and entity detection
Visibility scores compress many judgment calls. Review the underlying answers, citations and brand matches. A clean 40 percent can be less useful than a messy 30 percent if the first number counts incidental mentions as recommendations.
### 5. Decide who owns the next action
HubSpot, AthenaHQ, friction AI, Scrunch, Semrush and Writesonic send findings into different workflows. Choose the product whose next step belongs to the team that will actually do the work.
## Frequently Asked Questions
### What is the best HubSpot AEO alternative?
It depends on the program. AthenaHQ fits broad model coverage and content actions. Rankscale fits configurable credit-based monitoring. Semrush fits SEO teams. friction AI fits recommendation diagnosis and prioritized work. Peec fits focused daily analytics with more prompts, Scrunch fits crawler programs, and Writesonic fits content production.
### Is HubSpot AEO the cheapest option?
No. Rankscale publishes a $20 starting tier. HubSpot AEO at $50 is still one of the lowest fixed-price daily options in this comparison, below friction AI at $69, Writesonic at $79, Peec at $95, Semrush at $99 per domain, Scrunch at $250 and AthenaHQ Starter at $295. Plan shapes differ substantially.
### How does HubSpot AEO compare with friction AI?
HubSpot AEO tracks 25 prompts daily across ChatGPT, Perplexity and Gemini and connects especially well with HubSpot's customer data. friction AI runs daily User Prompts and a weekly Brand Audit focused on recognition, recommendation visibility, sentiment and purchase intent, then prioritizes improvements. HubSpot fits ecosystem-led monitoring; friction AI fits specialized recommendation diagnosis.
### Do I need Marketing Hub to use HubSpot AEO?
No. HubSpot sells AEO as a standalone product without requiring another HubSpot subscription. Marketing Hub Professional and Enterprise customers receive premium AEO features and the stronger CRM connection.
### Should I replace HubSpot AEO if I need more prompts?
Not automatically. HubSpot sells prompt add-ons, so compare their complete price with a 50-prompt or credit-based alternative first. Switching becomes more compelling when the team also needs different engines, raw evidence, site diagnostics or another action workflow.
## Related guides
- [Peec AI Alternatives: 7 Platforms Compared by Use Case](/blog/peec-ai-alternatives)
- [Best AI Visibility Tools Compared 2026](/blog/best-ai-visibility-tools-compared-2026)
- [How to Compare AI Visibility Platforms](/blog/ai-visibility-platform-comparison-2026)
- [Best AEO Platforms 2026](/blog/best-aeo-platforms-2026)
- [Writesonic AI Visibility Review](/blog/writesonic-ai-visibility-review-geo-features)
[](https://www.frictionai.co/pricing)
---
# AthenaHQ Alternatives: 7 AI Search Platforms Compared (2026)
# URL: https://www.frictionai.co/blog/athenahq-alternatives
# Slug: athenahq-alternatives
# Category: Tool Comparisons
# Published: 2026-08-02
# Author: Joao Da Silva, Co-Founder of friction AI
# Keywords: athenahq alternatives, athenahq competitors, athenahq review, friction ai vs athenahq, ai visibility tools
AthenaHQ covers a lot of ground. The free Essential plan gives a team a real way to inspect prompts, responses, citations and competitors before paying. Starter then expands into nine-model monitoring, exports, integrations and content actions. A team looking elsewhere is usually not rejecting that product. It is deciding that a different billing unit, workflow or level of specialization fits better.
One disclosure before the comparison: we build friction AI, one of the products below. We link to the vendor pages behind pricing and plan claims, and friction AI is not ranked first by default. AthenaHQ is the better purchase for several of the use cases in this guide.
*Last verified: August 3, 2026.*

## TL;DR
- **HubSpot AEO** is the lower-cost choice for teams that want daily monitoring tied to HubSpot customer data.
- **Rankscale** offers a flexible credit model, wide engine coverage and a low published entry price.
- **Peec AI** is a focused daily analytics product with unlimited users on self-serve brand plans.
- **friction AI** is built around recommendation accuracy, competitor diagnosis and a prioritized action queue.
- **Scrunch AI** combines monitoring with crawler observability, page audits and enterprise agent delivery.
- **Semrush AI Visibility** fits teams that already work inside Semrush.
- **Writesonic** puts visibility data next to content planning and production.
AthenaHQ remains the stronger fit when a free baseline, a broad paid action layer and nine-model coverage in one plan matter more than the alternatives' narrower strengths.
## AthenaHQ pricing and capabilities at a glance
AthenaHQ's [current plans](https://athenahq.ai/) start with Essential at no charge. It includes 300 credits across ChatGPT, Perplexity, Google AI Overviews, Gemini and Claude, plus unlimited members, prompt and response analysis, source and competitor insights, content recommendations and the Athena agent.
Starter costs **$295 per month**. It includes 3,600 credits and visibility across nine models, with API access, CSV export, integrations, on-page and off-page actions, a content optimization agent and self-learning content improvement. AthenaHQ defines one credit as one AI response. Enterprise pricing is custom and adds governance, multi-region and multilingual support, persona targeting, BI support and other controls.
That credit definition matters. A prompt tested across several models, regions or personas consumes several responses. Normalize the intended run plan before comparing AthenaHQ's credits with another vendor's prompts or monthly checks.
### What AthenaHQ does well
- A usable free entry point rather than a read-only demo
- Five AI surfaces on Essential and nine-model visibility on Starter
- Unlimited members on the free plan
- Prompt, response, citation and competitor analysis in one workspace
- An action layer that extends into content recommendations and optimization
- Enterprise controls for multilingual, multi-region and executive reporting programs
### Why teams consider an alternative
1. **The paid jump is substantial.** A free workspace is useful, but the next published tier is $295 per month.
2. **Credits can be hard to forecast.** Response-based billing changes with the number of models, prompts and checks.
3. **The team may need a narrower tool.** A focused tracker can be easier to operate when content actions and enterprise modules are not part of the brief.
4. **The existing stack may decide the workflow.** HubSpot, Semrush and Writesonic reduce handoffs for teams already committed to those platforms.
5. **The measurement question may be different.** Some teams care most about recommendation accuracy, purchase intent, crawler behavior or a simple share-of-voice trend.
## Quick comparison
Entry prices are not directly equivalent. The products count prompts, responses, models, domains, users and refreshes differently.
| Platform | Published entry point | Entry-plan shape | Best fit |
|---|---:|---|---|
| AthenaHQ | Free; Starter $295/mo | 300 free credits; Starter has 3,600 credits and 9-model visibility | Free evaluation followed by a broad action platform |
| HubSpot AEO | $50/mo | 25 prompts across ChatGPT, Perplexity and Gemini | HubSpot users and low-cost daily monitoring |
| Rankscale | $20/mo | Credit-based monitoring with flexible cadence and broad engine choice | Budget-sensitive teams that want configuration control |
| Peec AI | $95/mo | 50 prompts, choose 3 models, unlimited users | Focused daily analytics and broad team access |
| friction AI | $69/mo | Weekly Brand Audit plus daily User Prompts | Recommendation diagnosis and prioritized actions |
| Scrunch AI | $250/mo | 125 prompts, 4 LLMs, 5 audits and 5 users | Monitoring plus site and crawler diagnostics |
| Semrush AI Visibility | $99/mo per domain | 25 custom prompts and AI research inside Semrush | Existing Semrush teams |
| Writesonic | $79/mo | 50 tracked prompts plus content workflows | Content teams that want measurement near production |

## HubSpot AEO: for a HubSpot-connected workflow
[HubSpot AEO](https://www.hubspot.com/products/aeo/ai-visibility) costs $50 per month for 25 prompts across ChatGPT, Perplexity and Gemini, or $45 per month when paid annually. It refreshes daily and includes visibility, competitor share of voice, citation analysis and recommendations. A HubSpot subscription is not required. Marketing Hub Professional and Enterprise customers receive AEO features inside their existing plan, with CRM data informing prompt suggestions.
That makes HubSpot the practical AthenaHQ alternative when the team wants a smaller daily program, already depends on Marketing Hub, or wants customer data closer to prompt selection. AthenaHQ covers more answer surfaces at its paid tier and has a more explicit content-action and enterprise AEO product.
Choose HubSpot when three engines and 25 prompts cover the initial brief. Choose AthenaHQ when the broader model set, response analysis and dedicated action environment justify the higher spend.
## Rankscale: for flexible credits and broad engine choice
[Rankscale](https://rankscale.ai/pricing) starts at $20 per month. Its monitoring uses credits, and the product lets teams schedule search terms hourly, daily, weekly or monthly. The engine list includes ChatGPT, Gemini, Perplexity, Claude, DeepSeek, Mistral, Grok, Copilot and other surfaces. Its feature set includes visibility trends, competitor benchmarking, citations, sentiment, prompt research and page audits, with higher plans adding collaboration and data access.
Rankscale is the stronger option when the buyer wants to tune cadence and engine mix closely, start with a smaller commitment or run many regions without buying a broad action suite. AthenaHQ is easier to understand when the priority is a guided workflow from monitoring into on-page and off-page actions.
Credits still need normalization. Rankscale charges different fractions for different engines, while AthenaHQ describes one credit as one response. Price the intended prompt, model and cadence combination in both calculators.
## Peec AI: for focused daily analytics
[Peec AI](https://peec.ai/pricing) starts at $95 per month for 50 prompts, one project, three selected models and unlimited users. Its self-serve brand plans run daily. Pro and Advanced increase prompt and project limits, while Enterprise expands model choice, projects, API access and controls.
Peec is a sensible alternative when the team wants a clean analytics product and many internal users, but does not need AthenaHQ's broader action tooling. Its prompt-based plan is also easier for some teams to explain internally than a response-credit budget.
AthenaHQ has the advantage when five free surfaces or nine paid models matter, or when content recommendations and optimization are central. Peec has the cleaner proposition for focused daily tracking with a defined prompt allowance.
## AthenaHQ vs friction AI
AthenaHQ and friction AI both connect measurement to action, but they begin with different questions.
AthenaHQ tracks prompt and response performance across a broad model set. Its paid product adds on-page and off-page actions, content optimization and enterprise modules. The credit system lets a team shape a large program, but the budget moves with response volume.
friction AI separates recurring measurement into two layers. User Prompts run daily for the questions a team chooses. The weekly Brand Audit measures recognition, visibility, sentiment and purchase intent against competitors with a consistent prompt set. Improve converts detected gaps into prioritized work. Growth adds Commerce Prompts, and Professional increases User Prompt capacity and adds controlled prompt experiments. Current prices are listed on the [friction AI pricing page](https://www.frictionai.co/pricing).
| Decision factor | AthenaHQ | friction AI |
|---|---|---|
| Starting point | Free Essential plan | $69/mo with a 7-day trial |
| Paid self-serve step | Starter at $295/mo | Growth at $299/mo after Starter |
| Billing unit | Response credits | Tiered prompt and analysis allowances |
| Scheduled measurement | Prompt and response monitoring | Daily User Prompts plus weekly Brand Audit |
| Primary strength | Broad model coverage and content action layer | Recommendation diagnostics and prioritized work |
| Higher-tier direction | Governance, regions, personas and BI | More prompts, Commerce and controlled experiments |
### Choose AthenaHQ when
- A permanent free workspace is important for the initial evaluation.
- Nine-model visibility is needed in the first paid tier.
- The team wants content recommendations and optimization inside the same AEO environment.
- Multi-region, multilingual, persona or executive reporting requirements point toward an enterprise rollout.
### Choose friction AI when
- The team needs to distinguish mentions from actual recommendations.
- Recognition, sentiment and purchase intent belong in the recurring benchmark.
- A prioritized action queue matters more than a broad content agent.
- Daily custom prompts should sit beside a consistent weekly competitor audit.
- Shopping analysis or controlled positioning experiments are likely to follow.
AthenaHQ is not an overpriced version of friction AI, and friction AI is not a smaller AthenaHQ. AthenaHQ sells broad model coverage and an expanding action platform. friction AI is organized around repeated reccomendation measurement, diagnosis and testing.
## Scrunch AI: for crawler and agent visibility
[Scrunch AI](https://scrunch.com/faqs/category/pricing/) charges $250 per month for Core. That plan includes 125 unique prompts, five page audits per month, one brand workspace, five users and coverage across ChatGPT, Perplexity, Google AI Overviews and Microsoft Copilot. Enterprise expands to nine models and adds full-site audits, SSO, a data API and Scrunch's Agent Experience Platform.
Scrunch is the better alternative when the program includes bot traffic, crawl errors, page audits or serving a parallel machine-readable experience to AI agents. AthenaHQ offers broader model coverage on Starter and a different style of content action. Scrunch extends further into how agents access the site itself.
The comparison turns on ownership. A search or content team may prefer AthenaHQ's action environment. A web platform team dealing with crawler behavior and agent delivery may prefer Scrunch.
## Semrush AI Visibility: for an established SEO stack
[Semrush AI Visibility](https://www.semrush.com/pricing/ai/) costs $99 per month per domain when billed annually. It tracks 25 custom prompts and reports mentions across ChatGPT, Google AI, Gemini and Perplexity. The package also includes competitor analysis, prompt research and an AI-readiness site audit.
Semrush is the straightforward AthenaHQ alternative for an SEO team that already uses its keyword, competitor, audit and reporting products. The data stays in a familiar system and can be compared with traditional search work. AthenaHQ is more appropriate when AI search is its own operating discipline and nine-model coverage or dedicated content actions matter.
Watch the complete configuration. Semrush prices the AI Visibility package per domain and charges separately for some users and reports. AthenaHQ's cost changes with response credits and enterprise requirements.
## Writesonic: for content production teams
[Writesonic](https://writesonic.com/pricing) combines AI visibility with content strategy and production. Its entry GEO package has been listed at $79 per month for 50 tracked prompts across ChatGPT, Gemini and Google AI Overviews, with higher tiers expanding monitoring and content capabilities.
Writesonic is the stronger alternative when the same people research, draft and optimize content. AthenaHQ also offers content recommendations and optimization, but its product is centered on AI-search monitoring and action rather than a broad writing environment.
Choose Writesonic when reducing handoffs into production is the main requirement. Choose AthenaHQ when the team wants a dedicated AEO command center with broader model coverage and an enterprise path.
## How to choose an AthenaHQ alternative
### 1. Convert every plan into responses
Write down prompts, models, markets and checks per month. Multiply them. This exposes whether a credit plan, prompt plan or per-domain price is actually cheaper for the intended program.
### 2. Decide where action should happen
Some teams want recommendations in the monitoring product. Others want tickets, content drafts, page audits, experiments or data exports into an existing system. The best tool is often the one that ends at the right handoff.
### 3. Separate model count from useful coverage
Nine models look better than three, but only if the additional surfaces matter to the audience. Test where customers actually ask buying questions before paying for the widest list.
### 4. Inspect raw responses
Do not compare only the headline visiblity score. Check whether the platform resolves the correct brand, separates recommendations from incidental mentions and preserves enough raw evidence to audit the metric.
### 5. Run two products in parallel
Use the same prompt brief for at least two reporting cycles. The products will use different model versions, locations and scoring rules. Parallel evidence is more useful than trying to splice two unrelated scores into one trend line.
## Frequently Asked Questions
### What is the best AthenaHQ alternative?
It depends on the operating need. HubSpot AEO fits a smaller HubSpot-connected program. Rankscale fits flexible, credit-based monitoring. Peec fits focused daily analytics. friction AI fits recommendation diagnosis and prioritized actions. Scrunch fits crawler and agent programs. Semrush fits established SEO teams, and Writesonic fits content production workflows.
### Is there a cheaper alternative to AthenaHQ?
Yes. HubSpot AEO starts at $50 per month, Rankscale at $20, friction AI at $69, Writesonic at $79, Peec at $95 and Semrush AI Visibility at $99 per domain. Those plans do not reproduce AthenaHQ Starter's nine-model coverage or 3,600-credit allowance, so compare the full run plan rather than the sticker price.
### How does AthenaHQ compare with friction AI?
AthenaHQ has a free tier and a broad paid platform with nine-model visibility, response credits and content actions. friction AI combines daily User Prompts with a weekly Brand Audit, recommendation diagnostics, prioritized improvements and higher-tier Commerce and experiments. AthenaHQ fits broad AEO operations; friction AI fits teams focused on how consistently AI recommends the brand and what to fix next.
### Is AthenaHQ still a good choice?
Yes. AthenaHQ is a strong choice when the free evaluation is useful, the first paid program needs broad model coverage, and content recommendations or enterprise AEO controls belong in the same platform. Alternatives become more attractive when price, existing-stack integration or a narrower diagnostic workflow matters more.
### Can AthenaHQ data be compared directly with another platform?
Not safely from headline scores alone. Each vendor uses its own prompts, model versions, locations, schedules and entity rules. Export the rawest evidence available and run both tools in parallel before treating a new score as a continuation of AthenaHQ history.
## Related guides
- [Peec AI Alternatives: 7 Platforms Compared by Use Case](/blog/peec-ai-alternatives)
- [Best AI Visibility Tools Compared 2026](/blog/best-ai-visibility-tools-compared-2026)
- [How to Compare AI Visibility Platforms](/blog/ai-visibility-platform-comparison-2026)
- [Best AEO Platforms 2026](/blog/best-aeo-platforms-2026)
- [Profound Alternatives: 5 Platforms to Evaluate](/blog/profound-ai-alternative-affordable-ai-visibility)
[](https://www.frictionai.co/pricing)
---
# Peec AI Alternatives: 7 Platforms Compared by Use Case (2026)
# URL: https://www.frictionai.co/blog/peec-ai-alternatives
# Slug: peec-ai-alternatives
# Category: Tool Comparisons
# Published: 2026-08-02
# Author: Joao Da Silva, Co-Founder of friction AI
# Keywords: peec ai alternatives, peec ai competitors, friction ai vs peec, peec ai review, ai visibility tools
Peec AI is good at what it does. Its self-serve plans include daily tracking, unlimited users and a clean way to compare brand visibility across selected AI models. Most teams looking elsewhere are not rejecting Peec wholesale. They usually need one thing packaged differently: more models on the entry plan, a clearer path from measurement to action, a lower starting price, or AI visibility inside an existing SEO or content workflow.
One disclosure before the comparison: we build friction AI, one of the products below. We have linked the vendor pages behind the volatile pricing claims, and we do not rank friction AI first by default. There are several situations where Peec is the more sensible purchase.
*Last verified: August 2, 2026.*
## TL;DR
- **AthenaHQ** has a free entry point and a broader paid action platform.
- **Scrunch AI** combines monitoring with site audits and enterprise agent tooling.
- **Writesonic** joins AI visibility with content planning and production.
- **friction AI** is for recommendation measurement, competitor diagnosis and prioritized actions.
- **Semrush AI Visibility** is the natural fit for teams already using Semrush.
- **Profound** has a broader enterprise product suite.
- **Otterly AI** has the lowest published starting price.
Peec remains a strong choice for teams that value unlimited users, daily tracking and a focused analytics experience.
## Peec AI pricing and capabilities at a glance
Peec's public brand plans start at **$95 per month** for 50 prompts, one project and a choice of three models. Pro increases that to 150 prompts and two projects for $245 per month. Advanced includes 350 prompts and five projects for $495 per month. All three list unlimited users and daily tracking. Enterprise adds custom prompt tracking, API access, SSO, unlimited projects and access to as many as 11 models.
Peec also sells additional-model add-ons. That matters when comparing prices: the entry price is not necessarily the price of the final model mix you want. See [Peec's current pricing page](https://peec.ai/pricing) before making a budget decision.
### What Peec does well
- Unlimited users on its self-serve brand plans
- Daily prompt tracking
- Clear prompt and project allowances
- Model selection rather than paying for an undifferentiated bundle
- Country and language support without a separate regional price
- Agency plans and enterprise controls for larger deployments
### Why teams consider an alternative
The most common reason is not that Peec is bad. It is that its packaging does not match the job.
1. **You need more than three models on a self-serve plan.** Peec lets you add models, but the total cost changes with the plan and prompt volume.
2. **You need a different action layer.** Monitoring identifies visibility gaps. Some teams want content workflows, experiments, site remediation or a more prescriptive list of next steps in the same product.
3. **You already pay for an adjacent platform.** Semrush and Writesonic can be easier to justify when the team already uses their SEO or content tooling.
4. **You need a different operating model.** A free baseline, a lower entry price or a more enterprise-heavy implementation can matter more than a nominal feature count.
## Quick comparison
Entry prices are not directly equivalent. Prompt definitions, model coverage, markets, refresh cadence, users and exports vary by vendor.
| Platform | Published entry point | Entry-plan shape | Best fit |
|---|---:|---|---|
| Peec AI | $95/mo | 50 prompts, choose 3 models, unlimited users | Focused daily analytics with a polished self-serve workflow |
| AthenaHQ | Free; Starter $295/mo | 300 free credits; Starter includes 3,600 credits and 9 models | Free evaluation or a broader action platform |
| Scrunch AI | $250/mo | 125 prompts, 4 AI platforms, 1 workspace, 5 users | Brand teams that want monitoring plus site audits |
| Writesonic | $79/mo | 50 tracked prompts across ChatGPT, Gemini and Google AI Overviews | Content teams joining visibility and production workflows |
| friction AI | $69/mo | Weekly Brand Audit plus daily User Prompts | Recommendation accuracy, competitor diagnostics and prioritized actions |
| Semrush AI Visibility | $99/mo per domain | 25 custom prompts plus competitor and prompt research | Existing Semrush users and combined SEO/AI analysis |
| Profound | $99/mo billed annually | 50 prompts on ChatGPT at Starter | Teams evaluating a broader enterprise product path |
| Otterly AI | $29/mo | Lightweight multi-platform monitoring | Lowest-cost starting point |
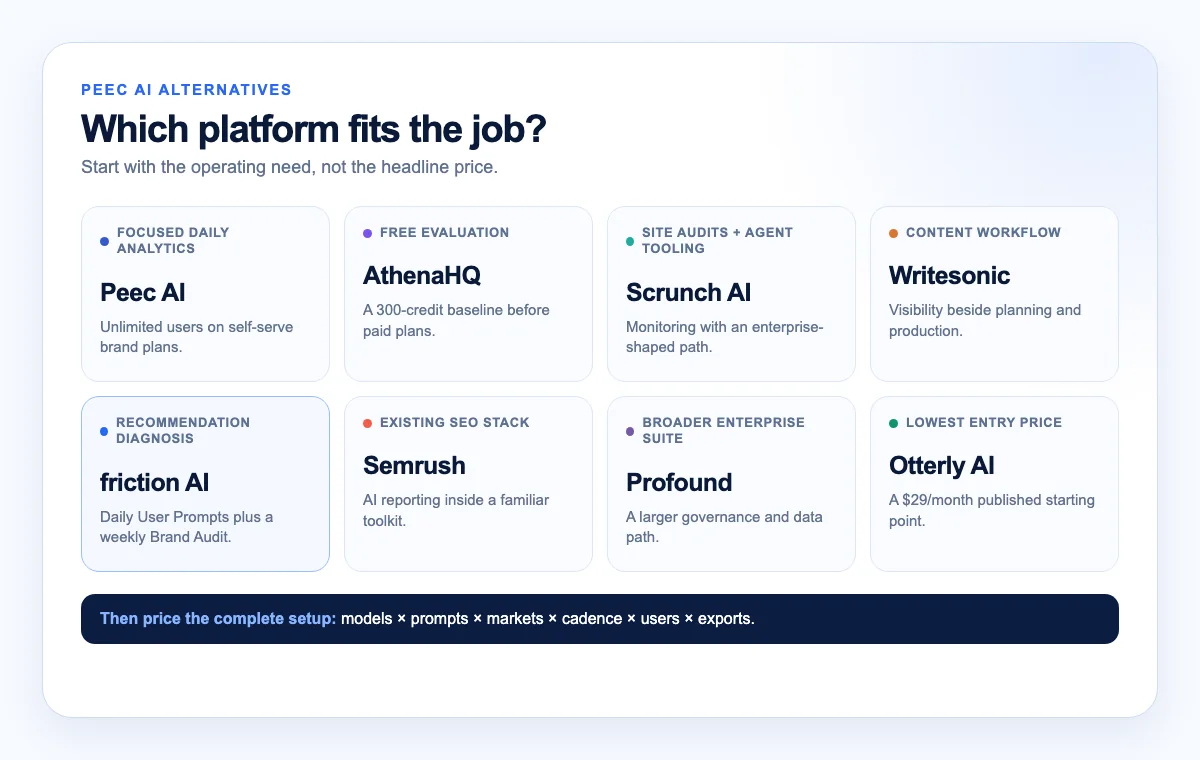
## AthenaHQ: a free baseline and credit-based action platform
AthenaHQ's Essential tier is free and includes 300 credits across ChatGPT, Perplexity, Google AI Overviews, Gemini and Claude. It also lists unlimited members, prompt and response analysis, source and competitor insights, content recommendations and its AI agent.
Starter costs $295 per month and includes 3,600 credits, visibility across nine models, API access, CSV export, integrations, on-page and off-page actions, and content optimization. Enterprise adds multi-region and multilingual support, governance controls and white-glove setup. Athena defines one credit as one AI response. See [AthenaHQ plans](https://athenahq.ai/plans) for the current limits.
Athena is the better shortlist candidate when a free initial workspace matters, when response-based credits make more sense to your team, or when you want monitoring and content actions together. Peec is easier to justify if you prefer prompt allowances, want a lower paid entry point than Athena Starter, and do not need the broader action platform.
## Scrunch AI: for larger brand and agent-experience programs
Scrunch Core costs $250 per month. It includes 125 unique prompts, four AI platforms, five site audits per month, one brand workspace and five user licenses. The supported Core platforms are ChatGPT, Perplexity, Google AI Overviews and Microsoft Copilot.
Scrunch Enterprise expands model coverage and adds API access, integrations, SSO, larger audits and its Agent Experience Platform. That creates a different path from Peec: Scrunch can move from monitoring into how AI agents consume and interact with a site. The trade-off is a higher starting price and a more enterprise-shaped product. See [Scrunch pricing](https://scrunch.com/pricing/) for current details.
Scrunch belongs on the shortlist when site audits, enterprise integrations and agent-experience infrastructure are central requirements. Peec is the simpler buy when you want lower-cost self-serve analytics, unlimited users and more prompt capacity before an enterprise procurement process.
## Writesonic: for content teams
Writesonic combines AI visibility tracking with content strategy, an SEO and Content AI Agent, and article production. Its Starter plan is listed at $79 per month and tracks 50 prompts daily across ChatGPT, Gemini and Google AI Overviews. Higher tiers expand the visibility and action features.
This is less a pure replacement decision and more a workflow decision. If the team already plans and produces content in Writesonic, keeping visibility signals close to production can reduce handoffs. If the team wants a dedicated measurement product, Peec's narrower focus may be preferable. See [Writesonic pricing](https://writesonic.com/pricing) for its current SEO and GEO plan matrix.
For a content team already using Writesonic, that integration may decide the comparison. Peec makes more sense when independent tracking and competitive analytics matter more than producing content in the same platform.
## Peec AI vs friction AI
Peec AI and friction AI overlap on scheduled AI visibility tracking, competitor analysis and brand performance reporting. The practical difference is what each product treats as the end of the workflow.
Peec is analytics-led. Its self-serve plans make prompt volume, projects, model selection and daily tracking easy to understand. Unlimited users are valuable for marketing teams that want broad dashboard access without assigning seats carefully.
friction AI puts more weight on repeated recommendation measurement and diagnosis. Its weekly Brand Audit evaluates recognition, visibility, sentiment and purchase intent against competitors. User Prompts run daily, while Improve turns detected gaps into prioritized actions. Growth adds shopping-prompt tracking. Professional increases the User Prompt allowance and adds controlled prompt experiments. Current plan details are on the [friction AI pricing page](https://www.frictionai.co/pricing).
| Decision factor | Peec AI | friction AI |
|---|---|---|
| Starting price | $95/mo | $69/mo |
| Entry-plan model structure | Choose 3 models | Five answer surfaces listed across the product |
| Scheduled measurement | Daily tracking | Weekly Brand Audit plus daily User Prompts |
| Team access | Unlimited users on self-serve brand plans | Tiered team plans |
| Primary strength | Focused analytics and share-of-voice tracking | Recommendation diagnostics and prioritized actions |
| Higher-tier direction | More prompts, projects, integrations and enterprise controls | More User Prompts, Shopping analysis and controlled prompt experiments |
### Choose Peec AI when
- Unlimited seats are important from the first paid tier.
- You want daily tracking with a clear prompt allowance.
- Choosing three core models is enough for your initial measurement plan.
- Your team wants a focused analytics product without adopting a broader experimentation workflow.
### Choose friction AI when
- You care about whether AI recommends the brand, not only whether it mentions it.
- Competitor substitution, recognition and purchase intent are part of the measurement brief.
- You want findings translated into a prioritized improvement queue.
- Shopping prompts, a larger User Prompt allowance or controlled messaging experiments are likely to become part of the program.
Neither product is universally better. Peec has the cleaner proposition for teams centered on daily monitoring and broad internal access. friction AI is the better fit when the measurement program needs diagnosis, action prioritization and experiments around how the brand is recommended.
## Semrush AI Visibility: for existing Semrush users
Semrush sells its AI Visibility toolkit for $99 per month per domain when billed annually. It includes 25 custom prompts, AI competitor analysis, prompt research, AI-readiness checks and visiblity reporting across ChatGPT, Google AI, Gemini and Perplexity.
The advantage is ecosystem fit. SEO teams can relate AI visibility to familiar keyword, competitor, audit and reporting workflows. The constraint is packaging: one domain, a smaller custom-prompt allowance and additional costs for more domains, users or prompts. See [Semrush AI Visibility pricing](https://www.semrush.com/pricing/ai/) for the current plan.
Semrush is the practical choice when the team already lives there and wants AI data in the same environment. Peec has the cleaner package when AI-search tracking is the primary requirement and the team wants 50 prompts plus unlimited users at the starting tier.
## Profound: for a broader enterprise evaluation
Profound's public Starter plan costs $99 per month billed annually and tracks 50 prompts on ChatGPT. Growth costs $399 per month billed annually and broadens the model coverage. Enterprise adds Profound's wider analytics and governance product set.
Profound and Peec therefore serve different buying motions. Peec offers a direct self-serve path with unlimited users and a choice of models. Profound is relevant when the evaluation includes its broader enterprise products, datasets and implementation model. Check [Profound pricing](https://www.tryprofound.com/pricing) for current plan limits.
For a deeper post-decision shortlist, read [Profound Alternatives: 5 Platforms to Evaluate](/blog/profound-ai-alternative-affordable-ai-visibility).
## Otterly AI: for the lowest-cost starting point
[Otterly AI](https://otterly.ai/) starts at $29 per month. Its lower entry price makes it suitable for teams establishing a basic AI visibility baseline before committing to a larger prompt set. The trade-off is that meaningful monitoring across more prompts, workspaces or advanced workflows can require a higher plan or add-ons.
Otterly wins on the size of the initial commitment. Peec is a better fit when 50 prompts, unlimited users and a clearer path into larger daily tracking programs matter more.
For a full evaluation, read [Best Otterly AI Alternative for AI Brand Monitoring](/blog/otterly-ai-alternative-ai-brand-monitoring).
## How to choose the right Peec AI alternative
Use the same normalized brief for every demo. Otherwise, vendors with different billing units will appear comparable when they are not.
### 1. Define the answer volume
Write down the number of prompts, models, countries and refreshes you actually need. A prompt tracked daily across five models is not equivalent to one response credit or a prompt checked weekly on one model.
### 2. Separate monitoring from action
Decide whether the product only needs to report visibility or must also prioritize changes, create content, test positioning, audit the site or connect results to other systems.
### 3. Price the complete configuration
Include model add-ons, domains, users, markets, exports and integrations. Entry prices are useful only when the entry plan matches the intended program.
### 4. Run tools in parallel before switching
Different products use different prompts, model versions, locations and scoring methods. Run the old and new systems together for at least two reporting cycles. Compare raw responses and brand-detection accuracy before comparing headline scores.
### 5. Keep the history you may need
Export prompts, raw responses, competitor definitions and time-series data before cancelling a tool. Historical scores often cannot be recreated becuase the underlying model response has already changed.
## Frequently Asked Questions
### What is the best Peec AI alternative?
It depends on the job. AthenaHQ fits a free baseline or credit-based action platform. Scrunch fits enterprise monitoring and site-audit programs. Writesonic fits content teams. friction AI fits recommendation diagnostics and prioritized actions. Semrush fits existing SEO workflows, Profound fits broader enterprise evaluations, and Otterly offers the lowest-cost entry point.
### Is friction AI cheaper than Peec AI?
At the published starting price, yes: friction AI starts at $69 per month and Peec starts at $95 per month. The plans are not identical, so compare model coverage, prompt volume, cadence, users and higher-tier features before deciding from price alone.
### How does Peec AI compare with friction AI?
Peec emphasizes daily analytics, selected-model tracking and unlimited users. friction AI combines daily User Prompts with a weekly Brand Audit, competitor diagnostics, prioritized improvements, higher-tier prompt allowances, Shopping prompts and controlled experiments. Peec is a strong fit for focused monitoring; friction AI fits teams that want a wider measurement-to-action loop.
### Is Peec AI still a good choice?
Yes. Peec is a credible choice when 50 or more prompts, daily tracking, unlimited users and a focused analytics experience match the team's requirements. Looking at alternatives is about operating fit, not declaring Peec ineffective.
### Can I preserve my Peec AI history when switching?
You can export the data Peec makes available, but another platform will calculate its own metrics from its own prompt runs. Keep the rawest export available and run both products in parallel before treating the new series as continuous with the old one.
## Related guides
- [Best AI Visibility Tools Compared 2026](/blog/best-ai-visibility-tools-compared-2026)
- [How to Compare AI Visibility Platforms](/blog/ai-visibility-platform-comparison-2026)
- [Best AEO Platforms 2026](/blog/best-aeo-platforms-2026)
- [Profound Alternatives: 5 Platforms to Evaluate](/blog/profound-ai-alternative-affordable-ai-visibility)
- [Best Otterly AI Alternative](/blog/otterly-ai-alternative-ai-brand-monitoring)
[](https://www.frictionai.co/pricing)
---
# The Coverage Gap: Why Your Own Website Barely Moves AI Recommendations
# URL: https://www.frictionai.co/blog/the-coverage-gap
# Slug: the-coverage-gap
# Category: Original Research
# Published: 2026-06-06
# Author: Joao da Silva
# Keywords: AI Visibility, Coverage Gap, Answer Engine Optimization, Digital PR, Brand Strategy, Citations
# The Coverage Gap: Why Your Own Website Barely Moves AI Recommendations
By Joao da Silva and Maryanna Franco (BrilliantSEO) · June 6, 2026
> **TL;DR.** On recommendation queries ("best [category] brands?"), a brand's own website is **0-3% of the sources AI cites**, topping out at 2.8%. Recommendation runs almost entirely on **earned third-party coverage** in your category. lululemon has **3,736** third-party citations behind its recommendations; New Balance has **144**. We call that distance the **Coverage Gap**, and you can see it most clearly when it's total: when New Balance does get cited for athleisure, the sources are dictionaries.
When New Balance turns up in an athleisure answer at all, look at what the model cites. Merriam-Webster. Cambridge. Collins. The AI, with no real athleisure content about New Balance to pull from, falls back to looking up what the words "new balance" mean. It's an empty drawer, on display.
That's the tell for the last and most expensive mechanism in the recognition-recommendation gap: the **Coverage Gap**, the distance between what you publish about yourself and what AI actually cites when it recommends. This is the fifth piece in the [Beyond KG Strength](/blog/brand-strength-recognized-not-recommended) series, and it's the one that redirects the most marketing budget.
## What the Coverage Gap is
The Coverage Gap is the gap between your owned content and your earned coverage, as AI sees it. Most brands pour effort into the first (their website, their blog, their product pages) and assume that's what makes them visible. For reccomendation queries, it barely registers. What registers is the second: independent third-party content in your category that an AI can retrieve and cite.
The reason is structural, not a quirk. A "best [category]?" question is comparative. Your own site cannot answer "is X better than Y?", it only ever argues for X. So the model reaches for sources that *can* compare: category round-ups, comparison articles, publications, listicles. If those exist about you, you surface.
If they don't, you don't, no matter how good your website is.
## Your own site barely counts (for recommendations)
The numbers are blunt. On recommendation queries, the brand's own domain is **0-3% of all citations**, with the single highest being 2.8% (Reebok). Across the board, AI almost never cites your homepage when it's deciding what to recommend.
This flips on recognition queries. Ask "what is [brand]?" and your own site jumps to the dominant source, 49% of citations on ChatGPT, 36% on Perplexity, 23% on Claude, 21% on AI Overview, 13% on Gemini. Same brand, same site, two completely different roles. Your website is your most-quoted document when someone already typed your name. It's nearly irrelevant when they didn't.
That split is the strategic core of this whole series: recognition runs on your own pages, recommendation runs on third-party coverage in your category. Optimizing the wrong one is the most common AI-visiblity mistake we see.
## The Coverage Gap, brand by brand
The amount of earned coverage behind each brand varies enormously, and it tracks recommendation almost perfectly. This is the gap made visible.
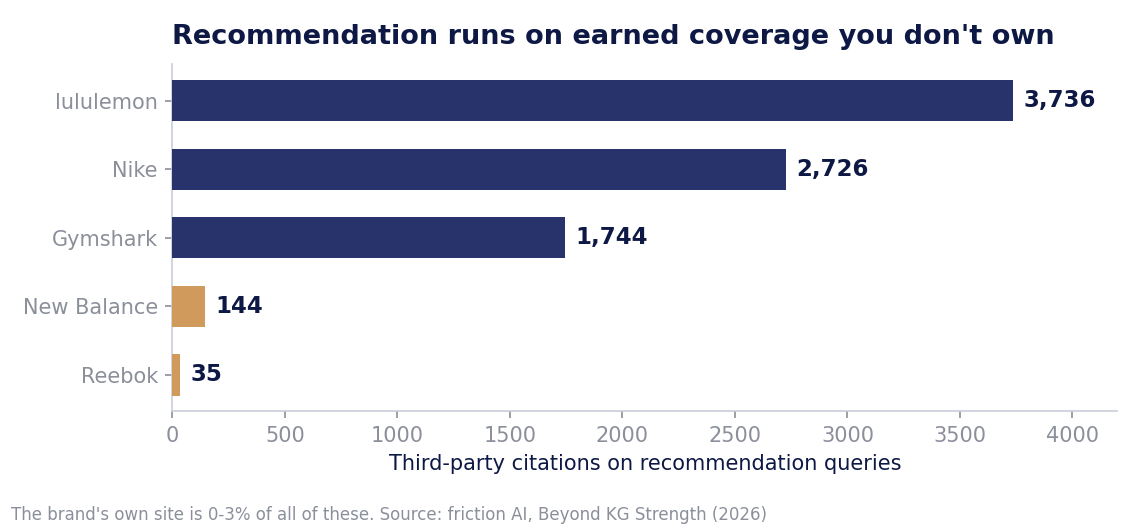
lululemon has 3,736 independent sources behind its recommendations. New Balance has 144, and Reebok 35. Gymshark, a low-Knowledge-Graph brand, has 1,744, far more than New Balance, which is the strongest brand in the sample by KG score. Earned coverage, not brand strength, is what fills the drawer the model opens.
## The dictionary tell
The clearest diagnostic in the whole study is what an AI cites when your coverage is *zero*. For New Balance in athleisure, the cited sources are dominated by dictionary sites: merriam-webster.com, dictionary.cambridge.org, collinsdictionary.com. There is no body of third-party athleisure content about New Balance to retrieve, so the model does the only thing it can and looks up the phrase.
If you ever see AI citing generic reference sites, dictionaries, definition pages, Wikipedia disambiguation, when it talks about your brand in a category, that's the signature of a Coverage Gap. The model isn't choosing those sources. It's settling for them becuase nothing better exists.
## A note on where the coverage lives
Earned coverage isn't one thing, and the engines don't all read the same sources. Each has a citation personality: Gemini and AI Overview lean on shopping listicles and Wikipedia, Perplexity on brand domains and Instagram, Claude on company-research databases and LinkedIn. So a placement strategy that only targets one publication type reaches only some of the engines. Spread earned coverage across category publications, comparison and listicle sites, and the reference sources each engine trusts.
## What to do: close the gap
1. **Stop optimizing your own site for category visibility.** It's 0-3% of recommendation citations. Keep your site sharp for *recognition* (your entity description, your About page), but don't expect it to win "best [category]" answers.
2. **Invest in earned coverage in your category.** The sources AI cites are category round-ups, comparisons, publications, and listicles. Getting written about in those, alongside the [category prototype](/blog/category-prototype), is what surfaces you.
3. **Measure corroboration density, not output.** The metric that matters is how many independent third-party sources reproduce your positioning, not how much content you publish or how many inbound links you count. lululemon doesn't dominate because it has the highest KG score (it doesn't); it dominates because it has the deepest earned coverage in athleisure.
4. **Spread placements across engines.** Match the citation personalities above so you're not visible to only one model.
This is the last of five mechanisms behind the recognition-recommendation gap. The full picture, and the other four, are in the pillar: [Brand Strength Gets You Recognized, Not Recommended](/blog/brand-strength-recognized-not-recommended). For a broader catalog of why AI overlooks brands, see [Why AI Ignores Your Brand](/blog/why-ai-ignores-your-brand-blindspots).
## FAQ
**Does my website matter for AI visibility?**
For recognition, yes, it's the dominant source when someone asks "what is [brand]?" (up to 49% of citations). For recommendation ("best [category]?"), almost not at all: your own domain is 0-3% of cited sources. The two surfaces need different work.
**What is the Coverage Gap?**
The distance between the content you own and the earned third-party coverage AI actually cites when it recommends brands. Recommendation runs on independent category coverage; if you don't have it, you don't surface.
**What is the "dictionary tell"?**
When AI cites dictionaries or generic reference pages for your brand in a category, it's a sign there's no real third-party content about you in that category. New Balance's athleisure citations are dominated by dictionary sites, the signature of a total Coverage Gap.
**How do I close the Coverage Gap?**
Earn third-party coverage in your category, round-ups, comparisons, listicles, and publications, especially content that names you alongside the category leader. Measure corroboration density (independent sources reproducing your positioning), not your own content output or raw link counts.
---
*Part of the [Beyond KG Strength](https://www.frictionai.co/white-papers/beyond-kg-strength) series (Franco & da Silva, 2026, [DOI: 10.5281/zenodo.20331344](https://doi.org/10.5281/zenodo.20331344)). Pillar: [Brand Strength Gets You Recognized, Not Recommended](/blog/brand-strength-recognized-not-recommended). Previous: [Bridge Brands and Sub-Stream Strength](/blog/bridge-brands-sub-stream-strength).*
---
# Bridge Brands and Sub-Stream Strength: How Nike Crosses a Wall New Balance Can't
# URL: https://www.frictionai.co/blog/bridge-brands-sub-stream-strength
# Slug: bridge-brands-sub-stream-strength
# Category: Original Research
# Published: 2026-06-06
# Author: Joao da Silva
# Keywords: AI Visibility, Sub-Stream Strength, Bridge Brands, Answer Engine Optimization, Brand Strategy, Category Expansion
# Bridge Brands and Sub-Stream Strength: How Nike Crosses a Wall New Balance Can't
By Joao da Silva and Maryanna Franco (BrilliantSEO) · June 6, 2026
> **TL;DR.** AI files both Nike and New Balance as footwear. Yet Nike gets recommended for athleisure **71.8%** of the time and New Balance **3.4%**, with Reebok (also footwear-coded) at **0.7%**. Same category code, opposite outcomes. The difference is not brand strength (New Balance actually has the higher Knowledge Graph score). It's **Sub-Stream Strength**: Nike has a deep body of *apparel* coverage that puts it in the athleisure conversation (co-mentioned with lululemon 482 times, versus 21 for New Balance). You can bridge into an adjacent category, but only by building density there, not by relabeling yourself.
Most of this series is about why brands stay stuck in one box. This piece is about the exception: the rare brand that crosses into a neighboring category and gets recommended there anyway. Nike is that brand in our data, and how it does it is the most useful playbook for anyone trying to expand.
This is the fourth mechanism in the [Beyond KG Strength](/blog/brand-strength-recognized-not-recommended) series. [Category Coding](/blog/category-coding-how-ai-sorts-your-brand) explained the box; [the Category Prototype](/blog/category-prototype) explained the cluster. This is about crossing from one cluster into the next.
## What a Bridge Brand is
A **Bridge Brand** is a brand AI files in one category that still surfaces strongly in an adjacent one. In our athleisure study, the footwear-coded brands (Nike, New Balance, Reebok) should all have been invisible on athleisure queries, the way Category Coding predicts. Two of them were. Nike wasn't. It bridged.
Nike is the only footwear-coded brand in our set that crosses the wall. That makes it the test case for a precise question: what does a brand need to surface in a category it isn't filed under?
## Same category code, opposite outcomes
Start with the outcome. All three brands carry a footwear-flavored Knowledge Graph description and all three are coded as athletic footwear by every model. Their athleisure recommendation rates could not be more different.
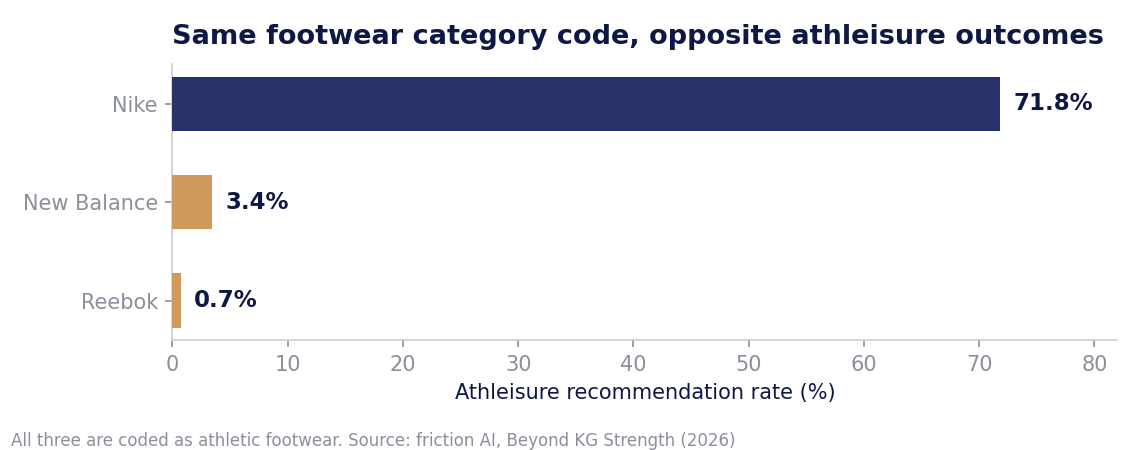
If category code alone decided this, all three would be near zero. If brand strength decided it, New Balance would lead, it has the highest Knowledge Graph score in the entire sample, about 2.5 times Nike's. Neither explains the result. Something else is doing the work.
## What Nike has that New Balance doesn't
The thing Nike has is a deep **apparel sub-stream**: decades of third-party content about Nike clothing, sportswear, leggings, and training apparel, not just shoes.
That coverage places Nike inside the athleisure cluster. New Balance's apparel coverage is a thin layer on top of a footwear brand; the third-party web mostly writes about its shoes.
You can see the gap in co-mention density. Nike is named alongside lululemon, the athleisure prototype, **482** times across recommendation answers. New Balance is named with lululemon **21** times. Nike is a member of the athleisure conversation. New Balance is a footwear brand that occasionally wanders past it.
We call this depth **Sub-Stream Strength**: the volume and density of category-aligned third-party content you have *in the target category*, as distinct from your overall brand strength or your primary-category authority. It's category-specific. Nike has huge sub-stream strength in apparel and even more in footwear. New Balance has it in footwear and almost none in apparel. The KG score doesn't see that split. The recommendation behavior does.
## You can't bridge by relabeling
The tempting move, once you see this, is to try to change your category: rebrand, update your messaging, tell the market you're an athleisure company now. It doesn't work, for the same reason [Outdoor Voices can't out-market its category code](/blog/category-coding-how-ai-sorts-your-brand). The category you surface in is set by the third-party content written about you, not by what you call yourself.
Brand strength doesn't transfer across the boundary either. Across all 12 brands, Knowledge Graph strength correlated with the recognition-recommendation gap at -0.10, statistically zero. Strength buys you recognition and durability in your home category; it doesn't buy you a seat in the next category over. Only sub-stream density does that, and density has to be built where you want to show up.
That's the hard truth of bridging: its the slowest of the five mechanisms to move. Nike's apparel sub-stream is the product of decades. But it's also the most durable, because once you're genuinely in the adjacent cluster, the same compounding that protects the prototype starts working for you.
## How does a brand become a bridge? (a hypothesis)
Here is the honest limit of the data. Our study is a snapshot: it shows that Nike *has* a deep apparel sub-stream and bridges, and that New Balance doesn't and doesn't. It does not show *how* Nike got there, the path over time, or the threshold it had to cross. Nike is also the only bridge brand in our 12-brand set. So treat what follows as a hypothesis, not a measured finding.
We think becoming a bridge brand takes five things, in roughly this order:
1. **Real product participation.** Nike actually makes apparel at scale. You can't manufacture third-party coverage for a category you don't operate in, so this is the precondition, and it isn't a marketing lever.
2. **Sustained category-aligned coverage.** Independent content in the target category that repeatedly names you alongside that category's brands, above all it's prototype.
3. **A density threshold.** Below it, your adjacent-category coverage reads as noise against your primary code; above it, the model treats it as a separate signal. Where that line sits, we don't yet know.
4. **Compounding.** Once your in enough lists you get into more, the same dynamic that protects the prototype. Slow at first, then self-reinforcing.
5. **Adjacency.** Nike crossed between two neighboring categories. A jump into a distant one likely needs much more, and we didn't test that.
Confirming this needs work we haven't done: tracking a brand's sub-stream and recommendation rate over time, across many brands, to see what actually predicts who bridges. It's the priority follow-up.
## How to build a sub-stream
If that hypothesis is right, the work is concrete:
1. **Confirm the target cluster is real.** Run the [Category Prototype](/blog/category-prototype) mapping on the category you want to enter. Identify its prototype and co-anchors. That's the company you need to be cited alongside.
2. **Earn category-aligned third-party coverage there.** Get featured in the target category's publications, round-ups, and comparisons, the content that already co-mentions its established brands. This is the [Coverage Gap](/blog/the-coverage-gap) mechanism applied with intent: build the corpus that positions you in the new category.
3. **Be consistent and patient.** Sub-stream strength accumulates; it doesn't spike. One placement won't move it. A sustained stream of category-aligned coverage, over quarters and years, is what eventually registers as cluster membership.
4. **Don't rebrand to fake it.** Messaging follows coverage, not the other way around. Spend on getting written about in the target category, not on telling people you belong there.
This is one of five mechanisms behind the recognition-recommendation gap. The full picture is in the pillar: [Brand Strength Gets You Recognized, Not Recommended](/blog/brand-strength-recognized-not-recommended).
## FAQ
**What is a Bridge Brand?**
A brand that AI files in one category but still gets recommended strongly in an adjacent one. Nike is footwear-coded yet earns 71.8% of athleisure recommendations, the only footwear brand in our study to cross over.
**What is Sub-Stream Strength?**
The volume and density of category-aligned third-party content a brand has *in a specific category*, separate from its overall brand strength. Nike has deep apparel sub-stream strength; New Balance has almost none, which is why Nike bridges into athleisure and New Balance doesn't.
**Why does Nike bridge into athleisure but New Balance can't, with the same KG description?**
Because bridging depends on sub-stream density, not Knowledge Graph strength. Nike has decades of apparel coverage (co-mentioned with lululemon 482 times); New Balance's apparel coverage is thin (21 co-mentions). New Balance actually has the higher KG score, which proves strength isn't the lever.
**Can I bridge into a new category by rebranding?**
No. Category surfacing is set by third-party content, not self-description. You bridge by earning sustained coverage in the target category, which takes time, not by relabeling yourself.
---
*Part of the [Beyond KG Strength](https://www.frictionai.co/white-papers/beyond-kg-strength) series (Franco & da Silva, 2026, [DOI: 10.5281/zenodo.20331344](https://doi.org/10.5281/zenodo.20331344)). Pillar: [Brand Strength Gets You Recognized, Not Recommended](/blog/brand-strength-recognized-not-recommended). Previous: [The Category Prototype](/blog/category-prototype).*
---
# The Category Prototype: The Brand AI Thinks Defines Your Category
# URL: https://www.frictionai.co/blog/category-prototype
# Slug: category-prototype
# Category: Original Research
# Published: 2026-06-06
# Author: Joao da Silva
# Keywords: AI Visibility, Category Prototype, Answer Engine Optimization, Brand Strategy, Co-occurrence, Generative Engine Optimization
# The Category Prototype: The Brand AI Thinks Defines Your Category
By Joao da Silva and Maryanna Franco (BrilliantSEO) · June 6, 2026
> **TL;DR.** A category isn't a flat list to an AI. It's a cluster of brands that get mentioned together, with one brand at the dead center. We call that center the **Category Prototype**. For athleisure it's lululemon: named first in most answers (average position **1.64**) and co-mentioned with Alo Yoga **534** times, Nike **482**, Gymshark **264**. New Balance co-occurs with lululemon **21** times, an unconnected node outside the cluster. To get recommended, you don't have to beat the prototype. You have to enter its cluster.
When an AI answers "what are the best athleisure brands?", it isn't reading down a ranked list. It's pulling from a dense web of brands that tend to appear together in the content it learned from. That web has a shape, and at the middle of it sits one brand the model treats as the definition of the category. Everything else is positioned by how close it sits to that center.
This is the third mechanism in the [Beyond KG Strength](/blog/brand-strength-recognized-not-recommended) series. [Category Coding](/blog/category-coding-how-ai-sorts-your-brand) decides which cluster you belong to. This piece is about your position *inside* the cluster once you're in it, and why the brand at the center has such a gravitational pull.
## What a Category Prototype is
A Category Prototype is teh single brand an AI treats as most representative of a category. It's the one that comes to mind first, gets named first, and anchors the list everything else hangs off. In cognitive terms it's the same idea as "robin" being the prototype for "bird": when you think of the category, you think of that member.
For athleisure, lululemon is unmistakably the prototype, and the data shows it two different ways: it's named more than any other brand, and it's named *first*.
## The cluster has one brand at its center
The clearest signal is co-occurrence: when the models recommend brands together, who appears alongside whom. lululemon sits at the center of a tight cluster. The brands that share the athleisure box co-occur with it constantly. The footwear-coded brands don't.

Alo Yoga is named with lululemon 534 times. New Balance, the strongest brand in our whole sample by Knowledge Graph score, co-occurs with it 21 times. That's the difference between being in the cluster and being a node floating outside it. New Balance isn't competing with lululemon for athleisure recommendations. As far as the models are concerned, it isn't in the conversation at all.
## The prototype gets named first
Co-occurrence shows who's in the cluster. Position shows who's at the center. We measured the average ordinal position at which each brand appears in reccomendation answers, where 1 means it was the first brand named. lululemon's average is **1.64**: in most responses where it appears, it's named first or second. Nothing else is close.

Being named first isn't a vanity metric. The order brands appear in an AI answer is the order a buyer reads them, and the first name carries disproportionate weight. The prototype gets that slot by default, every time the category comes up.
## The category AI sees is bigger than your competitive set
Here's the part that reframes how you think about competitors. The models don't restrict themselves to the obvious names. Our extractor captured more than 260 distinct brands across recommendation answers, and two we never put in the study outranked most of the ones we did: **Athleta (74% of recommendation runs)** and **Vuori (71%)** were each mentioned more often than 9 of our 12 target brands (study dashboard).
These two sit between Alo Yoga and Nike on both mention rate and position. They are co-anchors of the cluster, and most brand teams wouldn't list them first if you asked who lululemon's competitors are. The lesson: the category AI recommends from is wider and more specific than the competitive set in your deck. Before you try to enter a cluster, you have to know who AI thinks is actually in it.
## How to enter the cluster
You don't dislodge the prototype. lululemon's position is the product of years of accumulated coverage, and chasing it head-on is a losing game. What you can do is become a recognized member of the cluster, the way Athleta and Vuori are. Three steps:
1. **Map the real cluster.** Run several "best [category]" prompts across ChatGPT, Gemini, Claude, and Perplexity. Write down every brand named and the order. That list, not your competitive deck, is the cluster AI sees. Note who's named first (the prototype) and whether you appear at all.
2. **Measure your distance from the center.** Search the third-party web for content that names the prototype, listicles, comparisons, "brands like [prototype]" round-ups. Are you in those pieces? Co-mention with the prototype in independent content is what puts you in the cluster.
3. **Earn co-mention, not self-mention.** The way in is getting placed alongside the category leader in content you don't own: category round-ups, comparison articles, lifestyle and trade publications. This is the same mechanism behind [The Coverage Gap](/blog/the-coverage-gap), recommendation runs on third-party coverage, and the bridging move in [Sub-Stream Strength](/blog/bridge-brands-sub-stream-strength).
The prototype defines the category. Your job is to get close enough to it, in the eyes of the content AI reads, that you're part of the same answer.
Start with the pillar for the full picture: [Brand Strength Gets You Recognized, Not Recommended](/blog/brand-strength-recognized-not-recommended).
## FAQ
**What is a Category Prototype?**
It's the single brand an AI treats as most representative of a category, the one named first and most often when the category comes up. For athleisure it's lululemon, with an average mention position of 1.64.
**Why does the first brand named matter?**
AI answers are read top to bottom, so the first brand carries the most weight with the buyer.
The prototype occupies that slot by default whenever the category is queried, wich compounds its advantage over time.
**How do I get my brand into the category cluster?**
Earn third-party content that co-mentions you alongside the prototype: category round-ups, comparisons, and "brands like [leader]" articles. Co-mention in content you don't own, not your own website, is what AI reads as cluster membership.
**Who decides which brands are in my category?**
The published web does, and it may not match your competitor list. In our athleisure data, Athleta and Vuori outranked most pre-registered brands despite not being in our set. Map the cluster with live prompts before assuming you know it.
---
*Part of the [Beyond KG Strength](https://www.frictionai.co/white-papers/beyond-kg-strength) series (Franco & da Silva, 2026, [DOI: 10.5281/zenodo.20331344](https://doi.org/10.5281/zenodo.20331344)). Pillar: [Brand Strength Gets You Recognized, Not Recommended](/blog/brand-strength-recognized-not-recommended). Previous: [The KG-Hijacked Entity](/blog/kg-hijacked-entity).*
---
# The KG-Hijacked Entity: When AI Confuses Your Brand With a Bigger Namesake
# URL: https://www.frictionai.co/blog/kg-hijacked-entity
# Slug: kg-hijacked-entity
# Category: Original Research
# Published: 2026-06-06
# Author: Joao da Silva
# Keywords: AI Visibility, Knowledge Graph, Entity Disambiguation, Answer Engine Optimization, Brand Strategy, Entity Recognition
# The KG-Hijacked Entity: When AI Confuses Your Brand With a Bigger Namesake
By Joao da Silva and Maryanna Franco (BrilliantSEO) · June 6, 2026
> **TL;DR.** If a larger company shares your name, its Knowledge Graph entry can sit on top of yours, and AI ends up describing the wrong company or skipping you altogether. In our study, TALA, a UK athleisure brand, had a Google Knowledge Graph description that reads **"Financial services company"** (that's a same-named fintech). The result: TALA was recognized at **0.32** when every other brand sat near 0.99, and it earned **0% athleisure recommendations**. This isn't a content problem. The fix is a Knowledge Graph disambiguation request.
Most of the recognition-recommendation gap is about which category box AI files you in. This one is worse: AI has the wrong company in the box with your name on it.
We call it a **KG-Hijacked Entity**: your brand shares a name with a larger entity, Google's Knowledge Graph resolves that name to the other one, and every downstream AI inherits the confusion. It's the most damaging failure mode we found, because it breaks the foundation, recognition, that every other layer is built on. This is part of the [Beyond KG Strength](/blog/brand-strength-recognized-not-recommended) series; if Category Coding is about being in the wrong box, this is about the box belonging to someone else.
## What a KG-Hijacked Entity is
When an AI answers a question about a brand, it leans on a structured entity record, and Google's Knowledge Graph is the most influential one. Each entity carries a short free-text description ("Apparel company," "Footwear company," and so on). When two companies share a name, the Knowledge Graph resolves that name to a single entity, usually the larger or older one.
The smaller brand doesn't get a weaker version of its own entry. It effectively doesn't have one. Its name points somewhere else.
That's the hijack. Note the word is just shorthand: nobody did anything wrong. Both companies legitimately exist and both have a real claim to the name. Mechanically, though, the Knowledge Graph only resolves to one, and AI follows it.
## TALA: invisible in its own category
TALA is a UK athleisure brand. Its Google Knowledge Graph description reads, verbatim, **"Financial services company,"** because a larger Philippines-based fintech of the same name owns the entity. The numbers that follow from that are stark:
- **Recognition: 0.32.** Across our 12 brands, every other brand except one sat at 0.99 or higher. Ask an AI "what is TALA?" and it frequently describes the fintech, or hedges, because the entity it resolves to isn't the apparel brand.
- **Athleisure recommendation: 0%.** The lowest in the sample. TALA never surfaces when someone asks for the best athleisure brands.
What makes this especially frustrating: when we probed the models directly ("is TALA an athleisure brand?"), they could place it correctly. The knowledge exists somewhere. But the *default* resolution, the one that fires on an unprompted query, lands on the fintech. The brand is doing the marketing; the namesake is collecting the entity.
## It breaks recognition, not just recommendation
Every other mechanism in this series operates at the recommendation layer, the brand is known but not surfaced. The KG hijack is worse because it corrupts recognition itself. You can see it in the sources AI cites for the name. The fintech's domain (`tala.co`) shows up far more than the athleisure brand's actual domain (`wearetala.com`).
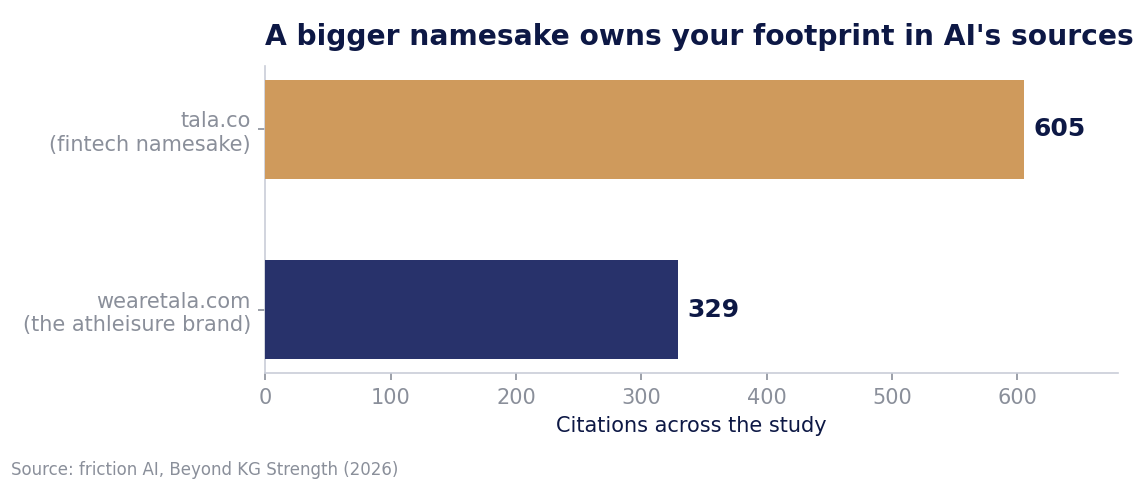
When the most-cited source for your brand name is a different company, no amount of athleisure content fixes the underlying problem. AI isn't failing to find good content about you. It's resolving your name to someone else before it even looks.
## How to tell if you're hijacked
This one is quick to diagnose:
1. **Read your knowledge panel.** Search your brand on Google. If the knowledge panel (or the one-line descriptor under your name) shows a different company, a different industry, or a different country, your name is resolving to another entity.
2. **Probe recognition.** Ask ChatGPT, Gemini, Claude, and Perplexity "what is [your brand]?" If any of them confidently describe a different company, the hijack is live at the recognition layer, which is the one that matters most.
3. **Check the cited domain.** When AI does mention your name, see which domain it cites. If it's not yours, a same-named entity owns your footprint.
A hijack looks different from ordinary weak recognition. A small brand with no Knowledge Graph entry gets vague, hedged answers. A hijacked brand gets confident, detailed answers about the *wrong company*. Confidence plus wrongness is the tell.
## The fix: a Knowledge Graph disambiguation request
This is the rare AI-visiblity problem you don't solve with more content. You solve it by getting Google to recognize your brand as a distinct entity. Two parts:
**File for disambiguation.** Google has a process for suggesting corrections to knowledge panels and for claiming an entity you represent. For an entirely missing or misattributed entity, this means establishing your brand as its own node, not editing the namesake's. Set expectations honestly: this is **slow (often months) and not guaranteed**. Knowledge Graph corrections propagate on Google's timeline, and AI models pick them up only on later training or retrieval cycles.
**Strengthen your own entity signals so Google can tell you apart.** This is the work that makes the disambiguation stick: clean `schema.org` `Organization` markup with a `sameAs` block linking your verified profiles (LinkedIn, Crunchbase, your social accounts), a Wikidata entry, consistent name-and-location signals across the web, and ideally independent coverage that names you with enough context to separate you from the namesake. The more uniquely-identifying structured data points to your real domain, the easier it is for Google, and then for AI, to resolve your name to you.
Until that resolves, paid and organic marketing both leak value: you build demand for a name that AI hands to someone else. The disambiguation request is the unlock that lets every other layer (category coding, coverage, recommendation) start working.
This is one of five mechanisms behind the recognition-recommendation gap. Start with the pillar, [Brand Strength Gets You Recognized, Not Recommended](/blog/brand-strength-recognized-not-recommended), and see the box-assignment mechanism in [Category Coding](/blog/category-coding-how-ai-sorts-your-brand).
## FAQ
**What is a KG-Hijacked Entity?**
It's when your brand shares a name with a larger company, and Google's Knowledge Graph resolves that shared name to the other entity. AI then describes the wrong company or skips you, becuase it has no distinct record for your brand.
**How do I know if my brand is hijacked in AI?**
Search your brand and read the knowledge panel, then ask the major AI models "what is [brand]?" If they confidently describe a different company, or your knowledge panel shows the wrong industry, your name is resolving to a namesake. Confident-but-wrong answers are the signature.
**Can I fix a Knowledge Graph hijack with content or SEO?**
Not directly. Content helps category coverage, but a hijack is an entity-resolution problem. The fix is a Knowledge Graph disambiguation request plus stronger entity signals (schema.org sameAs, Wikidata, consistent identifiers) so Google can distinguish you from the namesake.
**How long does it take to fix?**
Expect months, and there's no guarantee. Knowledge Graph corrections move on Google's schedule, and AI systems only reflect them after later retrieval or training cycles. Strengthening your structured-data signals in parallel improves the odds.
---
*Part of the [Beyond KG Strength](https://www.frictionai.co/white-papers/beyond-kg-strength) series (Franco & da Silva, 2026, [DOI: 10.5281/zenodo.20331344](https://doi.org/10.5281/zenodo.20331344)). Pillar: [Brand Strength Gets You Recognized, Not Recommended](/blog/brand-strength-recognized-not-recommended). Previous: [Category Coding](/blog/category-coding-how-ai-sorts-your-brand).*
---
# Category Coding: How AI Sorts Your Brand Before It Recommends You
# URL: https://www.frictionai.co/blog/category-coding-how-ai-sorts-your-brand
# Slug: category-coding-how-ai-sorts-your-brand
# Category: Original Research
# Published: 2026-06-06
# Author: Joao da Silva
# Keywords: AI Visibility, Category Coding, Answer Engine Optimization, Knowledge Graph, Entity Recognition, Brand Strategy
# Category Coding: How AI Sorts Your Brand Before It Recommends You
By Joao da Silva and Maryanna Franco (BrilliantSEO) · June 6, 2026
> **TL;DR.** Before an AI decides whether to recommend you, it has already decided *what you are*. We call this **Category Coding**: every model carries one internal category label for your brand, and a "best [category]?" query only considers the brands inside that box. The labels are remarkably consistent: across ChatGPT, Gemini, Claude, Perplexity, and Google AI Overview, **9 of our 12 brands were coded into the same category by all five**. If the box is wrong, you are invisible in that category no matter how much you spend on marketing.
An AI recommendation query has a hidden first step. Ask "what are the best athleisure brands?" and before the model picks anything, it filters to the brands it has filed under "athleisure." Everything else is invisible to that question. The filtering happens silently, and most brands never learn which box they are in.
This is the first of five mechanisms behind the recognition-recommendation gap we measured across 14,140 AI answers. The full reframe is in the pillar, [Brand Strength Gets You Recognized, Not Recommended](/blog/brand-strength-recognized-not-recommended). This piece is about the box itself: how AI assigns it, how consistent it is, and how to find yours.
## What Category Coding is
Category Coding is the internal category label an AI attaches to your brand. It isn't something you set, and it is not always what you think you are. It is what the model inferred from everything written about you, compressed into a single answer to "what kind of company is this?"
You can ask the models directly, and they will tell you. We probed all five with a forced-choice prompt ("categorize this brand into one of: athletic footwear, athleisure apparel, performance sportswear, yoga and wellness"). The answers were not mushy. They were specific, confident, and overwhelmingly consistent across models.
## The models agree on your category
This is the part that surprised us most. **9 of the 12 brands came back unanimous**, all five models the same, or four with one naming a near-synonym. The five systems don't just share facts about brands. They share the same mental filing cabinet, and that filing cabinet acts like a cage.
Where the models disagreed, the disagreement was itself predictive:
- **Gymshark** split 2-2 between sportswear and athleisure. Its real-world athleisure recommendation rate landed right in the middle, at 40.5%. A brand the models can't agree on gets recommended at an in-between rate.
- **lululemon** came back 3 of 4 athleisure, 1 of 4 yoga (Claude), reflecting its yoga heritage inside the broader athleisure box.
- **Alo Yoga** was the mirror image: 3 of 4 yoga, 1 of 4 athleisure.
The practical takeaway: your category code is **consistent across models and queryable in one prompt**. You don't have to guess. And because it's shared across the major systems, fixing it (or being stuck with it) affects all of them at once.
## You can't out-market your category code
The hardest version of this lesson is Outdoor Voices. It built its whole identity as *the* athleisure brand, the pioneer of "Doing Things" in matching sets. The models didn't get the memo. They code it **28% athleisure and 81% sportswear**, and they recommend it accordingly: it shows up far more for sportswear questions than athleisure ones.
That gap between how a brand markets itself and how AI files it is the thing to internalize. Your category code is set by the published web (what third parties write about you, in which contexts), not by your campaigns or your homepage copy. You can run athleisure ads all year; if the corpus of writing about you reads "sportswear," that's the box you're in.
## Proof: change the category, change the brands
The cleanest demonstration that category is the gate, not strength, is to hold everything constant and swap only the category register of the prompt. We did this in a small follow-up: same brands, same model, same day, but asking for the best *athletic footwear* brands instead of the best *athleisure* brands.
The pattern flipped completely. New Balance, near-invisible on athleisure (about 1%), jumped to roughly 90% on footwear. lululemon, the athleisure prototype at about 90%, dropped to 0% on footwear. The brands didn't change. The box the question opened did.
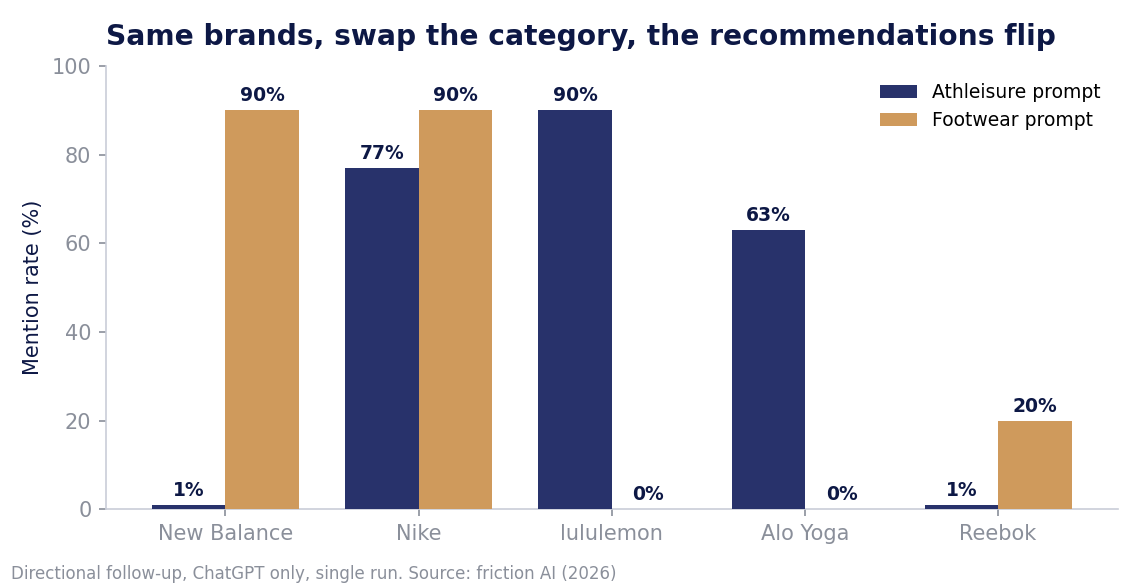
A caveat worth stating plainly: this flip experiment was a single run on one model (ChatGPT) and is not part of the main 14,140-run dataset. Treat it as a direction, not a measured result. It lines up with the rest of the study, but it hasn't been run at scale yet.
## Where your category code comes from
Here is the honest version of the mechanism, including the part that's easy to oversimplify.
The cleanest *single* signal we found is the **Google Knowledge Graph short-description field**, the one-line "X company" descriptor Google attaches to your entity. The categories the models assigned lined up with it closely:
| KG short-description | Example brands | AI category |
|---|---|---|
| "Footwear company" | Nike, New Balance | athletic footwear |
| "Sporting goods company" | Reebok | athletic footwear |
| "Apparel company" | lululemon, Alo Yoga | athleisure / yoga |
| "Fashion company" | Outdoor Voices | athleisure (partial) |
| "Financial services company" | TALA | wrong entity entirely |
| generic "Company" / none | Gymshark, Rhone, Varley, LNDR | no clear anchor |
But the description is a **proxy, not the cause**. Nike, New Balance, and Reebok all carry footwear-flavored descriptions, yet they behave completely differently in recommendations (Nike crosses into athleisure; New Balance and Reebok don't). So the label can't be the whole story. The actual driver is the **distribution of third-party content about you**: what fraction of the writing the models learned from positions you in wich category. The KG description and the AI's category both descend from that same upstream signal.
The description is just the most legible readout of it.
That distinction matters for what you do next. The description tells you your *diagnosis*. The *fix* lives in the third-party corpus, which is the subject of two later pieces in this series: [Sub-Stream Strength](/blog/bridge-brands-sub-stream-strength) (how Nike built enough apparel coverage to cross the boundary) and [The Coverage Gap](/blog/the-coverage-gap) (why earned third-party coverage, not your own site, is what moves recommendations).
And when the description points at the *wrong entity* entirely, like TALA's "Financial services company," you have a different problem with a different fix. That's the [KG-Hijacked Entity](/blog/kg-hijacked-entity), covered next.
## How to find your category code
You can run this today, in two steps:
1. **Probe the models.** Ask each of ChatGPT, Gemini, Claude, and Perplexity the same forced-choice question: *"In one label, what category does [your brand] belong to? Choose the single best fit."* Run it a few times per model. Agreement across models is your category code. Disagreement is a signal you sit on a boundary (like Gymshark), which usually means a middling recommendation rate.
2. **Check your Knowledge Graph description.** Search your brand on Google and read the one-line descriptor in the knowledge panel, or query the Knowledge Graph entry directly. If it reads as the wrong category, or as generic "Company," or as a different entity, that's your diagnosis. A wrong or missing description is a structural cap on your category recommendations.
If your category code is correct but you still don't surface, the problem is downstream (coverage density, covered later). If your category code is *wrong*, fix that first. Nothing else moves until the box is right.
This is one of five mechanisms. Start with the pillar for the full picture: [Brand Strength Gets You Recognized, Not Recommended](/blog/brand-strength-recognized-not-recommended). For a broader catalog of ways AI overlooks brands, see [Why AI Ignores Your Brand](/blog/why-ai-ignores-your-brand-blindspots).
## FAQ
**What is Category Coding?**
It's the single internal category an AI model assigns to your brand. A "best [category]?" recommendation query only considers brands inside that category, so your code determines which questions you can even appear for.
**How do I find what category AI puts my brand in?**
Ask each major model the same forced-choice question ("what one category does [brand] belong to?") and check your Google Knowledge Graph short-description. Models agree most of the time (9 of 12 brands in our study were unanimous), so one round of probes usually reveals it.
**Can I change my category code with marketing?**
Not directly. Outdoor Voices marketed itself as athleisure for years and is still coded 81% sportswear. Category coding follows the third-party content written about you, not your own campaigns or website.
**Is the Knowledge Graph description the cause of my category?**
It's the cleanest proxy, not the root cause. Nike, New Balance, and Reebok share footwear-style descriptions but behave differently, becuase the real driver is the distribution of third-party content about each brand. Use the description to diagnose; fix the underlying coverage.
---
*Part of the [Beyond KG Strength](https://www.frictionai.co/white-papers/beyond-kg-strength) series (Franco & da Silva, 2026, [DOI: 10.5281/zenodo.20331344](https://doi.org/10.5281/zenodo.20331344)). Pillar: [Brand Strength Gets You Recognized, Not Recommended](/blog/brand-strength-recognized-not-recommended). Next: [The KG-Hijacked Entity](/blog/kg-hijacked-entity).*
---
# Brand Strength Gets You Recognized, Not Recommended: What 14,140 AI Answers Reveal
# URL: https://www.frictionai.co/blog/brand-strength-recognized-not-recommended
# Slug: brand-strength-recognized-not-recommended
# Category: Original Research
# Published: 2026-06-06
# Author: Joao da Silva
# Keywords: AI Visibility, Answer Engine Optimization, Knowledge Graph, Entity Recognition, Brand Strategy, Generative Engine Optimization
# Brand Strength Gets You Recognized, Not Recommended: What 14,140 AI Answers Reveal
By Joao da Silva and Maryanna Franco (BrilliantSEO) · June 6, 2026
> **TL;DR.** We ran 14,140 controlled queries across five AI systems and found that brand strength, measured by Google Knowledge Graph `resultScore`, predicts whether an AI *recognizes* your brand, not whether it *recommends* you. Inside the category an AI files you under, strength helps (KG score correlates with recommendation at +0.68, p=0.05). Across category boundaries it does nothing (−0.10, statistically zero). New Balance has the strongest Knowledge Graph entry in our whole sample and gets recommended for athleisure 3.4% of the time. Lululemon, with 1/79th the KG score, gets recommended 92.5% of the time. Here is what actually moves the second number.
An AI will happily tell you exactly who a brand is, then never recommend it.
That sentence is the whole study. Ask ChatGPT, Gemini, Claude, Perplexity, or Google's AI Overview "what is New Balance?" and all five answer correctly, every time. Ask the same five "what are the best athleisure brands?" and New Balance shows up in 3.4% of answers. Not becuase the models forgot it. Because they have it filed under footwear, and an athleisure question never opens that drawer.
New Balance is not a weak brand. It holds the **highest Google Knowledge Graph `resultScore` in our entire 12-brand sample (64,235, about 2.5 times Nike's)**. If brand strength bought recommendation, New Balance would dominate. It doesn't. Lululemon, sitting at a `resultScore` of 810, surfaces in **92.5%** of athleisure recommendations. Both brands are recognized at essentially 100%. The gap between them is not awareness. It is something most AEO advice never names.
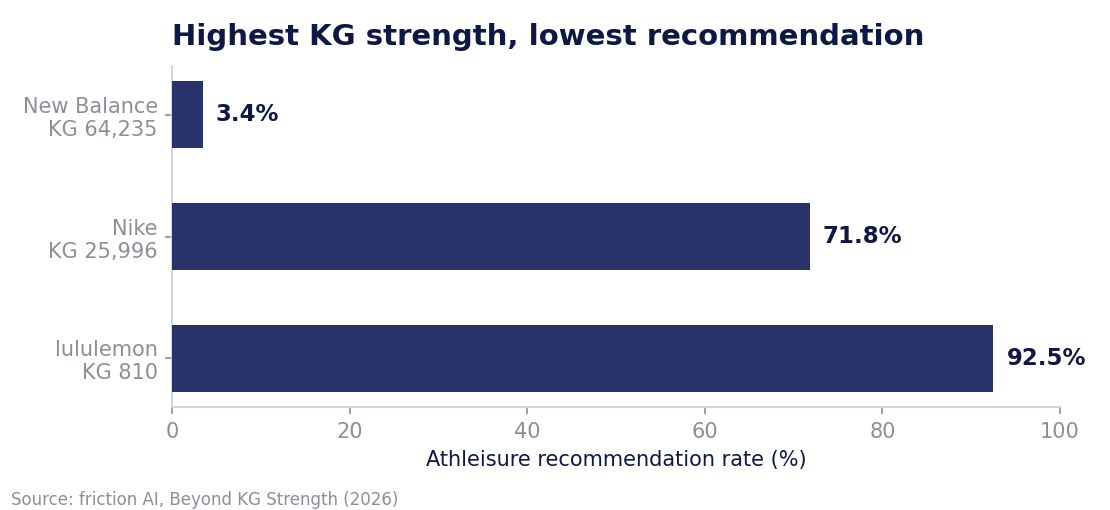
This is the pillar for a five-part study we ran with Maryanna Franco of BrilliantSEO, published in full as the white paper *[Beyond KG Strength](https://www.frictionai.co/white-papers/beyond-kg-strength)* (Franco & da Silva, 2026, [DOI: 10.5281/zenodo.20331344](https://doi.org/10.5281/zenodo.20331344)). Below is the reframe, the five mechanisms that actually drive recommendation, and what to do about each. Every mechanism has its own deep dive.
## Recognition is not recommendation
These are two different surfaces, and they are governed by two different mechanisms.
**Recognition** is what an AI says when you name your brand: "what is Acme?" **Recommendation** is what it says when you name a *category* and let it pick: "best tools for X?" Most brand teams optimize as if these were one problem. They are not.
The cleanest proof is the correlation split. Across all 12 brands, Knowledge Graph strength correlates with the recognition-recommendation gap at **−0.10**, which is statistically indistinguishable from zero. Strength alone does not close the gap. But narrow the lens to the nine brands the AIs file inside the apparel category, and KG strength correlates with athleisure recommendation at **+0.68 (p=0.05)**. Inside your category, strength is a real multiplier. Across the boundary, it buys you nothing, even when the categories are adjacent.
That is the headline, and it is worth stating precisely so it isn't over-read: **brand strength is not irrelevant.** It earns recognition. It earns durability. And, as we'll see with Nike, it can earn a bridge into an adjacent category if the right conditions are met. What it does not do is transfer across a category boundary on its own. Strong brand, wrong drawer, no recommendation.
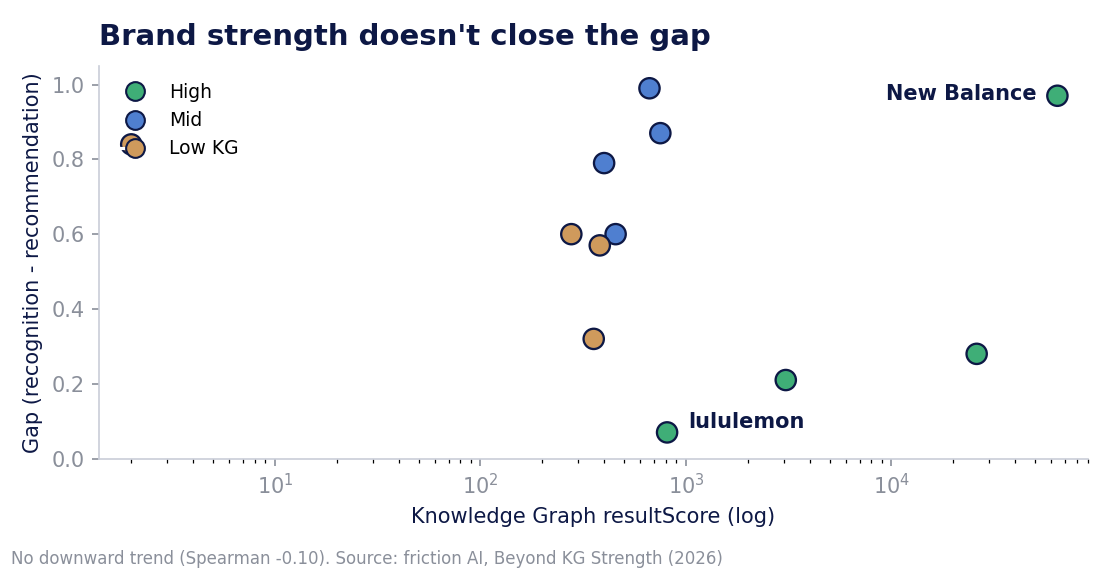
Once you see recognition and recommendation as seperate surfaces, the obvious question is what governs the second one. The study found five mechanisms.
## What actually drives recommendation: five mechanisms
### 1. Category Coding: the AI files you, and the file is sticky
Before an AI decides whether to recommend you, it has already decided what you are. We call this **Category Coding**: every model carries an internal category label for your brand, and a category query only considers the brands inside that category.
The striking part is the agreement. We probed all five models on what category each brand belongs to, and **9 of the 12 brands came back unanimous** (4 of 4, or 3 of 4 with one near-synonym). Nike is footwear to all of them. Lululemon is athleisure to all of them. The models don't just share facts about brands. They share the same mental filing cabinet, and that filing cabinet acts like a cage. Where they disagree, behavior gets fuzzy in exactly the way you'd expect: Gymshark splits 2-2 between sportswear and athleisure across the models, and its athleisure recommendation rate lands in the middle at 40.5%.
You can't out-market your category code. Outdoor Voices spent years positioning itself as *the* athleisure brand. The models code it 28% athleisure and 81% sportswear, and recommend it accordingly. Marketing told one story; the published web told another, and the AIs learned from the web.
→ Deep dive: [Category Coding: how AI sorts your brand before it recommends you](/blog/category-coding-how-ai-sorts-your-brand)
### 2. The KG-Hijacked Entity: when a bigger namesake owns your drawer
Category Coding fails completely when another entity owns your name in the Knowledge Graph. We call this a **KG-Hijacked Entity**.
TALA is a UK athleisure brand. Its Google Knowledge Graph description reads, verbatim, "Financial services company," because a larger Philippines-based fintech owns the `TALA` entity. When we probed the models directly, they correctly called the athleisure TALA an apparel brand. But in actual recommendation queries it surfaced **0% of the time**, the lowest in the sample, and its recognition score was depressed to 0.32, against 0.99 for nearly every other brand. The label on the drawer was wrong, so the brand was invisible regardless of how it markets itself.
This one has a real fix, and it isn't content. It's a Google Knowledge Graph disambiguation request. Most brand teams have never been told the process exists.
→ Deep dive: [The KG-Hijacked Entity: when AI confuses you with a bigger namesake](/blog/kg-hijacked-entity)
### 3. The Category Prototype: every category has a brand at its center
Categories aren't flat lists. Each one is a cluster of brands that get mentioned together, with one brand at the dead center. We call that center the **Category Prototype**.
For athleisure, it's lululemon, and the data is not subtle. Lululemon co-occurs with Alo Yoga **534** times, with Nike **482** times, and with Gymshark **264** times across recommendation responses. It's also the *first* brand named in most answers where it appears (average position 1.64, per the live study dashboard). New Balance, for contrast, co-occurs with lululemon **21** times. It sits outside the cluster as an unconnected node. To get recommended in a category, you have to enter that category's cluster, which means earning third-party content that places you next to the prototype.
One more thing the cluster revealed: it's bigger than the brands we pre-registered. The extractor surfaced more than 260 other brand names, and two we never put in the study, Athleta (74% of recommendation runs) and Vuori (71%), were mentioned more often than 9 of our 12 targets (study dashboard). The category, as the AIs construct it, is wider than any single brand's competitive set.
→ Deep dive: [The Category Prototype: the brand AI thinks defines your category](/blog/category-prototype)
### 4. Sub-Stream Strength: how Nike crosses a boundary New Balance can't
Nike breaks the rule, and the way it breaks it is the lesson. Nike is footwear-coded, exactly like New Balance, yet it gets recommended for athleisure **71.8%** of the time. New Balance gets 3.4%. Same category code, opposite outcome.
The difference is what we call **Sub-Stream Strength**: a dense enough body of category-aligned third-party content to register as a real presence in the adjacent category. Nike has a large apparel sub-stream (decades of coverage about Nike leggings, Tech Fleece, sportswear), so it co-occurs with lululemon **482** times. New Balance co-occurs with lululemon **21** times. Nike built a bridge into athleisure through earned coverage, not by relabeling itself. You cross a boundary by building density on the other side, not by claiming you belong there.
→ Deep dive: [Bridge Brands and Sub-Stream Strength: crossing into an adjacent category](/blog/bridge-brands-sub-stream-strength)
### 5. The Coverage Gap: your own website barely counts
Here is the mechanism most marketing budgets get wrong. On recommendation queries, the brand's own website is almost never the source. We call the distance between what you publish and what AI cites the **Coverage Gap**.
The numbers are stark. On recommendation queries, a brand's own domain accounts for **0 to 3% of citations**, topping out at 2.8% (Reebok). Lululemon has **3,736** third-party citations supporting its recommendations; New Balance has **144**. Recognition runs on your own pages, and recommendation runs on third-party coverage in your category.
The smoking gun is New Balance's athleisure citations. When the models do cite something for New Balance in an athleisure context, the sources are dictionary sites: Merriam-Webster, Cambridge, Collins. There is no real third-party athleisure content about New Balance to retrieve, so the model falls back to looking up what the phrase "new balance" means. An empty drawer, on display.
→ Deep dive: [The Coverage Gap: why your own site barely moves AI recommendations](/blog/the-coverage-gap)
## The two surfaces, side by side
The recognition-recommendation split shows up cleanly in the citation data. Ask an AI "what is this brand?" and it leans on the brand's own domain. Ask it "best brands in this category?" and that same domain nearly vanishes.
| Surface | Question type | Where AI gets its answer |
|---|---|---|
| Recognition | "What is [brand]?" | The brand's own site (ChatGPT 49%, Perplexity 36%, Claude 23%, AI Overview 21%, Gemini 13% of citations) |
| Recommendation | "Best [category] brands?" | Third-party coverage (own site is 0-3%, max 2.8%) |
*Per-LLM recognition shares from the live study dashboard; recommendation shares from the white paper.*
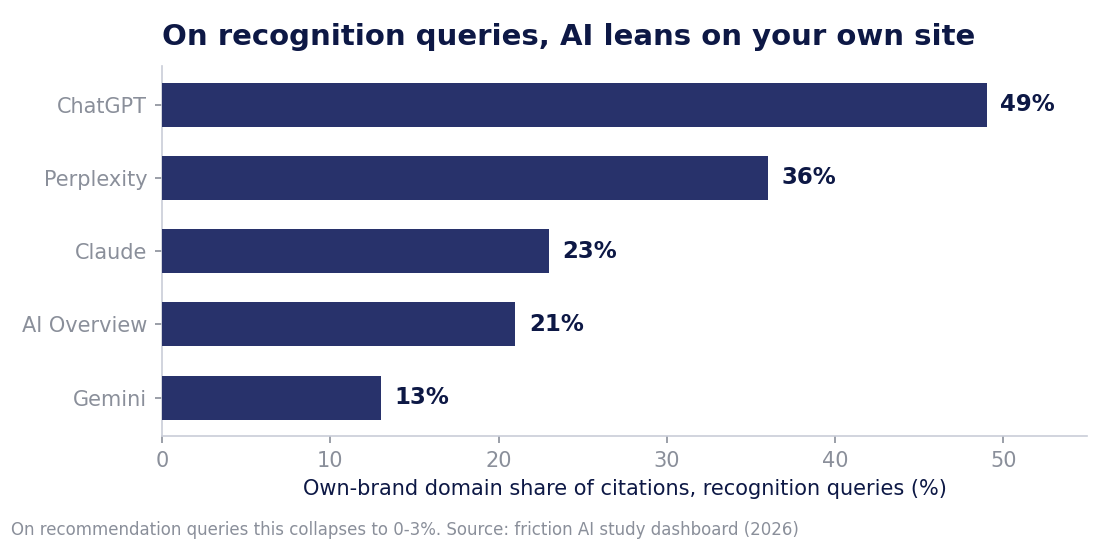
Two surfaces, two mechanisms, two budgets. Optimizing your homepage harder will move recognition and do almost nothing for recommendation. The brands that win recommendation win it on other people's pages.
## What to do with this
The study points to four moves, roughly highest-impact first:
1. **Probe your category code first.** In one prompt, ask each model to categorize your brand. If the models disagree, or file you where you don't sell, that is your binding constraint, and no amount of homepage work fixes it.
2. **Check for a namesake collision.** Look up your Google Knowledge Graph description. If it reads as the wrong company, you have a KG-Hijacked Entity problem, and the fix is a disambiguation request, not content.
3. **Earn category coverage, not just links.** Recommendation is decided by third-party publications in your category. The metric that matters is corroboration density: how many independent sources in your target category reproduce what you want AI to say. Inbound link counts measure the wrong thing.
4. **If you're expanding categories, build the sub-stream.** You don't bridge into an adjacent category by relabeling. You bridge by accumulating enough category-aligned coverage to register as a real presence, the way Nike did in apparel.
## Methodology
> **The study in one line.** 14,140 controlled API queries across 5 AI systems, 12 athletic-apparel brands, 10 prompts, 7 days, single UK exit, May 2026.
We ran 14,140 queries through friction AI's harness, of which 13,992 succeeded (98.95%). The five systems were ChatGPT (`gpt-5`), Gemini (`gemini-2.5-pro`), Claude (`claude-opus-4-7`), Perplexity (`sonar-pro`), and Google AI Overview (via SerpAPI), all with web search on. We tested 12 athletic-apparel brands stratified across three Knowledge Graph strength tiers, using Google KG `resultScore` as the proxy for brand strength. Ten prompts (5 recognition, brand-named; 5 recommendation, category-named) ran 5 times a day for 7 consecutive days, May 3 to 9 2026, from a single UK (London) exit at temperature 0.7. Responses were scored by an Anthropic Haiku-4.5 judge. Full method, every number, and the brand-by-brand data are in the [white paper](https://www.frictionai.co/white-papers/beyond-kg-strength) and the live [study dashboard](https://frictionaistudies.vercel.app/kg-gap).
Two honest limits. This is a 12-brand pilot in one category and one geography, so treat the tier-level claims as directional and the per-brand cases as the durable evidence. And a small follow-up experiment, swapping athleisure prompts for footwear prompts, showed New Balance jumping from roughly 1% to 90% and lululemon dropping from 90% to 0%, which is the cleanest illustration we have that category, not strength, is the gate; but it ran on ChatGPT only, as a single pass, and is not part of the main 14,140-run dataset. We report it as a direction, not a result.
**Disclosure:** both authors are affiliated with friction AI, an AI brand visibility platform. friction AI is not one of the 12 brands studied. The white paper is ungated and the underlying data is published so the analysis can be checked independently.
## FAQ
**Does brand strength help AI visibility at all?**
Yes, but only on the recognition surface and inside your own category. Knowledge Graph strength correlates with recognition and, within a matched category, with recommendation (+0.68, p=0.05). It does not transfer across category boundaries (−0.10).
**Why does AI recognize my brand but never recommend it?**
Because recognition and recommendation are different surfaces. Recognition reads your own site; recommendation reads third-party coverage in the category the AI has filed you under. If you have strong recognition and weak recommendation, you usually have a Coverage Gap, a Category Coding mismatch, or both.
**How do I find out what category AI thinks my brand is in?**
Ask each model directly to categorize your brand in one prompt.
Cross-model agreement is high (9 of 12 brands in our study were unanimous), so a single round of probes is usually enough to reveal your category code.
**Does optimizing my website improve AI recommendations?**
Barely. On reccomendation queries, a brand's own domain is 0-3% of cited sources. Your site drives recognition; third-party coverage in your category drives recommendation.
---
*This is the pillar of a five-part series translating the [Beyond KG Strength white paper](https://www.frictionai.co/white-papers/beyond-kg-strength) into practice. Deep dives: [Category Coding](/blog/category-coding-how-ai-sorts-your-brand) · [The KG-Hijacked Entity](/blog/kg-hijacked-entity) · [The Category Prototype](/blog/category-prototype) · [Bridge Brands and Sub-Stream Strength](/blog/bridge-brands-sub-stream-strength) · [The Coverage Gap](/blog/the-coverage-gap). See the framework applied to 40 SaaS brands in our [40-brand AI visibility audit](/blog/40-brand-ai-visibility-audit).*
---
# Find Buyer Questions for AI Prompts: 4 Sources (2026)
# URL: https://www.frictionai.co/blog/find-buyer-questions-for-ai
# Slug: find-buyer-questions-for-ai
# Category: Monitoring & Measurement
# Published: 2026-04-26
# Author: Joao Da Silva, Co-Founder of friction AI
# Keywords: AI Visibility, Buyer Research, Prompt Engineering, Reddit, Sales Enablement, Answer Engine Optimization
# Find Buyer Questions for AI Prompts: 4 Sources (2026)
By Joao da Silva · April 26, 2026 · Last updated May 18, 2026
> **TL;DR.** Most AI visibility audits fail because the prompts are written by marketers, not buyers. Real prospects do not type pitch-deck language into ChatGPT. They type their pain. This guide walks four sources where buyer language already exists in writing (Reddit, Quora, sales transcripts, support tickets), how to mine each in under 20 minutes, and a 60-minute exercise to build a real prompt set. **This is Step 4 of the [4-step AI visibility audit framework](/blog/15-prompt-ai-visibility-audit)** — the "fix and repeat" stage, where you keep your audit current as your buyers evolve.
The single biggest mistake in AI visibility work is testing prompts you wrote, not prompts your buyers would write. The vocabulary gap between marketers and prospects is wide. Marketers spend their day inside positioning docs, customer-segment slides, and pitch rehearsals. Prospects spend their day with the problem, looking for relief, in their own words. The intersection is small, and the audit prompts you write from inside the marketing bubble miss most of where the actual buyer queries live.
## Why are imagined buyer queries usually wrong?
Marketers default to writing prompts in their own language because their own language is what they have. The result is an audit that measures how well AI answers a query a real prospect would never type. The dashboard fills with green, the team agrees the brand is doing okay, and the pipeline gap shows up two quarters later.
The fix is to never invent prompts. Start with the [15 universal AEO prompts](/tools/aeo-starter-prompts) as a baseline, then mine custom variants from artifacts where buyers already wrote down what they want to know. Four sources are reliably good, and one source (your own brain) is reliably bad. The [12 use-case prompt templates for AI visibility](/blog/how-to-write-ai-visibility-prompts) covers the prompt deep-dive; this guide covers the operational dig for finding what buyers actually ask.
For context on the failure modes that bad prompt selection produces downstream, see [11 AI visibility failure modes that quietly lose you deals](/blog/why-ai-ignores-your-brand-blindspots). The "win category, lose problem" mode is almost always rooted in audit prompts that match the brand's category vocabulary instead of the buyer's pain vocabulary.
## Where do real buyer questions live?
Real buyer questions live in writing — specifically, in places where the buyer had a reason to type them out without an audience. The four reliable sources below all share that property: each captures the buyer's unfiltered intent at a specific point in the journey, recorded in their own words. Prompts pulled from real artifacts produce sharper diagnostics than prompts written from imagination.
Four sources, ordered by accessibility (easiest first):
1. **Reddit thread titles** in your category subreddit. Free, fast, no permissions needed.
2. **Quora questions** with 5+ answers in your category. Free, sharper for B2B and technical buyers.
3. **Sales call transcripts** from your last 10 to 20 discovery calls. Internal, requires Gong/Chorus/Fireflies or 30 minutes with three AEs.
4. **First-touch support tickets** from your last 50 customer signups. Internal, requires Intercom/Zendesk/HubSpot access.
The four sources are complementary, not redundant. Reddit captures unfiltered top-of-funnel pain, Quora captures more deliberate research-mode questions, sales calls capture mid-funnel evaluation language, and support tickets capture post-decision implementation questions. The full audit prompt set should pull from all four to cover the buyer journey end to end.
## How do you mine Reddit for buyer questions?
Open the relevant subreddit (r/SaaS, r/marketing, r/sales, r/[your-vertical]) and scan the **question-shaped thread titles**. People type their problems literally as they think them. The thread titles ARE your prompts — copy them verbatim, including the imperfections that make them sound like real buyers rather than marketers writing for SEO.
Practical workflow:
1. Open the subreddit and sort by "Top" / "Past Year" to filter for high-engagement threads
2. Scroll through the first 50 to 100 thread titles
3. Copy any title that ends in a question mark or describes a problem in buyer language
4. Tag each by funnel layer: Layer 1 (entity recognition: "Has anyone heard of X?"), Layer 2 (visiblity: "Best tool for Y?"), Layer 3 (recommendation: "Is X worth it for Z?")
Reddit threads also surface a second layer of useful data: the *answers*. Read the top three responses on each high-engagement thread and note wich brands get mentioned, in what order, and with what attributes.
That's exactly the leaderboard structure AI surfaces, often pulled from these same Reddit threads. If your brand keeps appearing in second or third position in Reddit responses, expect the same in ChatGPT and Perplexity.
Time budget: 20 minutes for one subreddit, longer if you cover multiple verticals.
## How do you mine Quora for buyer questions?
Same logic as Reddit, often sharper for B2B software and technical categories where the audience skews more research-driven. Filter Quora for questions in your category with five or more answers; that signal tells you the question is asked frequently enough to matter.
Quora questions tend to be longer and more grammatical than Reddit titles, which means they translate more directly into the conversational form that ChatGPT and Claude prefer ([HubSpot AEO guide](https://www.hubspot.com/products/aeo)). A Quora question like "What's the best CRM for a 10-person startup that's switching from spreadsheets?" is essentially audit-ready as written; you do not need to reformat it.
The downside of Quora is signal-to-noise. There is more bot content and more recycled questions than on Reddit. Skim past anything that sounds like SEO bait or a marketer fishing for backlinks. The questions worth copying are the ones with conversational specificity: a buyer named their team size, their current tool, their constraint.
Time budget: 15 minutes per category.
## How do you get buyer questions from your sales team?
Ask three of your AEs the same question: **"What are the top 10 questions buyers ask in discovery calls?"** Their pattern recognition is gold. The exercise takes under an hour, requires no Gong / Chorus / Fireflies infrastructure, and consistently produces 70-80% of the value of full transcript mining at a fraction of the time cost (friction AI internal benchmark, April 2026, comparing AE-recall sets against full transcript sets across our own audit cohort).
If you have Gong, Chorus, or Fireflies, mining transcripts directly is even better. Three workflows that work:
1. **Filter for question-mark sentences in buyer turns** (most call-recording tools support this query). Export the top 100, dedupe by intent, and you have a real prompt candidate set.
2. **Search transcripts for objection patterns** ("but how do you handle X", "what about Y"). These are Layer 3 audit prompts in disguise; the buyer is checking your concerns surface in real time.
3. **Filter for "vs" or "compared to" mentions.** These transcripts surface Layer 3 comparison prompts in the buyer's own framing.
The AE shortcut produces most of the value of full transcript mining at a small fraction of the time cost. Run the full mining workflow once a quarter; the AE shortcut works monthly.
## How do you mine support tickets for buyer questions?
First-touch customer messages are pure gold and almost no team uses them for prompt research. Filter Intercom, Zendesk, or HubSpot for the openers your existing customers wrote when they first signed up or asked a question. What they asked then is what your prospects are typing into ChatGPT right now.
The structural advantage of support tickets over sales calls: they are written.
The ticket text is exactly the keystroke pattern a buyer would use in ChatGPT. Sales calls have the right vocabulary but the wrong format (spoken not typed). Support tickets are both.
Two filters that work:
1. **Tickets opened in the first week after signup.** These are the questions a buyer had when they were still in evaluation mode and lacked context.
2. **Tickets that were closed without resolution requiring a feature change.** These are pure information-gap questions, the same shape as audit prompts.
Pull 50 tickets, copy the opening sentence of each, dedupe by intent, and you have 30 to 40 high-quality candidates.
## What sources should you NOT use?
Three sources reliably produce false-positive prompt candidates more often than they help — and all three share the same root cause: they are sources of *your* marketing language, not your buyer's pain language. Avoid each one even when they feel like the easiest place to start, becuase the prompt set you build from them will measure imagination, not reality:
- **Your marketing team's keyword list.** Too sanitized, written in your voice, optimized for Google not ChatGPT. The keywords your brand ranks for on Google are rarely the same as the prompts buyers type into AI.
- **Your own brain.** You have been thinking about your category for years. You cannot think like a buyer who just discovered the category last week. Trying to imagine what they would ask produces audit prompts that test your imagination, not their reality.
- **Generic "AI search best practice" articles.** Most are written for the median brand, not yours. Generic prompt lists optimize for the average vertical and miss what is specific to your buyer segment, your competitors, your category vocabulary.
The pattern across all three: they are sources of *your* language, not the buyer's. The whole point of this exercise is to escape your own vocabulary. The four sources in the previous sections work because they capture buyer language at the moment a buyer wrote it down.
## What's the 60-minute exercise to build a custom prompt set?
The exercise has four steps, takes one focused hour with your sales team and category subreddit, and produces about 60 prompt candidates. De-dupe down to the strongest 15-20 prompts, group by funnel layer, and lock that set for quarterly tracking — the prompts will outlast three or four model updates without needing to be rewritten.
| Step | Time | Source | Output |
|---|---|---|---|
| 1 | 20 min | Read 10 sales call transcripts (or talk to 3 AEs) | ~15 buyer-language questions |
| 2 | 20 min | Scan top 30 thread titles in your category subreddit | ~20 question-shaped prompts |
| 3 | 10 min | Pull first messages from your last 50 support tickets | ~15 information-gap prompts |
| 4 | 10 min | Meta-prompt ChatGPT: "I'm a [your ICP] dealing with [your buyer's problem]. What 10 questions might I type into ChatGPT to find a tool that helps?" | ~10 buyer-perspective prompts |
After 60 minutes you have ~60 candidates pulled from real sources. Apply the [5 principles for writing AI visibility prompts](/blog/how-to-write-ai-visibility-prompts) as filters: cut anything written in your marketing voice, convert category-only candidates to problem-led variants, force at least 60% non-branded, and ensure the conversational form matches what buyers actually type.
What survives is your tracked audit set. Lock it. Run it across [ChatGPT, Claude, and Perplexity](/blog/track-brand-mentions-across-ai-platforms) using the 4-step audit framework with the 15 starter prompts from [the pillar guide](/blog/15-prompt-ai-visibility-audit), and re-read the results quarterly. The exercise compounds: every quarter you get sharper at recognizing which buyer-language candidates produce the cleanest diagnostic data.
## Frequently Asked Questions
### How long does the full buyer question mining take?
The 60-minute exercise produces a working prompt set. A more thorough version (mining 50 sales transcripts, 100 Reddit threads, 100 support tickets, plus Quora) takes about 4 hours and gets you a deeper candidate pool. For most teams, the 60-minute version captures most of the value at a fraction of the cost.
### What if my company doesn't have call recording or a support ticket system yet?
Reddit alone gets you most of the way. Twenty minutes scanning your category subreddit produces 15 to 20 high-quality question-shaped prompts in real buyer language. The other three sources are accelerators, not requirements; the audit works without them.
### Should I include questions buyers ask competitors, not just my brand?
Yes. Layer 2 audit prompts (the visibility / leaderboard layer) are intentionally non-branded, which means they capture buyer queries about *competitors* as much as about you. Mining Reddit threads where buyers ask "alternatives to [competitor]" or "is [competitor] worth it" produces prompts that test your relative position in AI's category-level recommendation set.
### How often should I refresh the buyer question pool?
The prompt set itself should rarely change once locked (you need run-over-run comparison value). The buyer-language input you mine to populate it should refresh quarterly. New use cases enter your category, your competitors evolve, and the language buyers use to describe their pain shifts faster than your positioning does.
### Are buyer questions from one vertical useful for another?
No. Run the mining exercise per vertical. A SaaS audit prompt set will not transfer to a DTC e-commerce audit even if both brands sell to "small businesses." Buyer language is vertical-specific, and the audit's diagnostic value depends on the prompt vocabulary matching the buyer vocabulary in your specific market.
### How do I tell if a buyer question is worth tracking?
The criterion comes from Citation Labs' research: a tracking-worthy prompt has contrastive reasoning ("better," "worth it"), category anchoring, and a constraint clause ([Citation Labs, 2025](https://citationlabs.com/tracking-worthy-bofu-prompts/)). Add the structural test: it should be answerable by an LLM in 2-3 paragraphs (not a one-line factoid), and it should produce a different answer for two different brands in your category.
### What's the cheapest source if I have only 30 minutes?
Reddit. Open your category subreddit, sort by Top / Past Year, scroll the first 30 thread titles, copy the question-shaped ones. You will end up with 10 to 15 high-quality buyer-language prompts in 25 minutes. The other 5 minutes is for tagging by funnel layer.
---
### Run this audit on your own brand
Want this 4-step audit running across ChatGPT, Claude, Perplexity, and Gemini on a continuous schedule — without doing the spreadsheet by hand?
**[▶ Start your free trial of friction AI →](https://www.frictionai.co/signup)**
Or grab the **[free 15-prompt starter pack →](https://www.frictionai.co/tools/aeo-starter-prompts)** and run the manual workflow tonight.
---
**About the author.** Joao da Silva is co-founder of [friction AI](https://www.frictionai.co) alongside Camilla Wirth. friction AI tracks brand visibility across ChatGPT, Claude, Perplexity, and Gemini for SaaS and DTC brands. Joao writes about AI search, entity recognition, and the operational side of getting recommended by LLMs. Connect with him on [LinkedIn](https://www.linkedin.com/in/joao-da-silva-v/).
---
# How to Track Brand Mentions in ChatGPT, Claude & Perplexity (2026)
# URL: https://www.frictionai.co/blog/track-brand-mentions-across-ai-platforms
# Slug: track-brand-mentions-across-ai-platforms
# Category: Monitoring & Measurement
# Published: 2026-04-26
# Author: Joao Da Silva, Co-Founder of friction AI
# Keywords: Brand Tracking, ChatGPT, Claude, Perplexity, AI Visibility, Answer Engine Optimization, Multi-Platform
# How to Track Brand Mentions in ChatGPT, Claude & Perplexity (2026)
> **TL;DR.** Tracking brand mentions in one model is a tutorial. Tracking across three is a workflow. This guide shows a repeatable manual process for ChatGPT, Claude, and Perplexity, the spreadsheet that keeps it consistent, and the signals to capture so you can diagnose what to fix next. This is **Step 2 of the 4-step AI visibility audit**, pair it with the [free 15-prompt starter set](/blog/15-prompt-ai-visibility-audit) for the full workflow.
📺 Watch the 4-step audit walkthrough on YouTube, full framework walkthrough, prompt setup, and diagnosis.
**[▶ Watch the full walkthrough on YouTube →](https://youtu.be/wWqbnLPGXQc)**
Different assistants can give different answers to the same product question. If you track only one, you see one platform’s output rather than a cross-platform view of how your brand is represented.
This post is the operational guide for Step 2: running the same prompt set across ChatGPT, Claude, and Perplexity, capturing comparable outputs, and logging the details that make the results actionable.
If you need the operating model behind this workflow, start with our [AI brand monitoring guide](/blog/ai-brand-monitoring). It covers the scorecard, review cadence, and when a manual spreadsheet stops being practical.
## Why track brand mentions across multiple AI platforms?
The practical reason is variance. Different systems can produce different brand sets, different phrasing, different citations, and different confidence even when the prompt is identical. The more you rely on a single surface, the more likely you are to mistake one model’s behavior for your market reality.
A multi platform pass helps you seperate distinct outcomes that often get mixed together:
- **Mention**: your brand name appears at all.
- **Citation**: your brand or a claim about your brand is supported by a linked source (where the interface provides citations).
- **Recommendation**: the assistant positions your brand as a suggested option for the user’s goal.
- **Sentiment**: the language is positive, neutral, or negative.
- **Factual accuracy**: the description matches what is true about your product.
Treat these as separate fields. A brand can be mentioned without being recommended, recommended without being cited, or cited with inaccurate details.
Also, do not treat list order as a stable rank. Many assistants vary ordering across runs, and interfaces evolve. Your job in tracking is to capture what happened in a specific run, then look for consistant patterns over time.
## What you need before you start tracking
You can do a first round with free accounts and a spreadsheet.
1. **Accounts on each platform**
Create accounts for ChatGPT, Claude, and Perplexity. Tier, default model, and controls change over time, so treat your account setup as a variable.
2. **A locked prompt set**
Use the [15 starter prompts](/tools/aeo-starter-prompts) from the [4-step audit pillar](/blog/15-prompt-ai-visibility-audit), or build a custom set of 10 to 15 prompts from sales calls, support tickets, and community threads. Freeze the set so you can compare runs.
3. **A spreadsheet template**
Keep it simple but explicit. Suggested columns:
- Prompt
- Platform
- Model or mode (as labeled in the UI)
- Run date and time
- Run number (1, 2, 3)
- Mentioned (yes/no)
- Recommendation (yes/no)
- Citation present (yes/no, and source domains if applicable)
- Position in answer (capture as observed, but do not treat as rank)
- Accuracy notes (wrong features, stale pricing, wrong category, etc.)
- Sentiment notes (optional)
4. **Focused time and consistent conditions**
Manual tracking time varies by prompt complexity, response length, and interface speed. Avoid promising a fixed time budget. Instead, aim for consistency: same prompt set, same run window, and the same logging detail each round.
5. **A simple repeatability rule**
For each prompt, run multiple times and log the variance. If you can't run multiple times, record that explicitly and treat the output as directional.
The manual workflow is four stages. The value is not the screenshot of a single answer. It is the consistent capture of comparable runs.
## How to build a tracking worthy prompt set
Stage 1 is choosing prompts that match how buyers actually ask. For a repeatable audit, you want prompts that are:
- **Natural language**: how a person would type it
- **Category anchored**: the category term appears, not only brand names
- **Decision oriented**: implies comparison, constraints, or a goal
If you want a default starting point, use the [15 starter prompts](/tools/aeo-starter-prompts) linked from the [4-step audit pillar](/blog/15-prompt-ai-visibility-audit).
If you want to customize, pull candidates from:
- Sales call questions and objection handling notes
- Support ticket phrasing
- Community thread titles in your category
- Competitor comparison pages that rank for your category terms
Whatever set you choose, freeze it. Replace prompts only when category language or your ICP changes enough that the existing prompts stop reflecting real buyer queries.
## How to track brand mentions in ChatGPT
Stage 2 begins with ChatGPT.
### What to log for every ChatGPT run
For each prompt, capture:
- **Mention**: yes/no
- **Recommendation**: yes/no, and the phrasing used
- **Accuracy**: correct category, correct capabilities, correct positioning
- **Any citations shown in the interface**: copy the linked domains or URLs when present
- **Run context**: model or mode label shown in the UI, and the date
ChatGPT interfaces change, and the same applies to model defaults and search behavior.
Do not rely on a stable toggle name or placement. The safest approach is to record the mode and date for each run.
### ChatGPT Search notes (what to do, and what not to assume)
OpenAI describes ChatGPT Search as a feature that can search the web and provide inline citations, and that it can use multiple third party search providers. Reference: https://help.openai.com/en/articles/9237897-chatgpt-search
Practical implications for tracking:
- **Do not treat ChatGPT as training data only**. Depending on mode and prompt, it may search automatically and may show citations.
- **Do not attribute results to a single provider**. OpenAI indicates multiple third party providers can be used.
- **Make runs comparable**. If you are comparing quarter over quarter, record whether Search appeared to be in play and whether citations were shown.
### Run hygiene for ChatGPT
- Start a fresh chat for each prompt to reduce cross prompt contamination.
- Keep the prompt text identical across platforms.
- If you do multiple runs, spread them over a short window so your run set reflects the same content environment.
If you want the deeper platform specific setup, see [how to track ChatGPT brand visibility](/blog/how-to-track-chatgpt-brand-visibility).
## How to track brand mentions in Claude
Stage 3 is the Claude pass.
### What to log for Claude
Use the same columns as ChatGPT so your spreadsheet aggregates cleanly:
- Mention and recommendation
- Accuracy issues
- Any consistent hedging language that affects whether your brand is framed as a safe choice or an edge case
- Run context: model label, workspace context if relevant, date
### Claude run hygiene
- Start a fresh conversation for each prompt.
- Avoid running inside a context heavy workspace if it injects additional documents or memory that makes the run non comparable to baseline usage.
- Capture variance across runs rather than chasing a single best answer.
A common failure in Claude tracking is to over interpret tone. Claude can be conservative about naming brands or may ask clarifying questions. That can be a style or safety posture, not a visibility problem by itself. The tracking question is whether your brand is present, whether it is recommended, and whether the description is correct.
## How to track brand mentions in Perplexity
Stage 4 is the Perplexity pass.
### What Perplexity is useful for in a tracking workflow
Perplexity describes its approach as searching the web and providing answers with citations. It is designed to help users inspect sources. Reference: https://www.perplexity.ai/help-center/en/articles/10352895-how-does-perplexity-work
For brand tracking, this typically makes Perplexity your most source inspectable surface:
- Capture whether your brand is mentioned and recommended.
- Capture the **linked citations** and the domains that appear repeatedly.
- When your brand is missing, capture which sources are cited for competitors.
Avoid universal claims about how Perplexity ranks or weights sources. Use it as an evidence trail for the specific prompt and run you executed.
### Perplexity run hygiene
- Keep the prompt identical to your ChatGPT and Claude prompt.
- Record the mode label shown in the UI and the date.
- Save citations as URLs in your sheet so you can audit them later, especially when the assistant describes your product incorrectly.
For deeper Perplexity tactics, see [tracking brand visibility in Perplexity](/blog/track-brand-visibility-perplexity).
## See also: AI visibility tools compared
If you are reaching the point where you want to graduate from manual tracking, these companion posts cover the tools landscape and evaluation angles:
- **[Best AI visibility tools compared (2026)](/blog/best-ai-visibility-tools-compared-2026)**, a broader landscape with feature and pricing comparisons
- **[Profound vs Otterly: AI visibility tools compared](/blog/profound-vs-otterly-ai-visibility-tools-compared)**, a public-plan comparison of the two platforms
- **[AI visibility platform comparison (2026)](/blog/ai-visibility-platform-comparison-2026)**, Profound vs AthenaHQ and the mid-market alternatives
If you are using these pages to evaluate vendors, check the pricing sections for freshness. **Last verified: July 26, 2026.**
## How to score and aggregate results without pretending there is a stable rank
After you finish runs across platforms, reduce the raw logs into a few summary metrics that remain meaningful even when ordering shifts.
### Recommended summary metrics
Per platform:
- **Mention coverage**: number of prompts where you are mentioned at least once within your run set.
- **Recommendation coverage**: number of prompts where you are recommended (not just listed).
- **Citation coverage** (where applicable): number of prompts where your brand is linked or supported by citations.
- **Accuracy issues count**: prompts with at least one factual error about your product.
Cross platform:
- **Cross platform overlap**: prompts where all tracked platforms mention your brand at least once in the run set.
- **Cross platform recommendation overlap**: prompts where all tracked platforms recommend your brand at least once.
If you still want to record order, treat it as an observation:
- Log position as seen for the run.
- Compute an average only if you are also logging variance and run context.
- Do not interpret a single run list order as a durable leaderboard.
### Illustrative summary table
Use an output format like this to make your next step obvious. The numbers below are illustrative, not benchmarks.
**Table 1: Illustrative example output format.**
| Platform | Prompts mentioned (of 15) | Prompts recommended (of 15) | Prompts with citations (of 15) | Accuracy issues (count) | Notes |
|---|---:|---:|---:|---:|---|
| ChatGPT | | | | | Record model or mode and date; capture citations if shown |
| Claude | | | | | Record model or mode and date; note hedging patterns |
| Perplexity | | | | | Save cited URLs and domains |
## How to read patterns and prioritize what to fix
Treat the tracking round as diagnosis input, not a score to celebrate.
### 1) Start with recognition, then recommendation, then validation
If you are missing from brand anchored prompts, that is a recognition problem. If you are present but rarely recommended, that is a positioning and comparative authority problem. If you are recommended but described inaccurately, that is an accuracy and narrative control problem.
These are different fixes. Tracking works when your sheet clearly separates them.
### 2) Use Perplexity citations as your evidence trail
Where Perplexity provides citations, it can tell you which URLs are shaping the answer for that prompt. This is often the fastest way to identify:
- Which third party pages repeatedly define your category
- Which reviews, listicles, or forum threads keep appearing for competitors
- Which sources are outdated or incorrect about your product
Then you can prioritize: update your owned content, improve third party coverage, or correct misinformation on the sources that are actually being used.
### 3) Fix prompt level gaps before platform level narratives
It is tempting to say you are weak in one platform. The higher leverage view is usually prompt level:
- If you are absent across all platforms for the same category only prompt, that suggests a category association gap.
- If you are present in some platforms but absent in one, look at the cited sources and the phrasing used. It may be a retrieval difference, or it may be that one platform is drawing from different surfaces for that query.
For more on common patterns, see [11 AI visibility failure modes guide](/blog/why-ai-ignores-your-brand-blindspots).
## When to graduate from manual to automated tracking
Manual tracking is useful when you need clarity on what is happening and why. It gets harder when you need cadence, scale, and reliable historical comparisons.
Automation becomes more compelling when:
- You need frequent runs and consistent timestamps without manual effort
- You track multiple brands or multiple product lines
- You need clean trend reporting over time, including changes in wording and citations
If you are exploring automation, use your manual sheet as your requirements document. It tells you exactly which fields you need a tool to capture: mention, reccomendation, citations, accuracy notes, run context, and timestamps.
This is the problem [friction AI](https://www.frictionai.co) is designed to address. If you evaluate tools, compare them against the criteria your workflow actually needs, and validate outputs by spot checking prompts inside the platforms.
## Frequently Asked Questions
### How do I know if ChatGPT mentions my brand?
Run a small set of buyer realistic prompts in ChatGPT and log whether your brand is mentioned, recommended, and described accurately. For each run, record the model or mode label and the date. ChatGPT may use web search and may show inline citations depending on the experience you are in, so capture citations when they appear. Reference: https://help.openai.com/en/articles/9237897-chatgpt-search
### Should I run each prompt in a new chat?
If you want comparable results across prompts, use a fresh chat or conversation per prompt. Prior context can bias responses, and that bias is hard to detect later when you are aggregating.
### How do I track brand mentions in Claude?
Run the same locked prompt set in Claude and log mention, recommendation, and accuracy. Record the model label and date. Focus on whether Claude names your brand and how it frames tradeoffs, not on whether the wording is more cautious than another platform.
### How do I see sources in Perplexity?
Perplexity searches the web and links citations so you can inspect sources. For every prompt, save the cited URLs or at least the source domains, especially when your brand is missing or described incorrectly. Reference: https://www.perplexity.ai/help-center/en/articles/10352895-how-does-perplexity-work
### What is the best AI brand monitoring tool in 2026?
It depends on your requirements: platforms covered, fields captured (mentions vs citations vs recommendations), cadence, reporting, and whether you need collaboration. Use the tool comparisons here and validate by spot checking outputs against live runs in the assistants:
- [best AI visibility tools compared (2026)](/blog/best-ai-visibility-tools-compared-2026)
Pricing sections: **Last verified: July 26, 2026**
### How often should I run brand visibility checks?
Pick a cadence you can maintain with consistent prompts and logging. Quarterly is a common baseline for manual tracking. If you need more frequent reporting, record run context carefully because platform interfaces and defaults change, and you want your time series to remain interpretable.
### How long does a multi platform tracking round take?
It varies by prompt length, platform speed, and how many runs you do. Instead of targeting a universal time budget, standardize your process: identical prompts, consistent run counts, and explicit recording of model or mode and date.
### Can I use paid tiers instead of free tiers?
You can, but treat paid tier runs as a separate dataset. Model defaults, modes, and limits vary over time and across tiers. The most important step is to record what you used in each run so comparisons remain valid later.
### What is the minimum useful prompt count?
Ten prompts is a practical floor for a directional read. Fifteen prompts is a common size because it lets you cover brand anchored prompts, category only prompts, and comparison or validation prompts. If you go larger, the value comes from better coverage of your category vocabulary, not from sheer volume.
### How do I track a prompt where my brand is not mentioned?
Log it as not mentioned, then capture which brands were mentioned, whether any were recommended, and any citations or sources shown. Missingness is part of the competitive map, and the cited sources often point to what is shaping the answer.
---
## Run this audit on your own brand
Want Step 2 running across ChatGPT, Claude, and Perplexity on a continuous schedule, with run context and deltas captured automatically?
**[▶ Start your free trial of friction AI →](https://www.frictionai.co/signup)**
Or grab the **[free 15-prompt starter pack →](https://www.frictionai.co/tools/aeo-starter-prompts)** and run the manual workflow.
---
# 40 SaaS Brands, Two GPT Models. Only 12 Passed Layer 1.
# URL: https://www.frictionai.co/blog/40-brand-ai-visibility-audit
# Slug: 40-brand-ai-visibility-audit
# Category: Original Research
# Published: 2026-04-26
# Author: Joao Da Silva, Co-Founder of friction AI
# Keywords: AI Visibility, Original Research, Cohort Study, Knowledge Graph, GPT-5.2, Entity Recognition, Answer Engine Optimization
# 40 SaaS Brands, Two GPT Models. Only 12 Passed Layer 1.
By Joao da Silva · April 26, 2026 · Last updated May 18, 2026
> **TL;DR.** We tested 40 SaaS brands' Layer 1 AI visibility (entity foundation, training-data recognition, web-search recognition) on both gpt-4o and gpt-5.2. Only 12 brands cleanly passed all three sub-tests, and the same 12 passed under both models. The model upgrade did not move the strict pass count. The binding constraint is the Google Knowledge Graph entity, which does not change when you upgrade your LLM. Three findings below, plus the full dataset and methodology.
The most-discussed assumption in AI visibility right now is that the next model will fix it. ChatGPT does not know your brand today, the argument goes, but gpt-5.2 has a fresh training cutoff and better recall, so wait six months and the problem shrinks. We wanted to test that. Specifically: does the leap from gpt-4o (training cutoff Oct 2023) to gpt-5.2 (Dec 2025) move the needle on how many SaaS brands AI can correctly recognize?
Short answer: no. Not at the strict pass count. The same 12 of 40 brands cleanly pass all three Layer 1 sub-tests on both gpt-4o and gpt-5.2. The newer model recovers some borderline cases (Linear, Bezel, Greptile flipped from "I'm not familiar" to correct identification) and surfaces a regression worth noting (Celest's web search ranking dropped). But the strict pass count of 12 is identical, because the binding constraint is upstream of the LLM.
## What did we set out to test?
Layer 1 of the [4-step AI visibility audit framework](/blog/15-prompt-ai-visibility-audit) splits into three sub-levels: entity foundation (does AI have your brand in its knowledge graph?), training-data recognition (does the LLM know you without live retrieval?), and web-search recognition (does the LLM identify you when allowed to search the live web?). Each fails for different reasons.
We wanted to answer four questions:
1. What share of SaaS brands cleanly pass Layer 1 today?
2. Does the gpt-4o → gpt-5.2 upgrade meaningfully change that share?
3. When brands fail, what failure mode dominates?
4. How does the failure pattern split between established (G2 category leaders) and recent (YC W24/W25) cohorts?
## How did we run the audit?
40 SaaS brands, stratified across three Knowledge Graph tiers to test the training-data depth hypothesis — high-KG incumbents like Salesforce and Asana versus low-KG recent entrants from the YC W24/W25 batches. Three independent tests per brand: Knowledge Graph API query, training-data-only LLM recognition, and web-search-enabled LLM recognition.
- **20 G2 category leaders.** Five each from CRM, project management, product analytics, and AI content/MarTech. Established brands with deep training-data presence. The "known good" baseline.
- **20 Y Combinator W24/W25 SaaS startups.** First 20 alphabetical from the YC batch site, B2B Software industry tag. Recent enough that gpt-4o (Oct 2023 training cutoff) has not seen them, but gpt-5.2 (Dec 2025) might have.
Three tests per brand:
| Test | Method | What it measures |
|---|---|---|
| 1. Entity foundation | Google Knowledge Graph Search API, query brand name, capture top result + resultScore | Does the brand exist as a structured entity? |
| 2. Training-data recognition | OpenAI gpt-4o and gpt-5.2 via API, prompt "Who is [brand]?", no tools | Does the LLM know the brand from training, with no live retrieval? |
| 3. Web-search recognition | Same models with `web_search` tool use forced | Does the LLM correctly identify the brand when allowed to search? |
Scoring rubric for tests 2 and 3: PASS if the response correctly identifies the brand and its category. WEAK_PASS if identified but with wrong details. FAIL if "I'm not familiar" (NOT_RECOGNIZED) or "describes a different company" (CONFUSED_IDENTITY). Single-rater scoring; we read every response. Total combined runtime: about 1 hour 37 minutes. Total combined API cost: about $0.87.
Limitations up front: 40 brands is directional, not statistically powered. OpenAI only; Anthropic Claude and Google Gemini may have different recall profiles. Layer 1 only; Layer 2 (visibility) and Layer 3 (recommendation) were not in scope.
Single-rater scoring with no inter-rater reliability check. The full dataset, methodology, and raw response logs are linked at the bottom.
## Finding 1: Why is the Knowledge Graph the binding constraint?
**Every brand that cleanly passed Layer 1 had a high-confidence Knowledge Graph entry — and none of the brands without one passed.** 12 of 40 brands (30%) cleanly passed all three Layer 1 sub-tests under both gpt-4o and gpt-5.2. The same 12 brands passed on both models. The model upgrade improved borderline cases but did not move the strict pass count.
12 of 40 brands (30%) cleanly passed all three Layer 1 sub-tests under both gpt-4o and gpt-5.2. The same 12, on both models:
- HubSpot, Pipedrive (CRM)
- Asana, Monday.com, Notion, ClickUp (project management)
- Mixpanel, Amplitude, Heap, Hotjar (product analytics)
- Copy.ai, Writesonic (AI content)
All 12 share one structural property: a high-confidence Knowledge Graph entry with `resultScore` over 100. None of the brands without that structural anchor passed all three sub-tests. The model upgrade improved recall for some borderline cases (gpt-5.2 correctly identified Linear and 2 YC startups that gpt-4o did not), but the strict pass count was identical. **For a brand pursuing AI visibility, fixing the Knowledge Graph entity is the highest-leverage Layer 1 action; it gates everything downstream.**
Layer 1 strict pass rate by stratum. The same 12 brands pass on both gpt-4o and gpt-5.2. The model upgrade did not move the strict pass count.
There is also a structural-vs-recall gap worth flagging. 6 of 40 brands have a Knowledge Graph entity (PASS or WEAK_PASS on Test 1) but fail training-data recognition on gpt-5.2. The same 6 fail on gpt-4o. All 6 have `resultScore` below 100, meaning their KG presence is barely-there. The implication: low-confidence Knowledge Graph entries do not appear to feed LLM training corpora reliably. A KG entry with score over 100 is the threshold that matters. [Search Engine Land has documented similar patterns](https://searchengineland.com/why-pr-is-becoming-more-essential-for-ai-search-visibility-455497) where structural authority gates LLM citation behaviour more than on-page optimization does.
## Finding 2: How does the failure mode shift on newer models?
**Answer: NOT_RECOGNIZED drops, CONFUSED_IDENTITY rises. As models get better at recall, confidently-wrong answers become the dominant failure mode.**
The total failure-event count dropped from 29 on gpt-4o to 23 on gpt-5.2 (a 21% reduction). But the *shape* of those failures changed meaningfully:
| Failure mode | gpt-4o | gpt-5.2 | Δ |
|---|---:|---:|---:|
| NOT_RECOGNIZED ("I'm not familiar with...") | 19 (65%) | 12 (52%) | -7 |
| CONFUSED_IDENTITY (describes a different company) | 10 (35%) | 11 (48%) | +1 |
NOT_RECOGNIZED dropped meaningfully. CONFUSED_IDENTITY held flat in absolute count and rose to nearly half of all failures as a share. **As model recall improves, confidently-wrong answers become the dominant failure mode.** This matters because CONFUSED_IDENTITY is more dangerous than NOT_RECOGNIZED: a buyer who hears "I'm not familiar with Acme" knows to keep looking. A buyer who hears "Acme is a Belgian video-tech company" (when Acme is actually a YC SaaS startup) walks away with the wrong mental model and never knows.
Failure mode share, gpt-4o vs gpt-5.2. Total failures drop on the model upgrade, but CONFUSED_IDENTITY rises from 35% to nearly half — confidently-wrong answers become the dominant failure mode.
Two oddball examples worth featuring. **gpt-5.2 misidentifies "Nitrode" as a fictional Roman character from Petronius's *Satyricon*** (the "Widow of Ephesus" tale), confidently presenting it as the most likely meaning before the modern fintech. Generic-but-Latin-sounding names introduce a new failure mode we are calling scholarly hallucination. **"Spott" gets identified as a Belgian video-tech company by gpt-5.2** (not the YC W25 recruitment ATS spott.io). No disclaimer, no hedge, just a confident description of the wrong company.
## Finding 3: Why do generic-named brands stay broken across model upgrades?
**Answer: even web search cannot disambiguate them from their famous-name collisions. Four brands in our cohort fail on both tests across both model generations.**
Four brands in the cohort fail CONFUSED_IDENTITY across **both** training-data and web-search tests, on **both** gpt-4o and gpt-5.2:
- **Bud** → describes Budweiser, Bud Financial, Bud Grant, "buddy" nickname
- **Forge** → describes Forge Global, ForgeRock, Atlassian Forge
- **Roark** → describes Howard Roark (Ayn Rand) and Roark Capital
- **Trim** → describes Trim fintech app, Trim County Ireland, TRIM SSD command
For these four, even web search could not disambiguate them from their famous-name collisions. **Generic naming is a Layer 1 visibility issue that no model upgrade is likely to fix.** A Series A startup with strong product traction stays invisible in AI when it's name collides with a famous fictional character (Roark, Forge), an established corporate trademark (Forge, Trim), or a common English word with strong semantic associations (Bud).
The implication is brutal but actionable. If your brand name is generic, every other Layer 1 fix you invest in (Wikipedia, schema, founder presence) has to work twice as hard to overcome the disambiguation problem AI is solving against you.
If you are still pre-launch and choosing a name, "uniquely searchable" should rank above "memorable" and "easy to spell." And if you have already named your company a common English word, the realistic Layer 1 strategy is to over-invest in disambiguation content. That means an unambiguous About page with structured Organization schema, a Wikipedia entry with explicit disambiguation, and third-party content that anchors your brand to a specific market or category.
## What does this mean for your AI visibility strategy?
Three takeaways from the data, each translating directly into where to spend the next quarter's AI visibility budget: invest in the Knowledge Graph foundation first because its the binding constraint, plan for the failure-mode shift toward CONFUSED_IDENTITY as models improve, and treat generic brand names as a structural visibility tax that no model upgrade will fix:
1. **Knowledge Graph first.** If you don't have a high-confidence Knowledge Graph entry, every other Layer 1 investment is downstream of fixing that. Submit your brand via structured Organization schema, build a Wikipedia entry, get cited in third-party publications that Google trusts as KG sources.
2. **Audit on multiple model generations, not one.** Picking a single LLM for your audit (typically the latest) hides regressions like the Celest case. Run the audit on at least two model generations and look at the overlap. The strict pass set across generations is your real Layer 1 score.
3. **Renaming is on the table for generic-named brands.** If your name is Bud, Forge, Roark, Trim, or any close analog, the Layer 1 disambiguation problem is structurally hard. Either commit to disproportionate disambiguation content investment for the next 18 to 24 months, or evaluate whether a partial rename would be cheaper.
For the broader audit framework, see the [4-step AI visibility audit](/blog/15-prompt-ai-visibility-audit). For the specific patterns this audit surfaced, see the [11 AI visibility failure modes guide](/blog/why-ai-ignores-your-brand-blindspots), which maps the CONFUSED_IDENTITY data to a fix-priority order.
## What were the limitations?
Honest accounting of where this audit falls short before someone else points it out — n=40 is directional rather than statistically powered for sub-segment claims, OpenAI-only LLM testing means Anthropic Claude and Google Gemini patterns may diverge, and Layer 1 alone is tested here (Layer 2 visibility and Layer 3 reccomendation are scoped to follow-up work):
- **OpenAI only.** Anthropic Claude and Google Gemini may have different recall profiles, different retrieval mechanics, different failure-mode distributions. A multi-LLM v2 of this audit is the natural next study.
- **Layer 1 only, prompt 1.1 only.** Layer 2 (visibility / leaderboard) and Layer 3 (recommendation) were not tested in this run. Within Layer 1, this audit ran only the most basic prompt (1.1 — "Who is [brand]?") against three retrieval mechanisms. The full Layer 1 prompt set (1.1 through 1.5) was not run; that scope is on the v3 backlog. The "30% pass" headline is a Layer 1 / prompt-1.1 number; brands that pass cleanly here may still fail prompts 1.2 through 1.5 or Layers 2 and 3.
- **40 brands is directional.** Statistical power for sub-segment claims (CRM vs analytics, G2 vs YC) requires a larger N. Treat the per-stratum numbers as suggestive, not authoritative.
- **Single-rater scoring.** No inter-rater reliability check. The PASS/WEAK_PASS/FAIL boundary on edge cases (e.g., "identifies the right company but with one wrong fact") was a judgment call.
- **Forced web_search on Test 3.** v2 forces tool use for fair comparison with `gpt-4o-search-preview`. Without forcing, gpt-5.2 sometimes skips the tool and answers from training data. Production deployments where tool use is optional would see lower web-search pass rates.
- **Brand selection method.** YC W24/W25 alphabetical-first-20 is reproducible but introduces selection bias toward names starting with letters early in the alphabet. A random sample would be more defensible.
We will re-run a v3 quarterly with these limitations addressed (multi-LLM, larger N, dual-rater scoring, random YC sample). The dataset link below is the v2 baseline.
## Frequently Asked Questions
### Did the gpt-4o → gpt-5.2 upgrade help any brands?
Yes, at the margin. Linear, Bezel, and Greptile flipped from FAIL to PASS on training-data recognition. crmCopilot, Ellipsis, and Firebender flipped from FAIL to PASS on web-search. Six brands recovered. One regression: Celest's web search ranking dropped (gpt-4o-search-preview ranked celest.dev as #4 in disambiguation; gpt-5.2 + web_search dropped it entirely). Net positive but not a wholesale shift.
### Why does the Knowledge Graph matter so much for LLM training?
Google Knowledge Graph entries (especially high-confidence ones) are widely used as canonical entity sources by LLM training pipelines. When training data ingests the open web, named entities with Knowledge Graph anchors get linked, deduplicated, and reinforced. Brands without that structural anchor end up as scattered text mentions that may or may not survive deduplication. The 12 brands that passed all three sub-tests in our cohort all had `resultScore` over 100 in the Google KG; the 6 brands with KG presence below that threshold all failed training-data recognition.
### How is this different from existing AI visibility studies?
Most existing studies measure Layer 2 (visibility / leaderboard) on prompts like "best CRM for startups." Omniscient Digital's [200-prompt analysis of 25,755 AI citations](https://beomniscient.com/blog/how-i-created-the-perfect-prompt-set-for-ai-visibility-research/) is the canonical example. Our audit measures Layer 1 (entity recognition) instead, which is the upstream constraint: brands that fail Layer 1 cannot show up in Layer 2 leaderboards regardless of how much off-site authority they have. The two studies are complementary; we are filling in a layer the existing literature has under-measured.
### Can I run this audit on my own brand?
Yes. The methodology is reproducible with about 30 minutes of setup and an OpenAI API key. We published the [4-step audit framework + 15 prompts](/blog/15-prompt-ai-visibility-audit) and the full prompt list. For the Knowledge Graph test, use the Google Knowledge Graph Search API. For the LLM tests, use OpenAI's `gpt-5.2` with `reasoning.effort=low` (training-data test, no tools) and the same model with `web_search` tool use forced (web-search test). The total cost per brand is about $0.02.
### Will you re-run this study?
Quarterly. The next iteration will expand to Anthropic Claude and Google Gemini, increase the sample size, use dual-rater scoring, and replace the alphabetical YC sample with a random one. The v2 baseline below is what you can cite today.
### Does Knowledge Graph presence guarantee LLM recall?
No. Six brands in our cohort had Knowledge Graph entries (PASS or WEAK_PASS on Test 1) but still failed training-data recognition on both models. All 6 had `resultScore` below 100. The threshold matters: barely-there KG presence does not appear to feed LLM training data reliably. A high-confidence KG entry (`resultScore` over 100) is the structural anchor that gates downstream visibility.
---
## Dataset access
The full audit dataset is published alongside this post for anyone who wants to reproduce the methodology or extend it with additional brands, categories, or LLMs. Raw response logs, per-brand scoring rationale, and the prompt set are included — apply the same scoring rubric we used or adapt it to your own definitions of recognition quality:
- **Master CSV.** One row per brand, all 40 rows, all test fields
- **Aggregate stats JSON.** Machine-readable summary numbers
- **Raw response logs.** Every LLM response for tests 2 and 3, both v1 and v2
If you cite the dataset in your own writing, please link to this post. For replication, the methodology section above plus the published prompts are sufficient to reproduce the run.
---
**Methodology footnote.** Audit conducted by friction AI, April 2026. 40 SaaS brands stratified into 20 G2 category leaders + 20 Y Combinator W24/W25 startups. Three Layer 1 sub-tests per brand: entity foundation via Google Knowledge Graph Search API; training-data recognition via OpenAI gpt-4o and gpt-5.2 (reasoning.effort=low, no tools); web-search recognition via the same models with `web_search` tool use forced. Single-rater scoring. Layer 2 and Layer 3 not in scope for this run. Total runtime: 1h 37min combined; total API cost: $0.87. Limitations enumerated in section above.
---
### Run this audit on your own brand
Want this 4-step audit running across ChatGPT, Claude, Perplexity, and Gemini on a continuous schedule — without doing the spreadsheet by hand?
**[▶ Start your free trial of friction AI →](https://www.frictionai.co/signup)**
Or grab the **[free 15-prompt starter pack →](https://www.frictionai.co/tools/aeo-starter-prompts)** and run the manual workflow tonight.
---
**About the author.** Joao da Silva is co-founder of [friction AI](https://www.frictionai.co) alongside Camilla Wirth. friction AI tracks brand visibility across ChatGPT, Claude, Perplexity, and Gemini for SaaS and DTC brands. Joao writes about AI search, entity recognition, and the operational side of getting recommended by LLMs. Connect with him on [LinkedIn](https://www.linkedin.com/in/joao-da-silva-v/).
---
# AI Visibility Audit: 15-Prompt LLM Audit Framework (2026)
# URL: https://www.frictionai.co/blog/15-prompt-ai-visibility-audit
# Slug: 15-prompt-ai-visibility-audit
# Category: Monitoring & Measurement
# Published: 2026-04-26
# Author: Joao Da Silva, Co-Founder of friction AI
# Keywords: AI Visibility, Answer Engine Optimization, Entity Recognition, ChatGPT, Claude, Perplexity, Generative Engine Optimization
# AI Visibility Audit: 15-Prompt LLM Audit Framework (2026)
By Joao da Silva · April 26, 2026 · Last updated May 18, 2026
> **TL;DR.** A real AI visibility audit is a 4-step framework, not a one-shot ChatGPT query: **set up your prompts, run and track, analyze and diagnose, fix and repeat**. Step 1 uses 15 starter prompts across 3 layers (entity recognition, visibility, recommendation). When we ran this on 40 SaaS brands in April 2026, only 30% cleanly passed Layer 1. Free 15-prompt template at the bottom — or [run the interactive version now](/tools/aeo-starter-prompts). Run it tonight.
📺 Watch the 4-step audit walkthrough on YouTube — full framework walkthrough, prompt setup, and diagnosis.
**[▶ Watch the full walkthrough on YouTube →](https://youtu.be/wWqbnLPGXQc)**
When we audited 40 SaaS brands' Layer 1 visibility across two GPT generations (gpt-4o and gpt-5.2), only 12 of 40 (30%) cleanly passed all three sub-tests ([full methodology + dataset](/blog/40-brand-ai-visibility-audit)). The bottleneck was not the model. The same 12 brands passed under both generations; the model upgrade did not move the number. The binding constraint was the Knowledge Graph entity, which does not change when you upgrade your LLM. Every dollar a team spends on Layer 2 and Layer 3 work is wasted while their Layer 1 entity foundation is missing, because AI cannot recommend a brand it cannot recognize.
This guide walks the **4-step audit framework** you can run yourself in under an hour, the [15 starter prompts](/tools/aeo-starter-prompts) you should track quarterly, and the playbook for what to fix once you see the results.
## What is an AI visibility audit?
An AI visibility audit is a structured test of how large language models (ChatGPT, Claude, Perplexity, Gemini) recognize, rank, and recommend your brand. It runs in four sequential steps: set up the right prompts, run and track responses across models, analyze the gaps, then fix and repeat. Quarterly cadence is the floor:
1. **Set up your prompts** — 15 starter prompts across 3 diagnostic layers (entity, visibility, reccomendation)
2. **Run and track** — execute prompts 3-5x across models, capture responses
3. **Analyze and diagnose** — read patterns; identify which layer is leaking deals
4. **Fix and repeat** — apply layer-specific fixes; re-run quarterly
Unlike a Google rank check, AI visibility is a moving target. Search interest in "AI Visibility" grew 11.5x in the 12 months ending April 2026, and "Answer Engine Optimization" grew 5.9x ([Google Trends, internal pull, Apr 2026](https://trends.google.com/)).
## How to audit brand visibility on LLMs (the short version)
**Brand visibility on LLMs** is the measurable share of category prompts where ChatGPT, Claude, Perplexity, or Gemini mentions your brand. Auditing it isn't a one-shot ChatGPT query — it's a 4-step framework: lock 15 starter prompts, run each 3-5 times across at least two LLMs, score per layer, then prioritize fixes by which layer is leaking deals. The full walkthrough is below.
## Why a 4-step audit, not a one-shot ChatGPT query?
One ChatGPT query is a single roll of a loaded die. AI responses vary across runs, models, and phrasings. In our 40-brand audit, individual brands flipped between PASS and FAIL across gpt-4o and gpt-5.2 — Linear was unrecognized by 4o but correctly identified by 5.2. A structured 4-step audit averaged across runs produces direction; a single query produces anxiety.
The reference work here comes from Omniscient Digital. Their team analyzed 25,755 AI citations across 200 prompts and identified five universal BoFu prompt patterns that generalize across e-commerce, SaaS, services, and healthcare ([Omniscient Digital, 2025](https://beomniscient.com/blog/how-i-created-the-perfect-prompt-set-for-ai-visibility-research/)). The takeaway is not that you need 200 prompts of your own. It is that the *shape* of a real audit is structured, repeated, and read across runs, not extracted from one screenshot.
Each step of the framework maps to a distinct discipline, and we have a dedicated deep-dive for each:
| Step | What it answers | Deep dive |
|---|---|---|
| 1. Set up your prompts | Which prompts should I run, and how do I write variants for my use case? | [How to write AI visibility prompts →](/blog/how-to-write-ai-visibility-prompts) |
| 2. Run and track | How do I run these across ChatGPT, Claude, Perplexity, and Gemini at scale? | [Track brand mentions in ChatGPT, Claude & Perplexity →](/blog/track-brand-mentions-across-ai-platforms) |
| 3. Analyze and diagnose | What do failure modes look like, and how do I read the pattern? | [Why AI ignores your brand: 11 failure modes →](/blog/why-ai-ignores-your-brand-blindspots) |
| 4. Fix and repeat | Where do I find new prompts to add as my buyers evolve? | [Find buyer questions for AI prompts →](/blog/find-buyer-questions-for-ai) |
Want to see the framework applied at scale? We ran it across 40 real SaaS brands and published the [40-brand AI visibility audit case study](/blog/40-brand-ai-visibility-audit) with full methodology, dataset, and findings.
## Step 1 — Set up your prompts (the prompt audit foundation)
Step 1 is **what you'll run** — picking prompts that map to real buyer queries, not marketing-voice phrasings. The 15-prompt universal starter set covers 3 diagnostic layers (entity recognition, visibility, recommendation), with 5 prompts per layer. Each prompt tests a distinct failure mode in how AI sees your brand.
The framework draws on two pieces of public research. Citation Labs identified four properties that make a BoFu prompt worth tracking: contrastive reasoning ("better," "worth it"), offer-anchoring (a specific brand named), category anchoring, and constraint clauses ([Citation Labs, 2025](https://citationlabs.com/tracking-worthy-bofu-prompts/)). Omniscient's five universal BoFu patterns slot into the same Layer 3 set: pricing, comparison, social proof, fit, and verdict. Both frameworks are reflected in the prompts below.
### What is an LLM prompt audit?
An **LLM prompt audit** is the prompt-design and execution portion of an AI visibility audit — Step 1 of the 4-step framework, where you lock the 15 starter prompts (5 per diagnostic layer) and any use-case variants before running them. The prompt set decides what you can diagnose; everything downstream (runs, analysis, fixes) inherits from this choice.
### The 15 universal starter prompts
| # | Layer | Prompt |
|---|---|---|
| 1.1 | Entity | Who is [your brand]? |
| 1.2 | Entity | What does [your brand] do? |
| 1.3 | Entity | Who founded [your brand]? |
| 1.4 | Entity | What is [your brand] known for? |
| 1.5 | Entity | Tell me about [your brand]'s product. |
| 2.1 | Visibility | What are the best [category] tools for [ICP]? |
| 2.2 | Visibility | Which [category] software is best for [use case]? |
| 2.3 | Visibility | What's the best [category] for [tight niche]? |
| 2.4 | Visibility | What [category] platforms are most popular right now? |
| 2.5 | Visibility | What tools help with [buyer's problem]? |
| 3.1 | Recommendation | How much does [your brand] cost? |
| 3.2 | Recommendation | How does [your brand] compare to [competitor]? |
| 3.3 | Recommendation | What do users say about [your brand]? |
| 3.4 | Recommendation | Is [your brand] good for [my use case]? |
| 3.5 | Recommendation | Is [your brand] worth it? |
Run each prompt three to five times, average the results, then read the patterns. Three runs is the minimum that surfaces variance; five gives you confidence on the top entry. Single-run readings are how marketers convince themselves they are winning when they are not.
### Layer 1: Entity Recognition — does AI know your brand exists?
Layer 1 is the foundation. It tests whether AI has your brand in its model at all, whether the description is accurate, and whether the founder, founding date, and product knowledge are right. Fail it, and Layers 2 and 3 are moot. In our 40-brand Layer 1 audit (April 2026, run on both gpt-4o and gpt-5.2), 28 of 40 brands (70%) had at least one Layer 1 failure ([full audit dataset](/blog/40-brand-ai-visibility-audit)). The most common failures were entity foundation missing (no Knowledge Graph entry) and a pattern called CONFUSED_IDENTITY: the LLM picking the wrong company with the same name and describing it confidently.
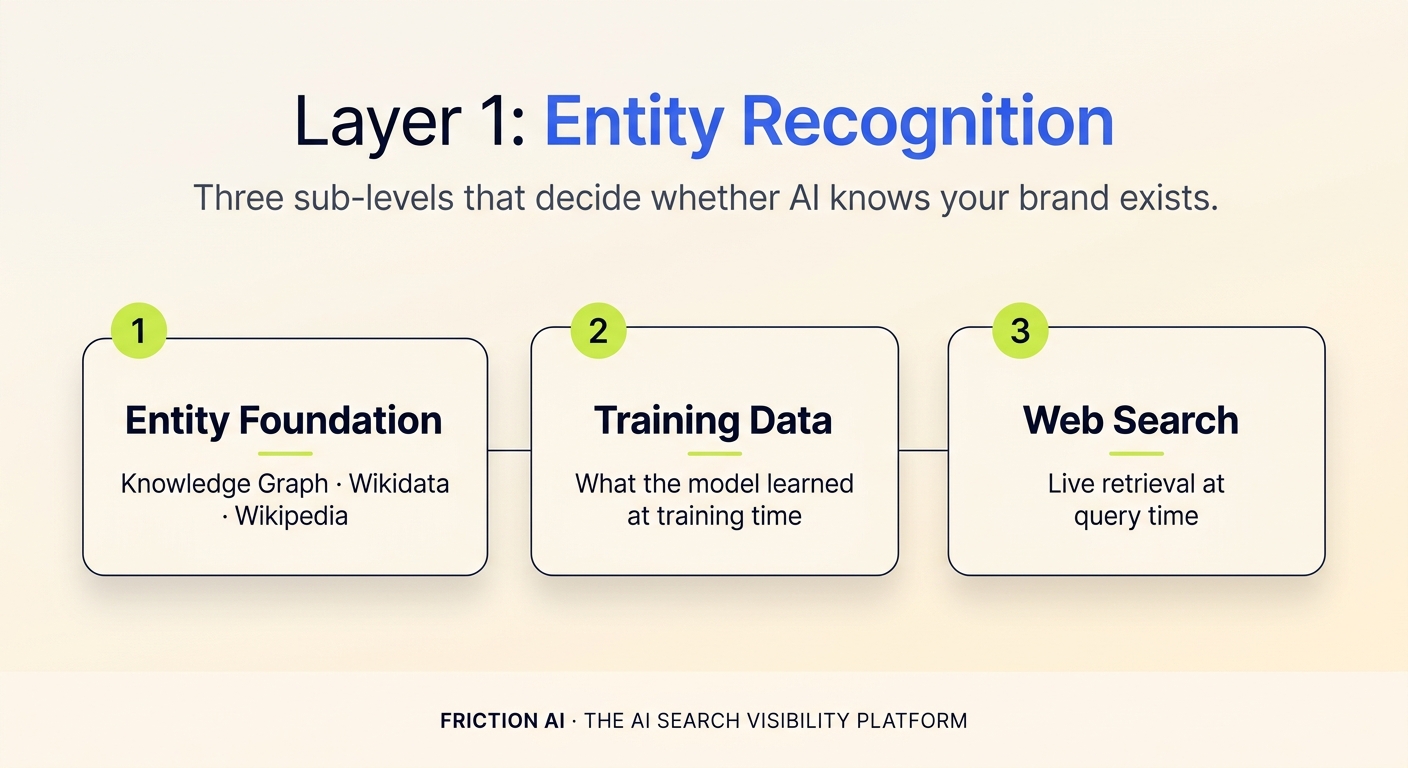
Layer 1 actually splits into three sub-levels, each with a different fix lever:
- **Entity foundation** is structural recognition. Does AI have you in its knowledge graph? Failure here means the fix is schema markup, Wikipedia presence, and structured data on your site.
- **Training data** is what AI learned historically, before its training cutoff. You cannot retroactively change what current models know, but you can influence future training rounds by publishing high-authority content now (12 to 24 month horizons).
- **Web search / live retrieval** is what AI fetches when search is enabled (ChatGPT Search, Perplexity, Claude with web). Failure here means a freshness gap: your indexable web footprint is thin or stale.
The five Layer 1 prompts each test a different dimension. **1.1 (Who is...)** tests *misidentification*. **1.2 (What does...do)** measures whether AI's first-sentence description matches your positioning. **1.3 (Who founded...)** surfaces hallucinated founders. **1.4 (What is...known for)** is the highest-leverage Layer 1 prompt — if "known for X" doesn't match what you're selling, third-party content is shaping the narrative without you. **1.5 (Tell me about...product)** reveals what AI *omits* — missing recent features signal stale training data.
### Layer 2: Visibility — where do you sit on the leaderboard?
Layer 2 is competitive intelligence in disguise. Every "best [category] for [ICP]" prompt reveals the leaderboard AI sees for that category, problem, or niche. The diagnostic value is not "do I show up?" (the passive question), it is "who does AI consider strongest in this space, and where do I rank against them?" (the active question). The active framing is what makes Layer 2 worth running quarterly.
Illustrative example of a Layer 2 audit response. What a ChatGPT answer to a Layer 2 prompt might look like for the AI visibility tooling category. Actual responses vary across runs, models, and prompt phrasings — this is not a verbatim screenshot.
Each Layer 2 prompt reveals a *different* leaderboard. These are not five versions of the same ranking — they are five competitive landscapes running in parallel:
- **2.1 (Best [category] for [ICP])** tests the head term plus your buyer segment.
- **2.2 (Best for [use case])** tests use-case specificity. A brand can win the head term and still lose use-case-specific queries.
- **2.3 (Best for [tight niche])** is where smaller brands often *win*. Niche dominance shows up even when the brand is invisible at the head term.
- **2.4 (Most popular right now)** tests temporal bias. AI defaults to incumbents.
- **2.5 (Tools that help with [buyer's problem])** tests problem-led discovery.
A brand can be #1 on the head term and invisible on the problem-led version. The pattern of where you DO rank versus where you don't tells you which content gap to close first. AI sources from Reddit, "best of" listicles, comparison sites, and podcast transcripts in addition to traditional SEO surfaces, and that mix can surface different brands than Google does.
### Layer 3: Recommendation — does AI pick you, and hide concerns?
Layer 3 is the selection filter — the layer where deals are won or lost in real time. By the time a buyer is at Layer 3, they already know you exist and they've surfaced you in there research. AI is the last filter before they commit. If it hedges, hallucinates pricing, or describes a competitor more favorably, you lose deals you almost won. And you never find out why.
Layer 3 splits into two distinct lenses, each diagnosing a different AI behavior:
**Lens 1 is the Favorite Test.** When forced to compare you against a named competitor, what does AI do? Tested by 3.2 and 3.5.
**Lens 2 is the Concerns Test.** When asked about you in isolation, what reservations does AI quietly surface? Tested by 3.1, 3.3, 3.4, and 3.5.
A brand can win Lens 1 (AI picks you head-to-head) and still lose Lens 2 because AI surfaces outdated complaints every time it describes you. A Layer 3 audit should produce two scores, not one.
| # | Prompt | Lens | Diagnoses |
|---|---|---|---|
| 3.1 | How much does [brand] cost? | Concerns | Pricing accuracy, hidden cost objections |
| 3.2 | How does [brand] compare to [competitor]? | Favorite | Head-to-head competitive framing |
| 3.3 | What do users say about [brand]? | Concerns | Outdated negative reviews surfacing |
| 3.4 | Is [brand] good for [use case]? | Concerns | Fit hedging vs. clean commitment |
| 3.5 | Is [brand] worth it? | Both | Verdict commitment plus surfaced caveats |
### When to write your own prompt variants
The 15 above are the universal starter set — they work for any SaaS brand. If your category has unique buyer language, multi-product complexity, or industry-specific intent, you'll want to write 8-12 use-case variants on top: sentiment-specific, competitor-specific, ICP-specific. We covered the deep-dive workflow in [how to write AI visibility prompts](/blog/how-to-write-ai-visibility-prompts).
## Step 2 — Run and track
Step 2 is **execution** — running each prompt 3-5 times across ChatGPT, Claude, and Perplexity, then capturing the responses for scoring. Whether you run by hand (about 45 minutes per brand per round) or use tooling, the core workflow follows the same five-step sequence below.
1. Plug your `[brand]`, `[category]`, `[ICP]`, `[competitor]` placeholders into the 15 prompts
2. Run each prompt 3-5 times in your model of choice
3. Run the full set in at least 2 platforms (start with ChatGPT, then Claude or Perplexity)
4. Capture each response — copy-paste into a doc, take a screenshot, or use an automated tracker
5. Score each prompt: pass, fail, or partial
The cross-model divergence is where Step 2 earns its keep. The same 15 prompts in ChatGPT, Claude, Perplexity, and Gemini can produce different leaderboards because each model has a different training mix and different live-retrieval logic. Cross-model agreement is anecdotally low; in our own testing, the top-brand pick diverges substantially across ChatGPT, Perplexity, and Claude. A rigorous cross-model study with published n is on our v3 audit backlog.
### Doing this at scale
Running 15 prompts × 3-5 runs × 4 platforms quarterly = 180-300 manual queries per audit cycle. Most teams burn out at run 2. We covered the workflow for tracking this continuously across platforms in [how to track brand mentions in ChatGPT, Claude & Perplexity](/blog/track-brand-mentions-across-ai-platforms), including the manual workflow, the failure modes of common spreadsheet approaches, and the automated alternatives.
## Step 3 — Analyze and diagnose
Step 3 is **reading the pattern** across runs. The audit produces three signals per brand: per-layer pass rate (how often AI recognizes / ranks / recommends you), per-prompt failure mode (the specific pattern that's breaking), and per-platform divergence (where ChatGPT, Claude, and Perplexity disagree). The combination tells you which layer is leaking deals.
### What our 40-brand audit found
Three findings from running the Step 1 + Step 2 workflow on 40 SaaS brands across two GPT generations:
**1. The Knowledge Graph is the binding constraint, and it does not move with model upgrades.** The same 12 brands cleanly passed all three sub-tests on both gpt-4o and gpt-5.2:
- HubSpot, Pipedrive (CRM)
- Asana, Monday.com, Notion, ClickUp (project management)
- Mixpanel, Amplitude, Heap, Hotjar (product analytics)
- Copy.ai, Writesonic (AI content)
All 12 have high-confidence Knowledge Graph entries (resultScore over 100). The model upgrade improved recall, but the Layer 1 strict pass count was identical. For a brand pursuing AI visibility, fixing the Knowledge Graph entity is the highest-leverage Layer 1 action; it gates everything downstream.
**2. As LLMs get better at recall, the failure mode shifts from "never heard of you" to "wrong company with your name."** On gpt-4o, NOT_RECOGNIZED ("I'm not familiar with...") accounted for 65% of Layer 1 failures. On gpt-5.2, that dropped to 52%, while CONFUSED_IDENTITY rose to nearly half of all failures ([40-brand audit, April 2026](/blog/40-brand-ai-visibility-audit)). As model recall improves, generic brand naming becomes the dominant failure mode. This is the bad kind of progress: a confidently wrong answer is more dangerous than an honest "I don't know."
**3. Generic-named brands stay broken across model upgrades.** Four brands in the cohort (Bud, Forge, Roark, Trim) fail CONFUSED_IDENTITY on both training-data and web-search tests, on both gpt-4o and gpt-5.2. The model picks Howard Roark, Atlassian Forge, Trim County in Ireland. Even a Series A startup with strong product traction stays invisible in AI when its name collides with a famous fictional character or an established corporate trademark. Generic naming is a Layer 1 visibility issue that no model upgrade is likely to fix.
### Common failure modes to look for
Beyond the 3 macro findings above, individual posts surface specific failure patterns: pricing hallucination, comparison ordering bias, outdated negative reviews, the hedge ("It depends..."), CONFUSED_IDENTITY, missing recent features. We cataloged the [11 most common AI visibility failure modes](/blog/why-ai-ignores-your-brand-blindspots) — read this before your first audit so you know what to look for in the response patterns.
### Methodology validated at scale
If you want the full dataset and methodology behind the findings above — sample frame, scoring rubric, sub-test definitions, raw response logs, and limitations — see the [40-brand AI visibility audit case study](/blog/40-brand-ai-visibility-audit). It's the proof-of-method for everything in this guide.
## Step 4 — Fix and repeat
Step 4 is **sequencing your fixes** in the right order. The diagnostic value of the audit collapses to zero if you fix the wrong layer first: Reddit content campaigns are wasted while AI doesn't yet recognize your brand, and PR investments take 60-90 days to register in AI's training and retrieval surfaces.
### Prioritization
Fix Layer 1 first, even if Layers 2 and 3 look worse on paper. The reason is sequencing. Layer 1 fixes (Wikipedia, schema, founder presence) compound forward into Layer 2 and 3 visibility, while Layer 2 and 3 fixes do nothing for Layer 1. Spending on a Reddit content campaign before AI knows your brand exists is a waste.
Once Layer 1 is clean, prioritize Layer 2 work for your three weakest prompts (the ones where you are invisible), not your three strongest. The marginal return on closing a visibility gap is higher than the marginal return on improving an existing rank. Save Layer 3 fixes for last because they are the slowest to compound; PR cycles, fresh reviews, and updated case studies show up in AI's answers on 60 to 90 day lags.
The second-order point on Layer 3 is that fixing it almost always means more PR, not more on-page SEO. Off-site authority compounds slowly, and the brand reputation AI sees lags reality by 1 to 3 quarters. Search Engine Land made this case directly: [PR is becoming more essential for AI search visibility than traditional optimization](https://searchengineland.com/why-pr-is-becoming-more-essential-for-ai-search-visibility-455497) because AI reads the entire web and weights publication authority.
### How often should you re-run the audit?
Quarterly is the minimum. Monthly is right if your category is hot or your competitive landscape is shifting fast. AI's answers move every few weeks as content gets indexed and competitors enter, so a one-time audit is data, but a recurring audit is direction. The pattern of *which* prompts shift over time tells you whether your investments are working. If Layer 2 prompts improve quarter over quarter while Layer 3 stays flat, your off-site authority work is paying off, but your validation surface still has gaps.
Quarterly trend in AI search interest, Q2 2025 to Q1 2026. "AI Visibility" grew 11.5× over the period, the fastest-growing of the AI-search-adjacent terms tracked.
You should also run the audit across multiple models.
The category itself is maturing fast enough that tooling has shifted. Peec AI raised $21M Series A in November 2025 to build out an Actions feature. Profound is building enterprise multi-model tracking. Semrush AI Visibility Toolkit and Ahrefs Custom Prompt Tracking shipped to existing customer bases in the same window. Re-run after every major model update (GPT, Claude, or Gemini); earlier results may not transfer.
### Finding new prompts as your buyers evolve
The [15 starter prompts](/tools/aeo-starter-prompts) are universal but static. Your buyers' questions evolve quarterly: new objections surface in sales calls, new comparison brands enter the market, new use cases emerge in support tickets. We laid out the playbook for mining real buyer language from Reddit, sales calls, and support tickets in [find buyer questions for AI prompts](/blog/find-buyer-questions-for-ai). Run this every 60-90 days to keep your audit current.
## The free 15-prompt template (copy-paste version)
Two ways to run this: copy the block below into a doc and fill in `[brand]`, `[category]`, `[ICP]`, `[use case]`, `[tight niche]`, `[buyer's problem]`, `[competitor]` yourself, or grab the [free interactive 15-prompt tool](/tools/aeo-starter-prompts) (no signup) to drop into ChatGPT, Claude, or Perplexity. Then run each prompt 3 to 5 times in your model of choice and average the readings. The whole audit fits in about 45-60 minutes for a single brand.
```
Layer 1 — Entity Recognition (run with web search OFF first, then ON)
1.1 Who is [your brand]?
1.2 What does [your brand] do?
1.3 Who founded [your brand]?
1.4 What is [your brand] known for?
1.5 Tell me about [your brand]'s product.
Layer 2 — Visibility (no brand name in any prompt)
2.1 What are the best [category] tools for [ICP]?
2.2 Which [category] software is best for [use case]?
2.3 What's the best [category] for [tight niche]?
2.4 What [category] platforms are most popular right now?
2.5 What tools help with [buyer's problem]?
Layer 3 — Recommendation (run head-to-head against your top 3 competitors)
3.1 How much does [your brand] cost?
3.2 How does [your brand] compare to [competitor]?
3.3 What do users say about [your brand]?
3.4 Is [your brand] good for [my use case]?
3.5 Is [your brand] worth it?
```
Score each prompt simply: pass, fail, or partial. Aggregate by layer. The pattern is the audit. If you would rather automate the run across ChatGPT, Claude, and Perplexity in parallel and track scores quarterly without doing it by hand, that is the problem [friction AI](https://www.frictionai.co) was built to solve. The manual workflow above is genuinely enough to get a first read.
## Frequently Asked Questions
Common questions brand teams ask after running their first AI visibility audit, with answers grounded in the 4-step framework, the 40-brand cohort study, and pattern data across thousands of LLM runs. Skim for what matches the gaps you're seeing in your own audit results.
### How do I audit brand visibility on LLMs?
Brand visibility on LLMs is the share of category prompts where ChatGPT, Claude, Perplexity, or Gemini mentions your brand. To audit it, run a 4-step framework: lock 15 starter prompts across 3 diagnostic layers (entity recognition, visibility, recommendation), execute each prompt 3-5 times across at least two LLMs, score per layer, then prioritize fixes by which layer is leaking the most deals.
### What is an LLM prompt audit?
An LLM prompt audit is the prompt-design and execution portion of an AI visibility audit. You lock a set of 15 universal starter prompts plus optional use-case variants, run each one 3-5 times across ChatGPT, Claude, Perplexity, and Gemini, then score responses by diagnostic layer. The prompt set decides what you can diagnose — everything downstream (runs, analysis, fixes) inherits from this choice.
### How do I do an AI visibility audit step by step?
Four sequential steps. Step 1: set up your prompts (use the 15 starter prompts or write 8-12 use-case variants). Step 2: run and track (execute each prompt 3-5 times in ChatGPT, Claude, Perplexity, Gemini, log mentions per platform). Step 3: analyze and diagnose (read per-layer pass rates, identify which layer is leaking deals). Step 4: fix and repeat (apply layer-specific fixes — schema, third-party PR, comparison content — re-run quarterly).
### How do I run an AI visibility audit for a B2B SaaS company?
Use the 15-prompt framework with B2B SaaS placeholders: [brand] = your tool, [category] = your software vertical (CRM, project management, analytics), [ICP] = your buyer segment (Series A founders, mid-market RevOps, enterprise CTOs). Run across ChatGPT, Gemini, and Perplexity (B2B buyers use all three: ChatGPT for solo research, Gemini for Google ecosystem, Perplexity for sourced citations). Add 2-3 vertical-specific prompts (integration questions, pricing tiers, free-trial fit).
### What's the difference between AI visibility, AEO, and GEO?
AI visibility is the broad term for how brands appear in AI answers. Answer Engine Optimization (AEO) is the optimization discipline that improves citation in answer engines like ChatGPT, Perplexity, and Google AI Overviews. Generative Engine Optimization (GEO) is the same thing under a different name, used more often in academic and SEO-tool contexts. All three solve for the same outcome: AI mentions your brand when buyers ask.
### How long does fixing Layer 1 entity recognition take?
Structural fixes (schema markup, Wikipedia, knowledge graph submissions) can show up in AI's web-search answers within days to weeks. Training-data fixes (what AI knows without web search) take 12 to 24 months because they only flow into the next training cycle. Web-search fixes (fresh content, recent press) appear fastest. Most teams see meaningful Layer 1 movement within a quarter if they prioritize the structural and live-retrieval levers together.
### Should I run this audit on ChatGPT, Claude, or Perplexity first?
Start with whichever model your buyers use most, and that is usually ChatGPT for B2B SaaS audiences. Once you have a baseline, run the same 15 prompts in Claude and Perplexity. Cross-model variance is the second-most useful signal in the audit, because a leaderboard that agrees across all three is a much stronger signal of true rank than one that only shows up in ChatGPT.
### Is the 4-step audit enough for enterprise brands?
The 4-step framework with 15 starter prompts is the universal core. Enterprise brands with multiple products, multiple ICPs, or multiple geographies should run a separate audit per product or segment, not stack everything into one. Add 1 to 2 vertical-specific prompts on top (free trial questions for SaaS, shipping questions for e-commerce, insurance questions for healthcare). The framework holds; the inputs change.
### Can I run this audit for free?
Yes. The manual workflow above costs nothing besides your time and a ChatGPT, Claude, and Perplexity account. Each platform has a free tier that supports the 15 prompts. Tooling automates the run across models, tracks results quarterly, and flags shifts, which matters at scale; it is not required to get a first read.
### How does this differ from traditional SEO ranking checks?
Traditional rank tracking watches one thing: your position on Google for a keyword. The 4-step AI visibility audit watches three: whether you exist in the model, where you rank in AI's answer mix, and whether AI commits to recommend you. AI sources from Reddit, podcasts, and comparison sites in addition to traditional SEO surfaces, so a brand can rank #1 on Google and be invisible in ChatGPT (and the reverse). Both audits are useful; they measure different things.
### What if my brand has multiple products or ICPs?
Run the audit per product, not per parent brand. ChatGPT might know HubSpot the company perfectly and be vague on HubSpot Marketing Hub specifically. Same for multi-ICP brands: if you sell to startups and enterprise, run separate audits because buyer language and AI's recommendation patterns shift completely between segments. The 15 prompts stay the same; the `[brand]`, `[category]`, and `[ICP]` inputs change per audit.
---
**Methodology footnote.** Layer 1 statistics in this post come from a 40-brand cohort audit conducted by friction AI in April 2026. Full methodology, dataset, raw response logs, and limitations live in [the case study writeup](/blog/40-brand-ai-visibility-audit). Quick version:
- **Sample (n=40):** stratified across 20 G2 category leaders (CRM, project management, product analytics, AI content) and 20 Y Combinator W24/W25 B2B SaaS startups. The "average SaaS brand" is neither; the headline 30% pass rate is read against this specific sample frame, not the universe of all SaaS.
- **Three sub-tests per brand:** entity foundation via the Google Knowledge Graph Search API, training-data recognition via OpenAI gpt-4o and gpt-5.2 (no tools), web-search recognition via the same models with `web_search` tool use forced.
- **Prompt scope:** the LLM tests used a single brand-anchored prompt ("Who is [brand]?") corresponding to prompt 1.1 of the 15-prompt framework. Prompts 1.2 through 1.5 were not run in this cohort.
- **Scoring:** single-rater, no inter-rater reliability check. 40 brands is directional rather than statistically powered for sub-segment claims.
- **Out of scope:** Layer 2 (visibility) and Layer 3 (recommendation) were not tested. Other LLMs (Anthropic Claude, Google Gemini) were not tested.
---
### Run this audit on your own brand
Want this 4-step audit running across ChatGPT, Claude, Perplexity, and Gemini on a continuous schedule — without doing the spreadsheet by hand?
**[▶ Start your free trial of friction AI →](https://www.frictionai.co/signup)**
Or grab the **[free 15-prompt starter pack →](https://www.frictionai.co/tools/aeo-starter-prompts)** and run the manual workflow tonight.
---
**About the author.** Joao da Silva is co-founder of [friction AI](https://www.frictionai.co) alongside Camilla Wirth. friction AI tracks brand visibility across ChatGPT, Claude, Perplexity, and Gemini for SaaS and DTC brands. Joao writes about AI search, entity recognition, and the operational side of getting recommended by LLMs. Connect with him on [LinkedIn](https://www.linkedin.com/in/joao-da-silva-v/).
---
# How to Write AI Visibility Prompts: 12 Templates (2026)
# URL: https://www.frictionai.co/blog/how-to-write-ai-visibility-prompts
# Slug: how-to-write-ai-visibility-prompts
# Category: Monitoring & Measurement
# Published: 2026-04-26
# Author: Joao Da Silva, Co-Founder of friction AI
# Keywords: AI Visibility, Answer Engine Optimization, Prompt Engineering, Buyer Research, ChatGPT, Claude, Perplexity
# How to Write AI Visibility Prompts: 12 Templates (2026)
By Joao da Silva · April 26, 2026 · Last updated May 18, 2026
> **TL;DR.** The [4-step AI visibility audit pillar](/blog/15-prompt-ai-visibility-audit) ships with 15 universal starter prompts. They work for any SaaS brand. This post is **the Step 1 deep-dive**. It covers 12 use-case-specific prompt templates: sentiment, competitive, ICP-specific, long-tail discovery. Layer them on top once you know which audit layers are underperforming. Inside: five principles for writing your own, plus a 60-minute exercise to lock your custom set.
A bad prompt set produces clean-looking data that diagnoses nothing. The audit comes back, the dashboard fills in, the team agrees the brand is "doing okay" in AI search, and three quarters later the pipeline gap quietly traces back to a prompt set that was measuring the wrong things from day one.
Prompt selection is the single highest-leverage decision in the audit, and it is the one most teams default through.
## Why these prompts aren't in the pillar's 15
The pillar's [15 starter prompts](/tools/aeo-starter-prompts) cover the **universal recognition, visibility, and recommendation layers**. They work for any SaaS brand — regardless of category, ICP, or competitive landscape. They're the right starting point for everyone. Most teams get directionally accurate data within their first 45-minute audit round using just that universal set.
This post goes deeper. The 12 templates below are **use-case-specific variants**. Layer them on top once you've run the universal set. By then you know which layers — or which prompts within a layer — are underperforming. Sentiment-specific, competitor-specific, ICP-specific, long-tail-discovery: these variants turn a directional audit into a precise diagnostic for your market.
Use this post when:
- You've run the pillar's 15 starter prompts and want to drill into a weak signal.
- Your category has unique buyer vocabulary. Generic "best X" framing misses it.
- You operate across multiple ICPs or product lines. You need segment-specific prompts.
- A competitor has launched. You want to test how AI frames the comparison.
Skip this post (and stick with the [pillar's 15](/tools/aeo-starter-prompts)) when you're running your **first** audit. The universal set is enough for a first read; come back here once you know which layers need a deeper look.
## The 5 principles behind every good prompt
Before the 12 templates, the framework that shapes them. These five principles tell you why the templates are built the way they are. More importantly, they tell you how to write your own variants. Use them when the templates don't quite fit your category vocabulary, your ICP segmentation, or your competitive landscape.
### Principle 1: Search like your customer
The most common audit mistake: testing buyer queries you imagine, sanitized through your own positioning vocabulary. Real prospects don't talk that way. Omniscient Digital analyzed 25,755 AI citations across 200 prompts and found the most-cited content mirrors buyer-language phrasing, not category-jargon phrasing ([Omniscient Digital, 2025](https://beomniscient.com/blog/how-i-created-the-perfect-prompt-set-for-ai-visibility-research/)).
The gap between what you think buyers ask and what they actually type is where most audit blind spots live. Never write prompts from imagination. Pull them from real artifacts. The [tactical guide to finding buyer questions](/blog/find-buyer-questions-for-ai) walks through where to mine each: subreddit thread titles, sales call recordings, support ticket openers.
### Principle 2: Lead with problems, not categories
Buyers know their pain. They don't know your category. A prospect doesnt think "I need a CRM" — they think "I keep losing track of leads." Problem-led prompts surface a different (and often more honest) leaderboard than category-led ones.
Citation Labs identified four properties that make a BoFu prompt worth tracking ([Citation Labs, 2025](https://citationlabs.com/tracking-worthy-bofu-prompts/)): contrastive reasoning ("better," "worth it"), offer-anchoring, category anchoring, and constraint clauses. Problem-led framing satisfies the constraint-clause criterion most cleanly.
The diagnostic test: write the same intent two ways. Once category-led ("What are the best CRMs for SaaS startups?"). Once problem-led ("What tool helps a small SaaS team stop losing leads in their inbox?"). The gap between them tells you whether your homepage is written in marketing language or buyer language.
### Principle 3: Be conversational, not Google-shaped
Write prompts as full questions, the way ChatGPT was built to be used, not as Google-style fragments. "best CRM SaaS" is a Google fragment a buyer might type into Google. "What's the best CRM for a small SaaS team in 2026?" is what they actually send to ChatGPT. LLMs respond to context — full sentences with team size, current tool, constraint clauses produce different (and more useful) answers than keyword fragments. HubSpot's [Answer Engine Optimization guide](https://www.hubspot.com/products/aeo) makes the same point in different language: prompts that work for tracking are the ones a real buyer would type, not the ones a marketer would write.
### Principle 4: Use buyer language, not marketing copy
Mine sales call transcripts. Skip your brand decks. The vocabulary your prospects use when they don't know your brand exists — that's the prompt to test.
Even teams that build audits around real buyers sometimes rewrite the buyer's language into "cleaner" marketing-friendly versions. Don't. Ahrefs' [Dec 2025 study of 75,000 brands](https://ahrefs.com/blog/why-chatgpt-cites-pages/) found branded web mentions correlate 0.656-0.709 with AI visibility. The mentions that compound are the ones in real buyer voice — Reddit threads, comparison posts, podcast transcripts — not the ones in marketing language.
The best two sources of buyer language: sales call transcripts (ask three AEs for top 10 discovery questions if you don't have Gong/Chorus/Fireflies) and first-touch support tickets (filter Intercom/Zendesk for openers from your last 50 signups).
### Principle 5: Mix branded and non-branded deliberately
Branded prompts test how AI represents you — validation, comparison, reviews. Non-branded prompts test whether AI surfaces you at all when the buyer isn't searching by name. Both matter. They reveal different failure modes.
Most teams over-test branded and under-test non-branded. A balanced audit lands at roughly **60% non-branded** prompts. If yours is below that, your data is biased toward false confidence at the top of funnel.
Our [40-brand AI visibility audit](/blog/40-brand-ai-visibility-audit) found that 28 of 40 brands (70%) had at least one Layer 1 failure on brand-anchored prompts alone. The non-branded surface is where the deeper category-level gaps sit. Search Engine Land's case that [PR is becoming more essential for AI search visibility than traditional SEO](https://searchengineland.com/why-pr-is-becoming-more-essential-for-ai-search-visibility-455497) underscores why.
## What this looks like applied: 3 mini case studies
Before the 12 templates, three short patterns we see most often when teams run use-case-specific prompts on their own brand. Each maps to one of the 12 templates and shows the diagnostic value of writing the variant instead of relying on the universal set alone.
### Pattern 1: The "wrong category" trap (Prompt 1 surfaces it)
A brand wins the head-term recommendation ("best [category] tools") but fails the vertical-scoped discovery prompt ("What companies offer [category] for [vertical]?"). The Knowledge Graph categorizes the brand for one category. The buyer is asking about an adjacent one. In our 40-brand audit, this pattern showed up in 8 of 40 brands. They passed Layer 1 cleanly. They disappeared the moment the prompt added a vertical qualifier.
**Fix priority:** vertical-anchored content (publication features in vertical-specific outlets, comparison content that names the vertical, customer case studies tagged by industry).
### Pattern 2: The outdated-negative loop (Prompt 5 surfaces it)
A brand has fixed a major product pain point but AI is still surfacing complaints from 12-18 months ago. The brand thinks the issue is gone; AI's training data says otherwise. The asymmetric "Prompt 5 — Negative sentiment surfacing" forces AI to commit to negatives where the pillar's neutral "what do users say" prompt usually hedges.
**Fix priority:** fresh G2/Capterra reviews that explicitly address the resolved issue, updated case studies, podcast appearances with founders correcting the narrative. PR cycles register in AI's answers on 60-90 day lags.
### Pattern 3: The naming-collision invisibility (Prompts 1 + 4 surface it)
A brand shares a name with a larger entity in a different category. TALA the UK athleisure brand is the canonical case — its Knowledge Graph entry resolves to a Filipino fintech. Prompt 1 (Vertical-scoped discovery) and Prompt 4 (Positive sentiment) both surface the collision. The LLM either skips the brand entirely or describes the wrong entity's attributes.
**Fix priority:** explicit disambiguation content with KG-recognized signals (Wikipedia entry with disambiguation, consistent vertical-tagged third-party coverage), and a Google Knowledge Graph disambiguation request if the conflict is severe.
## The 12 templates, grouped by use case
Each template below has four parts. The prompt itself (copy-paste ready). When to run it (specific diagnostic scenario). What signal to look for in AI's response. How it differs from the pillar's 15 starter set. Replace bracketed placeholders (`[brand]`, `[category]`, `[ICP]`, `[competitor]`, etc.) with your own variables before running.
### Brand awareness (3 prompts) — non-branded discovery
These are the prompts buyers run **before** they know your brand exists. They reveal whether AI surfaces you in your category's discovery layer.
**Prompt 1 — Vertical-scoped discovery**
```
What companies offer [category] for [vertical/ICP]?
```
*When to run it:* You suspect AI surfaces general category leaders but misses your vertical positioning. *Signal:* Is your brand in the first 5 named? If not, your vertical-specific positioning is invisible to AI. *Different from pillar:* The pillar's 2.1 ("best [category] tools for [ICP]") is more recommendation-shaped; this is pure discovery-shaped. *Example surface:* a B2B SaaS brand serving "sales teams at fintech startups" might pass the head-term audit cleanly but fail this prompt — AI returns CRM giants (HubSpot, Salesforce) instead of the vertical-specific player.
**Prompt 2 — Up-and-coming alternatives**
```
Who are the up-and-coming alternatives to [established player] in [category]?
```
*When to run it:* You're a newer entrant in a category dominated by incumbents and want to test whether AI recognizes the "alternative" framing. *Signal:* Are you listed? In what position? *Different from pillar:* Targets temporal/recency bias directly, which Layer 2 of the pillar only indirectly tests via 2.4. *Example surface:* Gymshark surfaces in 41% of athleisure recommendation prompts despite a low KG resultScore (277) — its strong alternative-framing presence in fashion/fitness publications closed the visibility gap that pure KG strength didn't.
**Prompt 3 — Persona-and-outcome discovery**
```
I'm a [persona role] looking for [specific outcome]. What tools or platforms should I evaluate?
```
*When to run it:* You want to see whether AI's discovery answer matches your ICP positioning. *Signal:* Does AI describe tools using language that matches your homepage, or in completely different vocabulary? *Different from pillar:* First-person framing elicits more advisory responses; pillar prompts are mostly third-person. *Example surface:* if your homepage positions you as "the platform for product-led growth" but AI describes you as "a generic analytics tool," the vocabulary gap is where buyers slip away — third-party content uses the generic framing, not yours.
### Sentiment (2 prompts) — perception-focused
These test how AI characterizes the sentiment around your brand, which is where outdated negatives and missing positives surface.
**Prompt 4 — Positive sentiment surfacing**
```
What do experienced users of [your brand] love most about it?
```
*When to run it:* You've shipped a new flagship feature and want to test whether AI's positive narrative has caught up. *Signal:* Does AI cite specific features? Recent ones? Or generic strengths that could apply to any competitor? *Different from pillar:* The pillar's 3.3 ("what do users say") is sentiment-neutral; this isolates the positive layer. *Example surface:* if AI lists "strong reporting" and "good customer support" — generic strengths — instead of your shipped-last-quarter AI-assistant feature, your release cycle is outrunning your third-party content cycle by 60-90 days.
**Prompt 5 — Negative sentiment surfacing**
```
What are the most common complaints about [your brand]?
```
*When to run it:* You've fixed a major pain point in the last 6-12 months and want to test whether outdated negatives still surface. *Signal:* Are complaints AI surfaces still accurate? Or are they referring to issues you've resolved? *Different from pillar:* Forces AI to commit to negatives where the pillar's 3.3 hedges. The most actionable single sentiment prompt — what surfaces here is what's costing you deals. *Example surface:* a SaaS brand that fixed mobile-app reliability in Q4 may still see "the mobile app crashes frequently" surface as a top complaint because AI's training corpus and live web index both lag the fix by 6-12 months.
### Competitive comparison (3 prompts) — head-to-head
These go deeper than the pillar's single 3.2 comparison prompt by testing different angles of competitive framing.
**Prompt 6 — Use-case-anchored comparison**
```
[Your brand] vs [competitor]: which is better for [specific use case]?
```
*When to run it:* You and your competitor both serve a category but specialize in different use cases. *Signal:* Does AI correctly attribute your specialty? Or describe you as a generic alternative? *Different from pillar:* The pillar's 3.2 is open-ended ("how does X compare to Y"); this forces a verdict for a specific scenario. *Example surface:* run this for Mixpanel vs Amplitude on "product analytics for mid-market mobile-first companies" and the verdict reveals which brand has invested in mobile-vertical use-case content — the loser shows up as the generic option.
**Prompt 7 — Switching narrative**
```
Why do customers switch from [competitor] to [your brand] (or vice versa)?
```
*When to run it:* You want to test whether AI surfaces your switching wins (or your competitor's). *Signal:* Does AI cite real switching reasons, or generic differentiators? Bidirectional framing reveals which direction has stronger third-party content. *Different from pillar:* Captures the migration narrative directly — none of the pillar's 15 prompts test this. *Example surface:* when AI consistently surfaces switching reasons in one direction only ("customers switch from A to B because X" but not the reverse), the asymmetry reflects where blog posts, case studies, and Reddit threads actually live — usually a sign that one brand has invested in switching-narrative content and the other hasn't.
**Prompt 8 — Multi-dimensional pricing comparison**
```
How does the pricing of [your brand] compare to [competitor] when you factor in [variable: scale, features, support]?
```
*When to run it:* You suspect AI is hallucinating prices or misrepresenting your pricing model. *Signal:* Are dollar amounts accurate? Is the "value" framing balanced? *Different from pillar:* The pillar's 3.1 tests pricing accuracy alone; this tests pricing-in-context, where most hallucinations actually happen. *Example surface:* a $99/seat tool getting described as "$300/seat" because AI is averaging price points across competitors in the same prompt — the multi-variable framing exposes the hallucination that single-brand pricing prompts miss.
### ICP-specific (2 prompts) — segment-targeted
These test whether AI surfaces you for specific buyer segments rather than just for category head terms.
**Prompt 9 — Multi-variable ICP fit**
```
What's the best [category] for a [team size] [vertical] team that needs [specific capability]?
```
*When to run it:* You serve a specific ICP and want to test whether AI's recommendation accuracy holds at that segmentation level. *Signal:* Are you in the top 3? With what description? *Different from pillar:* The pillar's 2.2 is "best for [use case]"; this stacks 3 variables (size + vertical + capability), which is closer to how real buyers actually query. *Example surface:* lululemon surfaces in 92% of athleisure recommendation prompts and 90% of stacked-variable variants for "yoga and running apparel for daily-wear urban professionals" — its content base anchors the brand specifically to that ICP, not just to the head term.
**Prompt 10 — Persona-and-stage match**
```
I'm a [persona role] at a [company stage]. What [category] tool should I pick to handle [job-to-be-done]?
```
*When to run it:* You target a specific persona-stage combination (Series A CMO, founder-led startup, enterprise CTO) and want to test whether AI matches you to that segment. *Signal:* Does AI recommend tools that actually fit that stage? *Different from pillar:* Pillar prompts don't stack persona+stage; this is the variant that surfaces stage-specific gaps. *Example surface:* a tool positioned for "Series B+ companies" may surface for founder-led queries and lose mid-market deals because AI doesn't have enough stage-anchored content to filter correctly.
### Long-tail discovery (2 prompts) — buyer-pain language
These mirror how buyers actually phrase queries when they don't know the category vocabulary yet.
**Prompt 11 — Pain-anchored discovery**
```
I'm struggling with [specific pain point]. What [category] tool can help me solve this?
```
*When to run it:* You want to test whether your brand surfaces for problem-led queries (Principle 2) at the long-tail end. *Signal:* Does AI translate the pain to your category and surface you? *Different from pillar:* The pillar's 2.5 ("tools that help with [problem]") is similar but doesn't include the first-person "struggling with" framing — a real buyer voice marker. *Example surface:* if a buyer types "I'm struggling with leads falling through the cracks" and AI returns generic CRM brands but not yours, your homepage and blog content haven't connected your category to that specific pain-language.
**Prompt 12 — Switch-from-legacy framing**
```
If I'm switching from [legacy approach: spreadsheets, manual process, competitor], what [category] should I consider that handles [migration concern]?
```
*When to run it:* You target buyers who are migrating from spreadsheets, manual processes, or a legacy competitor. *Signal:* Does AI surface you as a destination? With what migration framing? *Different from pillar:* Captures the migration intent specifically — high-conviction buyers who already know they need to switch. Zero pillar prompts test this. *Example surface:* a brand that markets "the Notion alternative for engineering teams" should surface on "switching from Notion" queries — if it doesn't, the switching-narrative content (migration guides, comparison posts, Reddit threads named after the legacy tool) hasn't been built yet.
## How to customize templates for your category
The 12 templates above are the universal starter library. Most SaaS and DTC brands can adapt them as-is. Your category may need extras: pricing-specific prompts for usage-based products, integration-specific prompts for ecosystem plays, regulatory-specific prompts for vertical SaaS. Three rules for writing your own:
1. **Anchor every variable in real buyer language.** If you're writing a prompt with `[specific pain point]`, pull the pain language from a Reddit thread or sales call transcript, not from your messaging doc.
2. **Test each new prompt 3 times before adding it to your tracked set.** If AI's responses vary wildly across 3 runs, the prompt is ambiguous — refine the variables before locking it in.
3. **Document the diagnostic intent.** For every prompt you add, write one sentence on what failure mode it diagnoses. If you can't articulate the diagnostic intent, the prompt isn't earning its slot in the audit.
## The 60-minute exercise to build your custom set
| Step | Time | Source | Output |
|---|---|---|---|
| 1 | 20 min | Read 10 sales call transcripts (or talk to 3 AEs) | ~15 buyer-language questions |
| 2 | 20 min | Scan top 30 thread titles in your category subreddit | ~20 question-shaped prompts |
| 3 | 10 min | Pull first messages from your last 50 support tickets | ~15 information-gap prompts |
| 4 | 10 min | Adapt 4-6 of the 12 templates above to your category vocabulary | ~6 use-case variants |
After 60 minutes you have ~55 candidates. Apply the 5 principles as filters. Cut anything in your marketing voice. Convert category-only candidates to problem-led variants. Force at least 60% non-branded. Make sure the conversational form matches what buyers actually type. What survives is your tracked audit set. Lock it, then run it across ChatGPT, Claude, and Perplexity alongside the pillar's 15 starter prompts.
## Where to run these prompts
The 12 use-case templates here layer on top of the pillar's 15 starter prompts. They dont replace them. Run both sets in parallel. Keep the universal 15 as your stable quarterly baseline — you need run-over-run comparison value. Add the 12 use-case variants when you need to drill into a specific signal that the universal set surfaces:
- **Pillar's 15 starter prompts** — your universal baseline. Re-run quarterly. You get stable run-over-run comparisons.
- **Spoke B's 12 use-case templates** — your deeper diagnostic. Run when you need to drill into a specific signal (sentiment drift, competitive shift, ICP gap).
The full multi-platform execution workflow is in [how to track brand mentions in ChatGPT, Claude & Perplexity](/blog/track-brand-mentions-across-ai-platforms). The buyer-language mining playbook is in [find buyer questions for AI prompts](/blog/find-buyer-questions-for-ai).
## Frequently Asked Questions
### How many AI visibility prompts should I track?
Start with the pillar's 15 universal starter prompts. Add 5-8 use-case variants from this post once you've identified which audit layer is your weakest. Above 30 total, the diagnostic value plateaus and the time cost becomes a tax on the workflow. The sweet spot for most brands is 20-25 prompts: 15 universal + 5-10 use-case-specific.
### Should I write prompts in the first or third person?
First-person framing ("Should I use X for my team?") tends to elicit more advisory, opinionated AI answers. Third-person framing ("Is X good for small teams?") tends to elicit more list-style answers. Test in the form your actual buyers use. If you don't know which form they use, run both for a few prompts and look at which response shape matches what your sales team hears in calls.
### How often should I refresh my custom prompt set?
Once you lock the set, don't change it. You need run-over-run comparison value. Refresh quarterly only if your category vocabulary has shifted — new competitor, new use case, new ICP. Otherwise the use-case variants stay stable. The pillar's 15 starter prompts essentially never change.
### What if my buyers don't use AI search yet?
Audit anyway. AI surfaces are a leading indicator. Buyers who don't use ChatGPT for evaluation today are typically using it within 6-12 months — as it gets embedded in workflows they already use (Notion AI, Google Workspace AI, Slack AI). The audit you run today is positioning for next year's buyer behavior, not just this quarter's.
### Can I use the same use-case templates across multiple products or business units?
No. Adapt each template per product or per ICP. ChatGPT might know HubSpot the company perfectly and be vague on HubSpot Marketing Hub specifically. Same applies to multi-ICP brands. Buyer language and AI's recommendation patterns shift completely between segments, so each segment needs its own set with its own buyer-language inputs.
### What's the difference between branded and non-branded prompts?
Branded prompts include your company name (e.g., "How does HubSpot compare to Salesforce?"). Non-branded prompts do not (e.g., "What are the best CRM tools for small SaaS teams?"). Branded prompts test validation and reputation. Non-branded prompts test discovery, which is where most large-volume buyer queries actually happen. A balanced audit needs both, weighted roughly 60-40 toward non-branded.
### What if my sales team doesn't have time to provide buyer questions?
Spend 30 minutes reading the most recent 20 thread titles in your category subreddit. The titles ARE the prompts; people type their problems literally as they think them. This is the single fastest substitute for sales-call mining and produces 70% of the same value in a fraction of the time.
### How do I know if a use-case variant is worth adding to my tracked set?
Three criteria. (1) It surfaces a different leaderboard from the pillar's universal version — cross-check by running both. (2) It produces consistent results across 3 runs (high-variance prompts are noise). (3) You can articulate one failure mode it diagnoses. If a prompt fails any of those three checks, drop it.
---
### Run this audit on your own brand
Want this 4-step audit running across ChatGPT, Claude, Perplexity, and Gemini on a continuous schedule — without doing the spreadsheet by hand?
**[▶ Start your free trial of friction AI →](https://www.frictionai.co/signup)**
Or grab the **[free 15-prompt starter pack →](https://www.frictionai.co/tools/aeo-starter-prompts)** and run the manual workflow tonight.
---
**About the author.** Joao da Silva is co-founder of [friction AI](https://www.frictionai.co) with Camilla Wirth. friction AI tracks brand visibility across ChatGPT, Claude, Perplexity, and Gemini. The clients are SaaS and DTC brands. Joao writes about AI search, entity recognition, and how to get recommended by LLMs. Connect with him on [LinkedIn](https://www.linkedin.com/in/joao-da-silva-v/).
---
# SEO and AEO Together: How to Run Both Without Doubling the Work
# URL: https://www.frictionai.co/blog/seo-and-aeo-together
# Slug: seo-and-aeo-together
# Category: AEO & GEO Guides
# Published: 2026-04-18
# Author: Joao Da Silva, Co-Founder of friction AI
# Keywords: seo and aeo together, seo vs aeo, aeo and seo strategy, integrate seo and aeo, seo and answer engine optimization, combined seo aeo workflow, seo aeo content strategy, aeo for seo teams, seo team adopting aeo, dual optimization seo aeo
# SEO and AEO Together: How to Run Both Without Doubling the Work
Most SEO teams treat AEO like a second job. It's not. Done right, AEO is what your existing SEO program produces almost for free, with three or four targeted additions.
## TL;DR
- SEO and AEO share most of their foundation. Quality content, technical accessibility, source authority, and freshness drive both.
- The divergence is in structure and signals: SEO rewards comprehensive pages with strong backlinks; AEO rewards extractable passages, structured data, and crawler accessibility for AI bots.
- A single content workflow can produce both outcomes if you plan for it. Bolt-on AEO work after the fact wastes effort.
- The real shift is measurement: SEO measures rankings and clicks; AEO measures citations, mentions, and recommendations across [the AI engines](/blog/aeo-explained-guide-2026).
- Most teams need one new tool ([an AEO platform](/blog/best-aeo-platforms-2026)) and a small change to their content brief, not a parallel team.
## The Shared Foundation
Strip the labels and roughly 70% of the work is identical. Both SEO and AEO reward the same fundamentals:
- **High-quality, original content.** Both Google's Helpful Content system and AI engines' source weighting demote thin or derivative content. Original research wins in both.
- **Technical accessibility.** A page Google can't crawl is also a page ChatGPT can't cite. Server-side rendering, clean robots.txt, sitemap hygiene, and schema markup all serve both purposes.
- **Source authority.** Authoritative domains earn higher Google trust signals AND get pulled more often as AI citations. Earning citations on Tier 1 publications doubles its value.
- **Freshness.** Both Google's freshness signals and AI engines' recency preferences favor recently updated content. A quarterly refresh schedule serves both.
- **Structured data.** Schema markup helps Google parse rich results AND helps AI engines disambiguate entities and key facts.
This is the asset base both disciplines stand on. If your SEO program already produces these things, you're 70% of the way to AEO.
## Where the Two Diverge
The other 30% is where teams trip up. Three differences matter most.
### Structure: Comprehensive Pages vs Extractable Passages
SEO rewards comprehensive coverage. The 3,000-word pillar that covers every angle of a topic outranks the 800-word post that covers one angle.
AEO rewards extractability at the passage level. AI engines pull a 60-word answer from your section and synthesize it into the response.
If your H2 buries the answer three paragraphs deep, the engine moves to a competitor with a sharper opener.
**The fix**: Write comprehensive pages with answer-first sections. Open every H2 with a 40 to 60 word direct answer. Then add the depth. SEO gets the long-form coverage it rewards; AEO gets the extractable passages it needs.
### Signals: Backlinks vs Citations
SEO weights backlinks. A page with 50 high-authority backlinks tends to rank above one with 5.
AEO weights citations and entity authority. AI engines care less about raw link volume and more about whether your domain shows up in the right contexts: industry publications, recognized analyst sites, trade press round-ups, Reddit and forum discussions where buyers actually compare options.
**The fix**: Stop chasing link volume from generic SEO directories. Focus link-building effort on Tier 1 publications and category-specific authorities. The same effort produces better results in both surfaces.
### Measurement: Rankings vs Recommendations
SEO measures rankings, organic clicks, and keyword positions. [SEO and AI visibility answer different questions](/blog/why-great-seo-still-does-not-give-your-brand-visibility-in-ai): a ranking dashboard shows where a page sits on Google, while an AI visibility audit records whether a brand appears in generated answers.
AEO measures citation share, mention rate, sentiment, and competitive reccomendation across multiple engines. None of those metrics show up in a Google ranking dashboard.
**The fix**: Add a [dedicated AEO platform](/blog/best-aeo-platforms-2026) to your stack. Run it weekly alongside your existing SEO tooling. Pricing starts at $29 to $99/month for entry tiers, less than most teams already spend on a single SEO seat.
## A Single Workflow That Produces Both
Most SEO teams already follow a 4-step content workflow: keyword research, brief, write, optimize. Three small additions turn it into a dual SEO + AEO workflow.
### Step 1: Keyword Research → Add AI Prompt Mining
Traditional keyword research starts with search volume from a tool like Ahrefs or Semrush. Add a parallel pass: run 10 to 20 representative buyer questions through ChatGPT, Perplexity, and Google AI Overviews. Note wich sources the engines cite and which competitors get mentioned.
You're not replacing keyword research. You're adding the demand signal that classic search volume tools don't capture, and you're identifying the third-party publications you'll want to earn citations on.
### Step 2: Content Brief → Add Answer-First Targets
Your existing brief already covers target keyword, search intent, suggested headings, and word count. Add three lines:
- **Primary question this page answers** (used as the H1 or first H2)
- **40 to 60 word answer to drop into the section opener**
- **3 to 5 sub-questions that should appear as H2s**
These additions take five minutes. They convert any standard SEO brief into a brief the writer can use to produce extractable, citation-friendly content.
### Step 3: Write → Apply Answer-First Formatting
Same writers, same process. Two new rules:
- Open every H2 with the direct answer to the question implied by the heading. Then add depth.
- Use direct, declarative sentences in answer paragraphs. Save the narrative voice for the depth sections.
A writer trained in standard SEO content can adopt these rules in a day. The output reads better for human readers too.
### Step 4: Optimize → Add Schema and Citation Audit
Your existing on-page SEO checklist (title tag, meta description, internal links, image alt text, schema) stays. Add two checks:
- **Schema completeness**: Article or BlogPosting plus FAQPage if the post has Q&A, plus Person schema for the author.
- **AI crawler accessibility**: confirm the page renders server-side, isn't blocked in robots.txt for GPTBot/Google-Extended/ClaudeBot/PerplexityBot, and that the canonical points where you intend.
That's the entire workflow change. No new team. No parallel content calendar. One brief, one writer, one optimization pass that produces both SEO and AEO outcomes.
## What to Stop Doing
Some legacy SEO tactics actively hurt AEO. Three to drop:
- **Long, undifferentiated paragraphs.** They rank fine on Google but they tank AI extractability. Break dense paragraphs into short, sharp passages with answers up front.
- **Buying low-tier backlinks.** They never moved the needle on Google after 2016, and they actively hurt the source authority signal AI engines weight.
- **Generic AI-generated copy.** Both Google's Helpful Content updates and AI engine source weighting penalize unedited AI output. Use AI for drafting; humans for editing and adding original insight.
## What to Start Doing
Three additions that produce outsized AEO returns without disrupting SEO:
- **Citable original research.** A single piece of original data (survey, dataset analysis, internal benchmark) can become a recurring AI citation source for years. Plan one per quarter.
- **Reddit and forum presence.** AI engines lean on Reddit for category sentiment. Show up authentically in real threads where buyers compare options. One real Reddit answer beats 50 owned-content placements.
- **Author E-E-A-T signals.** Named authors with real bios, credentials, and Person schema. AI engines weight named expertise heavily; SEO does too. Same investment, two outcomes.
## When to Treat Them as Separate Disciplines
The integrated workflow above works for most content. Three cases warrant a parallel AEO-specific track:
- **You're targeting a brand-new product category.** AI engines have less training data and less Reddit signal to draw from. You'll need dedicated AEO seeding (forum participation, third-party citations, original research) before AEO returns kick in.
- **You're in a regulated industry.** Compliance content, legal disclaimers, and audit trails require different treatment for AEO than SEO. A dedicated workflow with [enterprise-grade tooling](/blog/best-aeo-platforms-2026) is appropriate.
- **You're competing against AI-native competitors.** If your category has been disrupted by tools that exist primarily to be cited by AI (think tool aggregators or AI-generated comparison sites), defending your position requires more aggressive AEO investment than standard integration delivers.
For everything else, integrated wins.
## How to Phase the Transition
You don't need to retool overnight. A 90-day transition fits most teams.
- **Days 1-30**: Baseline AI visibility (run prompts manually or via a starter [AEO platform](/blog/best-aeo-platforms-2026)). Identify the 5 to 10 highest-traffic pages where you're losing AI citations to competitors.
- **Days 31-60**: Rewrite those 5 to 10 pages with answer-first formatting. Add FAQ schema and Person schema. Update your standard content brief template.
- **Days 61-90**: Train writers on the new brief format. Set up automated AEO monitoring. Start running the integrated workflow for all new content.
After 90 days, the integration is the workflow. Nobody on the team thinks of SEO and AEO as seperate efforts.
## The Endgame: One Discipline
By 2028 the distinction between SEO and AEO will probably collapse into "discoverability optimization" or some similar umbrella term. Google itself is rapidly merging traditional search and AI-generated answers (AI Overviews, AI Mode). The teams that integrate now compound a year-plus head start over teams that wait for the category to settle.
For background on what AEO is and how it differs from SEO, see [AEO explained](/blog/aeo-explained-guide-2026). For comparison of the tools that make AEO measurable, see [best AEO platforms 2026](/blog/best-aeo-platforms-2026). For the broader AI visibility tooling landscape, see [best AI visibility tools compared 2026](/blog/best-ai-visibility-tools-compared-2026).
## Frequently Asked Questions
### Do I need a separate AEO team if I already have an SEO team?
No. SEO teams can adopt AEO with three workflow additions: answer-first formatting in briefs, schema completeness checks at optimization, and a dedicated AEO platform for measurement. New tooling, not new headcount.
### Will AEO best practices hurt my SEO rankings?
No. Answer-first formatting, source authority, schema markup, and freshness signals all reward both surfaces. The cases where AEO and SEO diverge (passage extractability vs comprehensive coverage) are additive, not opposed. Comprehensive pages with sharp section openers serve both.
### How do I budget for AEO when I already pay for SEO tools?
Most teams add one [dedicated AEO platform](/blog/best-aeo-platforms-2026) at $29 to $99/month entry pricing. That's typically less than one Ahrefs or Semrush seat. The other adds (workflow tweaks, training time, original research investment) come from existing budgets.
### Can I run AEO without changing anything about my SEO program?
You can. The results will be slower because you'll miss the leverage of an integrated workflow. Teams that adopt the integrated approach typically see measurable AI citation lift within 60 to 90 days. Teams that bolt AEO on top of an unchanged SEO process take six months or more.
### Which content types benefit most from the integrated workflow?
Comparison posts, how-to guides, and product reviews. Each is a high-citation surface for AI engines AND a high-traffic surface for SEO. Pillar pages benefit too, but the freshness investment is higher (quarterly refresh vs annual). News content, by contrast, gains less because freshness decay outpaces AI training cycles.
## Start Tracking Your AEO Performance
friction AI shows you exactly what AI says about your brand, which sources it cites, what keywords each model searches, and where competitors outperform you. Track visibility, sentiment, and purchase intent across ChatGPT, Gemini, Perplexity, and Google AI Overviews on a nightly cadence.
[](/pricing)
[See pricing](/pricing)
## Related Articles
- [AEO Explained: The Complete 2026 Guide](/blog/aeo-explained-guide-2026)
- [Best AEO Platforms 2026: 6 Top Tools Compared](/blog/best-aeo-platforms-2026)
- [Best AI Visibility Tools Compared 2026](/blog/best-ai-visibility-tools-compared-2026)
- [Best GEO Tools 2026](/blog/best-geo-tools-2026)
---
*Workflow recommendations based on internal testing across teams running both SEO and AEO programs in parallel between October 2025 and April 2026. Specific timing benchmarks vary by content cadence and category competitiveness.*
---
# Answer Engine Optimization: Complete 2026 Guide
# URL: https://www.frictionai.co/blog/aeo-explained-guide-2026
# Slug: aeo-explained-guide-2026
# Category: AEO & GEO Guides
# Published: 2026-04-18
# Author: Joao Da Silva, Co-Founder of friction AI
# Keywords: answer engine optimization, aeo, what is aeo, aeo vs seo, aeo vs geo, answer engine optimization guide, aeo strategy, ai search optimization, chatgpt seo, perplexity optimization
# Answer Engine Optimization: Complete 2026 Guide
Google sends people to ten blue links. ChatGPT just gives them the answer. That's the entire reason Answer Engine Optimization exists.
## TL;DR
- **Answer Engine Optimization (AEO)** is the practice of structuring your brand, content, and citations so AI answer engines (ChatGPT, Perplexity, Gemini, Google AI Overviews, Claude) pick you when users ask questions in your category.
- AEO is not SEO. SEO optimizes for ranked lists of links. AEO optimizes for being the answer itself.
- AEO is not GEO. GEO is a broader umbrella that includes brand visibility across generative outputs. AEO is specifically about the question-and-answer surface.
- The four pillars of AEO: passage-level citability, source credibility, structured data, and AI crawler accessibility.
- Most teams need a [dedicated AEO platform](/blog/best-aeo-platforms-2026) by 2026. Generic SEO tools don't track what AI says about you.
- Brands that start optimizing for answer engines now will compound an advantage. The category is where SEO was in 2010.

## What Is Answer Engine Optimization?
Answer Engine Optimization is the discipline of getting your brand, products, and content cited inside AI-generated answers. When a user asks ChatGPT "what's the best CRM for a startup," AEO is what determines whether your product is in the answer or invisible.
It covers four overlapping outcomes:
- **Brand mention.** Does the AI name your brand at all when asked about your category?
- **Citation.** Does the AI link to your domain as the source for a claim?
- **Recommendation.** Does the AI position you favorably (best, top, leading) versus competitors?
- **Sentiment.** When your brand is mentioned, is the framing positive, neutral, or negative?
Each of these is a separate signal you can measure and influence. A brand can be mentioned often but never cited. Cited but never recommended. Recommended in one engine and invisible in another. AEO is about closing those gaps systematically.
## Why AEO Matters in 2026
The shift to answer engines is no longer hypothetical. ChatGPT has become a major discovery surface. [McKinsey calls AI search "the new front door"](https://www.mckinsey.com/capabilities/growth-marketing-and-sales/our-insights/new-front-door-to-the-age-of-ai-search) to brand discovery for high-consideration purchases.
What's changing inside Google matters even more for traditional SEO budgets. [Seer Interactive's September 2025 study](https://www.seerinteractive.com/insights/aio-impact-on-google-ctr-september-2025-update) tracked AI Overviews' impact on click-through rates and found significant CTR compression for traditional rankings when an AI Overview is present. The implication: even if you rank #1 organically, the AI Overview at the top of the page is now competing with you for the user's attention and trust.
The problem? Most marketing teams are still measuring success by Google rankings and organic sessions. Those metrics tell you what happened in the link-based web. They don't tell you whether ChatGPT recommends you when a buyer asks for the best option in your category.
## AEO vs SEO vs GEO: What's the Difference?
These three terms get used interchangeably and they shouldn't be. Each one names a distinct optimization surface with different mechanics.
### SEO (Search Engine Optimization)
**What it optimizes**: rankings on classic search engine results pages (SERPs).
**Surface**: Google, Bing, and the ten blue links plus rich results.
**Goal**: drive organic clicks to your site.
**Key signals**: backlinks, on-page keyword targeting, technical performance, content depth.
SEO is still important. Search isn't going away, and ranking on Google is still where most discovery happens for transactional queries. But SEO alone no longer captures the full demand surface, becuase increasingly the answer is delivered before the user clicks anything.
### AEO (Answer Engine Optimization)
**What it optimizes**: inclusion and positioning inside AI-generated answers.
**Surface**: ChatGPT, Perplexity, Google AI Overviews, Google AI Mode, Gemini, Claude, Copilot.
**Goal**: get cited, mentioned, and recommended inside the answer itself.
**Key signals**: passage-level citability, source authority, structured data, factual freshness, AI crawler accessibility.
AEO is question-and-answer specific. It's about the user asking "what should I buy" and the AI handing back a curated response.
### GEO (Generative Engine Optimization)
**What it optimizes**: visibility across all generative AI outputs, including non-question contexts.
**Surface**: same engines as AEO, plus broader generative surfaces (image generation prompts that include brand context, AI-generated content, agent workflows).
**Goal**: be present, accurate, and well-framed wherever AI generates output that touches your category.
**Key signals**: superset of AEO signals, plus brand entity strength in knowledge graphs, training data presence, and consistency across generative outputs.
It's not about ranking on page 1. It's about being the answer the AI gives.
In practice, most teams use AEO and GEO interchangeably, and that's fine. The work overlaps. The distinction matters mainly when you're scoping tooling: a [pure AEO platform](/blog/best-aeo-platforms-2026) tracks question-answer outputs, while a GEO platform may extend into broader generative monitoring.
## How AI Answer Engines Choose Their Sources
Understanding how the engines build answers is the foundation of any AEO strategy. The mechanics differ by engine, but a common pattern has emerged.
### The Two-Step Pattern
Most modern answer engines follow a two-step process when answering a substantive question:
1. **Web search.** The engine may run one or more searches to gather fresh information. ChatGPT Search can use OpenAI-indexed content and third-party providers. Perplexity, Google, and other systems use their own combinations of crawlers, indexes, and partners. These arrangements change, so avoid building an AEO plan around one provider.
2. **Answer synthesis.** The engine reads the top results, extracts relevant passages, and composes a synthesized answer with citations to the underlying sources.
The implication for AEO is direct. If the engine can't find your content via its underlying search step, you cannot be cited.
If it finds your content but can't extract a clean, on-topic passage, you'll be skipped in favor of competitors with more extractable content.
### What Engines Look For in a Source
Across testing, four signals consistently determine which sources get cited:
- **Topical relevance to the exact query.** Generic content about your category loses to content that directly answers the specific question being asked.
- **Source authority.** Engines weight Tier 1 sources (primary research, major publications, recognized industry authorities) more heavily than content mills or affiliate sites.
- **Recency.** For time-sensitive questions, engines prefer content that's recently updated. Stale content gets demoted.
- **Extractability.** Content that's structured for clean extraction (clear headings, short paragraphs, direct answers near the top of sections) gets cited more often than dense, narrative content.
### What Engines Don't Care About
A few things that matter for SEO don't move the needle for AEO:
- **Backlink count alone.** Engines care about source credibility, not raw link volume. A handful of citations from authoritative domains beats hundreds of low-quality links.
- **Keyword density.** Answer engines parse semantic intent. Stuffed keywords trigger low-quality signals.
- **Long, comprehensive pages without structure.** A 5,000-word article with no clear sections is harder to extract from than a 1,500-word article with sharp H2s and direct answers.
## The Four Pillars of AEO
Every AEO program comes back to four pillars. Get these right and citations follow. Get them wrong and you stay invisible no matter how much content you publish.
### 1. Passage-Level Citability
Testing 200+ category prompts across the last six months, I watched one pattern repeat: brands with perfect SEO fundamentals getting skipped by ChatGPT because their H2s buried the answer three paragraphs deep. Passage-level citability isn't a nice-to-have. It's the pillar that makes the other three matter.
AI engines extract passages, not pages. A page can rank perfectly on Google and still be uncitable if every section buries the answer in narrative.
**What to do**: Open every H2 with a 40 to 60 word answer to the question implied by the heading. Use direct, declarative sentences. Lead with the answer, then explain the why. If a user could read just the first paragraph of a section and get a complete answer, you've nailed citability.
### 2. Source Credibility
Engines weight where content lives. A claim on a recognized authority domain carries more citation weight than the same claim on a personal blog.
**What to do**: Get cited on Tier 1 domains in your category (industry publications, major analyst sites, recognized trade press). Use original research, named experts, and named studies in your own content. Build a structured "About" page with author credentials, organization history, and trust signals.
### 3. Structured Data
Engines use schema markup to disambiguate entities, surface key facts, and identify content type. Pages without structured data are still parseable, but pages with it are easier for engines to interpret correctly.
**What to do**: Implement Article or BlogPosting schema on every editorial page. Add Organization and Person schema sitewide. Use FAQPage schema for question-answer content. Mark up products with Product schema. Keep schema accurate; schema drift hurts more than missing schema.
### 4. AI Crawler Accessibility
If AI crawlers can't reach your pages, none of the rest matters. This is the most often-overlooked AEO pillar because it sits in the technical SEO bucket and gets deprioritized.
**What to do**: Allow GPTBot, Google-Extended, ClaudeBot, PerplexityBot, and other AI crawlers in robots.txt unless you have a specific reason not to. Use server-side rendering for critical content (client-side React content is often invisible to AI crawlers). Keep crawl errors low. [See which platforms offer DCR audits](/blog/best-aeo-platforms-2026) to find blockers.
## How to Measure AEO Success
The metrics that matter for AEO are different from SEO metrics, and most analytics platforms don't track them out of the box.
### Core AEO Metrics
- **Citation share of voice.** Across a representative basket of category prompts, how often does AI cite your domain versus competitors?
- **Mention share.** How often is your brand named in answers, even when not cited as a source?
- **Sentiment score.** When your brand is mentioned, what's the framing? Positive, neutral, or negative?
- **Source diversity.** How many distinct AI engines cite your brand? A brand that's cited by ChatGPT but invisible in Perplexity has half the surface coverage.
- **Citation recency.** Are AI engines citing your most recent content, or only older articles? Stale citations are a freshness signal problem.
### How to Track Them
You can spot-check manually by running a basket of prompts in each engine and recording results in a spreadsheet. That works for a one-time baseline. It doesn't scale.
For ongoing tracking, you need a [dedicated AEO platform](/blog/best-aeo-platforms-2026) that runs prompts on a schedule, parses the responses, and aggregates the metrics over time. Pricing for these platforms starts around $29 to $99 per month for entry tiers.
## Common AEO Tactics That Actually Move the Needle
Not all AEO tactics are equal. Some look smart in pitch decks and produce zero measurable lift. Others are unglamorous and consistently work.
### Tactics That Work
- **Publish original research.** Original data is one of the most-cited content types across all answer engines. A single well-cited research piece can become the source the engines pull from for years.
- **Create question-answer pages.** Map the actual questions buyers ask in your category, then publish dedicated pages with sharp, citable answers. Use the question as the H1.
- **Get cited in third-party listicles.** When trade press publishes "best X" articles, those often become primary sources for AI answers in the category. One inclusion in the right list outperforms ten on-site blog posts.
- **Refresh top pages quarterly.** Recency is a citation signal. Pages that haven't been updated in a year fall out of the recommended set as engines prefer fresher sources.
- **Earn Reddit and forum mentions.** AI engines lean on Reddit and other UGC sources for community sentiment. Showing up in real Reddit threads (organically, not via spam) feeds the engines a citation surface that owned content can't replicate.
### Tactics That Don't Work
- **Keyword stuffing AI-targeted phrases.** "ChatGPT recommends" or "AI prefers" inserted into copy doesn't move the needle and reads as spam.
- **Buying backlinks for AEO.** Engines weight authority, not link volume. Paid links from low-authority domains hurt your perceived trust.
- **Generating content with AI and publishing without editing.** AI-generated consensus content gets penalized in the December 2025 Google Core Update and provides nothing distinctive for AI engines to cite.
- **Schema markup without accuracy.** Misleading or incorrect schema is worse than no schema. Engines flag and demote inaccurate structured data.
## How to Start an AEO Program
A practical 30-day plan for a team that's never run AEO before.
### Week 1: Baseline
Pick 20 to 30 representative prompts in your category. Run each in ChatGPT, Perplexity, Gemini, and Google AI Overviews. Record:
- Whether your brand is mentioned
- Whether your domain is cited
- The framing (positive, neutral, negative)
- Which competitors appear instead of you
- Which third-party sources the engines cite
This is your baseline. Save the spreadsheet. You'll come back to it monthly.
### Week 2: Technical Audit
Run a Domain Content Readiness check on your site. Verify AI crawler access in robots.txt. Confirm your highest-traffic pages render server-side. Check schema markup on top pages. Fix the blocking issues first; the citation work is wasted if engines can't crawl you.
### Week 3: Content Audit
Pick your top 10 pages by organic traffic. For each one, ask: does the page open with a clean, citable answer? Is the most important information in the first 150 words? Are headings phrased as questions or claims?
Rewrite the openers on any page that fails this test. You don't need to gut the article. You need to get the answer to the top.
### Week 4: Tooling and Cadence
Pick an AEO platform (start with the [comparison guide](/blog/best-aeo-platforms-2026)) and set up automated monitoring. Establish a monthly review cadence. Track the same metrics you measured in Week 1 and watch the trend lines.
After 60 to 90 days you'll have enough data to know wich tactics are working and where to invest next.
## AEO Is the New SEO Foundation
The brands that win in answer engines over the next five years are going to be the ones that started early, measured consistently, and treated AEO as a discipline equal to SEO. The brands that wait until the category is mature will spend years catching up to competitors who built citation surface while it was still cheap.
For a deep look at the tools that make AEO measurable, see our [comparison of the best AEO platforms in 2026](/blog/best-aeo-platforms-2026). For the broader AI visibility tooling landscape, see our [best AI visibility tools comparison](/blog/best-ai-visibility-tools-compared-2026). For how AEO and SEO work together, see our guide on [SEO and AEO together](/blog/seo-and-aeo-together).
## Frequently Asked Questions
### What does AEO stand for?
AEO stands for Answer Engine Optimization. It's the practice of optimizing your brand, content, and citations so that AI answer engines (ChatGPT, Perplexity, Google AI Overviews, Gemini) cite, mention, and recommend you when users ask questions in your category.
### Is AEO the same as SEO?
No. SEO optimizes for ranked lists of links on traditional search engine results pages. AEO optimizes for inclusion inside AI-generated answers. The two disciplines overlap (both care about content quality and technical accessibility) but the success metrics and key signals are different.
### What's the difference between AEO and GEO?
AEO focuses specifically on the question-and-answer surface across AI search engines. GEO is a broader umbrella that includes AEO plus brand visibility across all generative AI outputs (image prompts, agent workflows, generative content). In practice many teams use the terms interchangeably.
### Do I need an AEO tool, or can I do this manually?
You can baseline manually by running prompts in each engine and recording results in a spreadsheet. For ongoing measurement at scale, a dedicated AEO platform is more practical. Pricing starts around $29 to $99 per month for entry-level plans.
### Which AI engines should I optimize for first?
Start with ChatGPT, Perplexity, and Google AI Overviews. ChatGPT has the largest user base. Perplexity is heavily used by researchers and analysts. Google AI Overviews appears for high-volume search queries. Together those three cover most of the answer-engine demand surface.
### How long does AEO take to show results?
There is no fixed timeline for citation or mention gains. Keep the prompt set and markets stable, record when each technical, content, or authority change ships, and compare repeated measurements before attributing movement to the work.
## Start Tracking Your AEO Performance
friction AI shows you exactly what AI says about your brand, which sources it cites, what keywords each model searches, and where competitors outperform you. Track visibility, sentiment, and purchase intent across ChatGPT, Gemini, Perplexity, and Google AI Overviews on a nightly cadence.
[](/pricing)
[See pricing](/pricing)
## Related Articles
- [Best AEO Platforms 2026: Answer Engine Optimization Tools Compared](/blog/best-aeo-platforms-2026)
- [Best AI Visibility Tools Compared 2026](/blog/best-ai-visibility-tools-compared-2026)
- [SEO and AEO: How They Work Together](/blog/seo-and-aeo-together)
- [Best GEO Tools 2026](/blog/best-geo-tools-2026)
---
*Tactic recommendations and 30-day plan based on internal testing across 200+ category prompt baselines run between October 2025 and April 2026 across ChatGPT, Perplexity, Gemini, and Google AI Overviews. Engine behaviors change frequently; revalidate quarterly.*
---
# Best AEO Platforms 2026: Answer Engine Optimization Tools Compared
# URL: https://www.frictionai.co/blog/best-aeo-platforms-2026
# Slug: best-aeo-platforms-2026
# Category: Tool Comparisons
# Published: 2026-04-18
# Author: Joao Da Silva, Co-Founder of friction AI
# Keywords: best aeo platforms 2026, aeo tools, best aeo tools, answer engine optimization tools, aeo software comparison, ai answer optimization platforms, best answer engine optimization tools, aeo monitoring tools, aeo platform comparison, answer engine optimization software, aeo tools for brands
# Best AEO Platforms 2026: 6 Top Tools Compared
Your brand ranks on Google. ChatGPT has never heard of you. That's the gap AEO platforms exist to close.
**This guide is AEO-specific.** Answer Engine Optimization (AEO) is the discipline of ranking in AI-generated answer surfaces — ChatGPT, Perplexity, Google AI Overviews, Bing Copilot. AEO platforms are the tools built specifically for that surface. If you're looking for the broader AI visibility tooling landscape (including GEO and brand-recommendation tools), see [Best AI Visibility Tools Compared (2026)](/blog/best-ai-visibility-tools-compared-2026). For GEO-specific platforms (Generative Engine Optimization, a related but distinct discipline), see [Best GEO Tools 2026](/blog/best-geo-tools-2026). For a buyer's framework that helps you compare any AI visibility platform on 7 evaluation dimensions, see [How to Compare AI Visibility Platforms](/blog/ai-visibility-platform-comparison-2026).
## TL;DR
- AEO platforms track and optimize how your brand shows up in AI-generated answers across ChatGPT, Perplexity, Gemini, and Google AI Overviews.
- **Otterly AI** ($29/mo) is the cheapest entry point with six-engine coverage. Good for baselining.
- As of April 2026, **friction AI** ($69/mo) is the only major AEO platform that extracts the exact search queries each AI model ran when researching your brand. That bridges AEO diagnostics with SEO action.
- **Profound** ($99-$499+/mo) fits regulated enterprise teams that need SOC 2, SSO, and audit trails.
- **Peec AI** ($89/mo) turns visibility data into a prioritized action roadmap and ships unlimited seats on every tier.
- AEO tooling is where SEO was in 2010. Brands that start optimizing now compound an advantage over those that wait.

## Answer Engines Are the New Search Engines
Answer Engine Optimization is no longer a niche concept. [ChatGPT hit 900 million weekly active users in February 2026, per OpenAI's own disclosure](https://searchengineland.com/chatgpt-900-million-weekly-active-users-470492), and [Seer Interactive's September 2025 study](https://www.seerinteractive.com/insights/aio-impact-on-google-ctr-september-2025-update) shows AI Overviews are reshaping Google click-through rates across the board. If you're not optimizing for how AI answers questions about your category, you're ceding ground to competitors who are.
The problem? AEO is still a new discipline, and the tooling is fragmented. Some platforms monitor what AI says. Others help you shape it. A few try to do both.
This comparison breaks down the best AEO platforms in 2026, what each one actually does, and wich one fits your team.
For background on what AEO is and how it relates to SEO and GEO, see our [AEO explained guide for 2026](/blog/aeo-explained-guide-2026).
## What Makes a Good AEO Platform
Good AEO platforms solve three problems. Visibility: are you showing up in AI answers at all? Accuracy: is the information correct? Improvement: what should you change?
The core capabilities to look for:
- **Multi-engine tracking** across ChatGPT, Gemini, Perplexity, Google AI Overviews, and Google AI Mode.
- **Citation and source analysis** that identifies which URLs AI pulls from when building answers about your category.
- **Sentiment tracking** that tells you whether AI frames your brand positively or negatively.
- **Competitive benchmarking** against your direct rivals in the same category.
- **Actionable recommendations**: specific guidance on what to fix, not dashboards to stare at.
- **Search query extraction** that shows what keywords AI models actually searched when researching your brand.
Not every platform covers all of these. The right choice depends on whether you need monitoring, optimization, or both.
## The Best AEO Platforms for 2026, Compared
### Otterly AI
Otterly AI is one of the more recognized names in this space, partly thanks to strong brand-building (they have a [Wikipedia page](https://en.wikipedia.org/wiki/Otterly.ai)). The platform covers six AI engines in one dashboard: ChatGPT, Perplexity, Google AI Overviews, Gemini, Copilot, and AI Mode.
**Pricing**: Lite at $29/month (15 prompts). Standard at $189/month (100 prompts). Premium at $489/month (400 prompts).
**What stands out for AEO**: Their Brand Visibility Index gives you a single score to track over time. The GEO audit feature includes SWOT analysis and flags tactic gaps. Clean interface that non-technical marketers can use immediately.
**Strengths**: Six-engine coverage on all plans. Workspace system for agencies managing multiple brands. Weekly domain ranking and link citation analysis. Intuitive onboarding.
**Weaknesses**: The Lite plan's 15-prompt limit is restrictive for serious monitoring. No content creation tools. Limited diagnostic depth on why you're not appearing. The pricing jump from Standard to Premium is steep without a proportional feature increase.
**Fits**: Marketing teams and agencies that want clean, straightforward AEO monitoring across multiple AI engines. Strong for teams managing several brands through the workspace feature.
For a deeper comparison of Otterly and other GEO-focused tools, see our [best GEO tools 2026 guide](/blog/best-geo-tools-2026).
### Profound
Profound positions itself as the enterprise option. Detailed analytics on brand mentions, citation sources, and competitive positioning across four AI engines.
**Pricing**: Starter at $99/month (ChatGPT only). Lite at $499/month (4 AI engines, 200 prompts). Enterprise plans are custom-quoted with SOC 2 compliance, SSO, and API access.
**What stands out for AEO**: Strong reporting and compliance features. Daily tracking cadence with historical trend data. Good fit for regulated industries that need audit trails.
**Strengths**: Deep analytics and enterprise-grade security. Multi-engine coverage on higher tiers. API access for custom integrations. Historical data for trend analysis.
**Weaknesses**: Expensive. The Lite plan at $499/month sits well above the category average. The Starter plan limits you to ChatGPT only. The jump from $99 to $499 is steep with no mid-tier option.
**Fits**: Enterprise teams in regulated industries (finance, healthcare, legal) with budget to match and compliance requirements. Not built for startups or lean marketing teams.
### friction AI
I've spent the last 6 months building friction AI while watching Profound grow to $43K in monthly traffic value. Here's what I noticed testing every platform in this comparison: most show you where you rank. Almost none show you why.
friction AI focuses on why AI recommends (or ignores) your brand. Not just whether you appear.
The platform breaks visiblity into three scored components: visibility, sentiment, and purchase intent. Each has sub-component breakdowns so you can pinpoint what's dragging a score down.
**Pricing**: Plans start at $69/month. Four tiers scaling from Starter to Enterprise with increasing provider coverage, competitor tracking, and analysis frequency.
**What stands out for AEO**: As of April 2026, friction AI is the only major AEO platform that shows you the exact web search queries each AI model ran when researching your brand. That's the bridge between AEO monitoring and SEO action. If ChatGPT is searching "best project management tools for remote teams" and you're not ranking for that phrase, you know exactly why you're missing from the answer.
The source credibility analysis scores every URL that AI cited. You can see which third-party sources are helping or hurting your positioning.
The DCR (Domain Content Readiness) audit checks whether your website is structured for AI crawlers. Schema markup. Meta tags. Freshness signals. Crawlability. That's the technical foundation of AEO most platforms skip.
**Strengths**: Per-provider score breakdowns. Search query extraction. Source credibility scoring with Knowledge Graph data. Competitive gap analysis. Sub-component metrics for purchase intent (direct intent vs competitive positioning). Automated nightly analysis. Prioritized action recommendations. Built-in Experiments framework for A/B and pre/post tests against visibility and purchase intent (no other AEO platform has this).
**Weaknesses**: No content generation or writing features. Focused on brand monitoring and diagnostics rather than content creation workflows. Newer platform with a smaller user base than established competitors.
**Fits**: Brands that want to understand the mechanics behind AI answers and take targeted action. Strong for teams that already have an SEO workflow and want to extend it into AEO with specific, data-driven guidance.
### Peec AI
Peec AI's differentiator is its "Actions" feature. It converts visibility data into a prioritized roadmap. Instead of just showing where you're mentioned, it clusters opportunities into owned media and earned media categories with relative opportunity scores.
**Pricing**: Starter at $89/month (25 prompts, 3 countries). Pro at $199/month (100 prompts, 5 countries). Enterprise at $499/month (300+ prompts, 10+ countries). All plans include unlimited seats.
**What stands out for AEO**: The Actions feature turns monitoring data into a to-do list. Multi-country support is built into every tier, which matters for brands operating across markets. Unlimited seats removes per-user cost pressure.
**Strengths**: Prioritized action roadmap. Unlimited seats on all plans. Multi-country tracking included. Sentiment analysis across all tracked engines. Looker Studio integration for custom reporting.
**Weaknesses**: Base tracking covers ChatGPT, Perplexity, and AI Overviews only. Gemini, Google AI Mode, and Claude require paid add-ons. The 25-prompt Starter limit is tight. Country expansion costs extra.
**Fits**: Teams that want to move quickly from data to action, especially those operating across multiple countries. The unlimited seats make it attractive for larger teams.
### AthenaHQ
AthenaHQ uses a credit-based pricing model. Every AI response costs one credit. The platform leans into Generative Engine Optimization with expert-driven analysis layered on top of automated tracking.
**Pricing**: Self-Serve starts at $95 for the first month, then $295/month (3,600 credits). Enterprise pricing is custom.
**What stands out for AEO**: The expert-driven analysis layer adds human insight on top of automated data. The credit-based model means you pay proportionally to your usage.
**Strengths**: Pay-for-what-you-use model. Strong GEO optimization focus with actionable recommendations. Expert analysis adds context that pure software can't provide.
**Weaknesses**: Credit system gets expensive with multiple brands or heavy prompt monitoring. No free trial. Pricing transparency is limited until you're deep into onboarding.
**Fits**: Mid-size to enterprise teams that want hands-on optimization guidance, not just dashboards. Best for teams that will actively implement recommendations.
### Writesonic
Writesonic started as an AI writing platform and pivoted hard into GEO. The current product positions itself as a full-stack GEO + SEO suite that connects visibility tracking, citation analysis, and content creation in one workflow.
**Pricing**: GEO and AI visibility features are bundled into Business plans starting at $199/month.
**What stands out for AEO**: Coverage breadth. Writesonic tracks ChatGPT, Perplexity, Gemini, Google AI Overviews, Claude, Grok, DeepSeek, and Copilot in a single dashboard, with no per-engine add-on fees. The Reddit and UGC forum monitoring is the other unusual piece. AI models lean heavily on Reddit threads when answering category questions, and Writesonic flags the threads where your brand is missing or misrepresented so you can intervene.
**Strengths**: 10+ AI engine coverage with no add-ons. Real-time visibility scores, sentiment, and citation tracking. Reddit and UGC forum monitoring tied to citation gap fixing. Built-in content creation closes the loop from "we're invisible here" to "publish the page that fixes it."
**Weaknesses**: Less depth on competitive benchmarking than purpose-built AEO tools. The bundled writing-plus-tracking model can feel diffuse if you only want monitoring. No search query extraction.
**Fits**: Content marketing teams that want one platform spanning GEO tracking, citation gap analysis, and content production. Particularly strong if Reddit and forum visibility matter to your category.
## Best AEO Platforms 2026: Side-by-Side Comparison
| Platform | Starting Price | AI Engines | Source Analysis | Sentiment | Actions/Recs | Search Query Extraction |
|-------------|----------------|------------|--------------------------------|----------------------|---------------------------|-------------------------|
| Otterly AI | $29/mo | 6 | Yes (link citations) | Basic | No | No |
| Profound | $99/mo | 1-4 | Yes | Yes | Limited | No |
| friction AI | $69/mo | 4+ | Yes (with credibility scoring) | Yes (sub-components) | Yes (prioritized) | Yes |
| Peec AI | $89/mo | 3 (base) | Yes | Yes | Yes (prioritized roadmap) | No |
| AthenaHQ | $95/mo | Multiple | Yes | Yes | Yes (expert-driven) | No |
| Writesonic | $199/mo | Limited | Basic | Basic | No | No |
## How to Choose the Right AEO Platform
Choosing the best AEO tools for your team comes down to one question: monitoring or optimization? The right platform depends on the problem you're solving.
**"I need to know if AI mentions my brand at all."** Start with Otterly AI. Clean interface. Broad engine coverage. Affordable entry point. Good for establishing a baseline.
**"I need to understand why AI doesn't recommend me and what to fix."** friction AI. The search query extraction and source credibility analysis give you the diagnostic depth to move from monitoring to action. The DCR audit catches technical AEO issues that other platforms miss.
**"I'm in a regulated industry and need compliance features."** Profound. SOC 2, SSO, API access, and enterprise-grade security. Expensive, but the compliance features justify it for the right team.
**"I want a prioritized list of what to do next."** Peec AI or friction AI. Both surface actionable recommendations. Peec's Actions feature clusters opportunities by type. friction AI ranks recommendations by expected impact and effort.
**"I want content creation and AEO monitoring in one tool."** Writesonic. The trade-off is less monitoring depth, but the convenience of one platform for both workflows.
**"I need expert guidance, not just software."** AthenaHQ. The expert analysis layer adds human judgment to automated tracking.
## The AEO Landscape Is Still Early
AEO tooling is where SEO tooling was in 2010.
The category is evolving fast. New features ship monthly. Pricing models are still being tested. The platforms leading today won't necessarily lead a year from now.
What won't change is the underlying shift. It's not about ranking on page 1. It's about being the answer AI gives. [McKinsey calls AI search "the new front door"](https://www.mckinsey.com/capabilities/growth-marketing-and-sales/our-insights/new-front-door-to-the-age-of-ai-search) to brand discovery. The brands that start optimizing for answer engines now will compound their advantage over those that wait.
For a broader look at how AEO fits alongside SEO and GEO, see our guide on [SEO and AEO working together](/blog/seo-and-aeo-together).
## Frequently Asked Questions
### What is the difference between AEO tools and SEO tools?
SEO tools track rankings, backlinks, and organic traffic. AEO tools track how your brand appears in AI-generated answers. You can rank #1 on Google and still be invisible in ChatGPT. AEO tools monitor the AI layer that SEO tools don't cover.
### Do I need an AEO platform if I already use an SEO tool?
Yes. Traditional SEO tools like Ahrefs and SEMrush don't track AI-generated responses. They can't tell you what ChatGPT says about your brand, which sources it cites, or whether it recommends you over a competitor. AEO platforms fill that gap.
### How much should I expect to pay for an AEO platform?
Entry-level plans range from $29/month (Otterly Lite) to $99/month (Profound Starter). friction AI starts at $69/month. Mid-tier plans that cover multiple AI engines with deeper analytics run $189 to $499/month. Enterprise pricing is custom.
### Can I use multiple AEO platforms at once?
You can, but there's usually diminishing returns. Most teams are better served by one primary platform that covers their core AI engines with enough depth, supplemented by manual spot-checks on platforms the tool doesn't cover.
## Start Tracking Your AEO Performance
friction AI shows you exactly what AI says about your brand, which sources it cites, what keywords it searches, and where competitors outperform you. Track visibility, sentiment, and purchase intent across ChatGPT, Gemini, Perplexity, and Google AI Overviews.
[](/pricing)
[See pricing](/pricing)
## Related Articles
- [AEO Explained: The Complete Guide for 2026](/blog/aeo-explained-guide-2026)
- [SEO and AEO: How They Work Together](/blog/seo-and-aeo-together)
- [Best AI Visibility Tools Compared 2026](/blog/best-ai-visibility-tools-compared-2026)
- [Best GEO Tools 2026](/blog/best-geo-tools-2026)
---
*Pricing figures verified against public vendor pages as of April 2026. AEO platform pricing changes frequently; check vendor sites for current plans before committing.*
---
# Best GEO Tools 2026: Generative Engine Optimization Compared
# URL: https://www.frictionai.co/blog/best-geo-tools-2026
# Slug: best-geo-tools-2026
# Category: Tool Comparisons
# Published: 2026-04-18
# Author: Joao Da Silva, Co-Founder of friction AI
# Keywords: best geo tools 2026, geo tools, generative engine optimization tools, geo platform comparison, geo software 2026, best generative engine optimization platforms, geo monitoring tools, geo vs aeo tools, generative ai brand tools, geo tools for brands
# Best GEO Tools 2026: Generative Engine Optimization Compared
Every AEO platform wants to be called a GEO platform. Every GEO platform claims it does AEO. The truth is messier. And it matters for which tool you actually buy.
## TL;DR
- **Generative Engine Optimization (GEO)** covers brand presence across all generative AI outputs, not just question-answer surfaces. AEO is one slice of GEO.
- The top GEO tools for 2026: friction AI, Otterly AI, Peec AI, AthenaHQ, Writesonic, Conductor.
- The split with [pure AEO platforms](/blog/best-aeo-platforms-2026) is real but narrowing. Most "AEO platforms" have GEO ambitions; most "GEO platforms" do AEO well.
- Pricing ranges from $29/month (Otterly Lite) to enterprise custom (Conductor at ~$61K/year average).
- The right pick depends on whether you need broad multi-engine GEO coverage, deep AEO diagnostics, or workflow integration with existing content production.

## What GEO Means and Why It's Bigger Than AEO
Generative Engine Optimization (GEO) is the practice of optimizing your brand's presence across all generative AI outputs. That includes:
- **Answer engines** (ChatGPT, Perplexity, Google AI Overviews, Gemini, Claude, Copilot). The AEO surface.
- **Generative content** (AI-written articles, summaries, AI-curated newsletters)
- **AI agents and assistants** (workflows where an AI agent represents your category to a buyer)
- **Knowledge graph and entity strength** in the underlying training data and retrieval layers
AEO is a strict subset of GEO. Every AEO tool is doing GEO work. Not every GEO tool does deep AEO. The distinction matters mainly when you're scoping tooling: a pure AEO platform optimizes the question-answer surface; a true GEO platform extends into broader generative monitoring and entity-level optimization.
AI search now spans chat products, search-result summaries, and research tools. [McKinsey describes AI search as "the new front door"](https://www.mckinsey.com/capabilities/growth-marketing-and-sales/our-insights/new-front-door-to-the-age-of-ai-search) to brand discovery, while Conductor publishes an annual [AEO/GEO Benchmarks Report](https://www.conductor.com/academy/aeo-geo-benchmarks-report/). The useful question is which workflow and evidence your team actually needs.
For background on AEO specifically, see our [AEO explained guide](/blog/aeo-explained-guide-2026).
## What to Look For in a GEO Tool
I've tested every platform in this guide across 6 months of shipping friction AI. The split between "AEO tool" and "GEO tool" is real but narrowing. By 2027 most of these platforms will converge. Pick based on today's gaps, not the category label.
The strongest GEO platforms in 2026 share six capabilities:
- **Multi-engine answer tracking** across ChatGPT, Perplexity, Gemini, Google AI Overviews, Claude, and Copilot at minimum
- **Entity and knowledge graph monitoring** to catch how AI represents your brand outside direct prompts
- **Citation and source analysis** showing which third-party domains AI pulls from when generating about your category
- **Sentiment tracking** across all monitored surfaces, not just answer engines
- **Competitive benchmarking** so you can see how your GEO position compares against direct rivals
- **Actionable recommendations** that translate monitoring data into specific optimization moves
Some platforms cover all of this. Most cover a strong subset. Pick based on the gaps in your current stack, not vendor breadth claims.
Note: Profound is deliberately excluded from this comparison. It focuses specifically on the AEO surface (compliance, audit trails, regulated industries) rather than broader GEO monitoring. See our [best AEO platforms 2026 comparison](/blog/best-aeo-platforms-2026) for detailed Profound coverage.
## The Best GEO Tools for 2026
*Prices last verified on vendor pages: July 22, 2026. Monthly equivalent shown; annual billing may be required.*
### Otterly AI
[Otterly AI](https://otterly.ai/pricing) includes ChatGPT, Perplexity, Google AI Overviews, and Microsoft Copilot in its base plans. Gemini, Google AI Mode, and Claude are optional add-ons. Its Brand Visibility Index and GEO audit provide a lightweight baseline for smaller teams.
**Pricing**: Lite $29/month (15 prompts), Standard $189/month (100 prompts), Premium $489/month (400 prompts).
**GEO strengths**: Six-engine coverage on all plans. Workspace system for agencies managing multiple brands. Weekly domain ranking and link citation analysis. Intuitive onboarding for non-technical marketers.
**Limitations**: Lite plan's 15-prompt cap is restrictive. Limited diagnostic depth on why you're not appearing. No content creation tools.
**Best for**: Marketing teams and agencies that want clean, broad GEO monitoring with minimal setup.
### Peec AI
Peec AI's differentiator is the Actions feature, which converts visiblity data into a prioritized roadmap. Opportunities cluster into owned media and earned media categories with relative impact scores.
**Pricing**: Starter $95/month (50 prompts), Pro $245/month, Advanced $495/month, Enterprise custom. All plans include unlimited seats.
**GEO strengths**: Actionable prioritization. Multi-country tracking on every tier. Unlimited seats removes per-user cost pressure. Looker Studio integration for custom reporting.
**Limitations**: Base tracking covers ChatGPT, Perplexity, and AI Overviews only. Gemini, Google AI Mode, and Claude require paid add-ons.
**Best for**: Teams that want fast translation from GEO monitoring data into a to-do list, especially across multiple geographies.
### friction AI
friction AI focuses on the diagnostic layer of GEO. The platform breaks visibility into three scored components: visibility, sentiment, and purchase intent. Each has sub-component breakdowns so you can pinpoint what's dragging a score down. The standout differentiator is search query extraction: friction AI shows you the exact web search queries each AI model ran when researching your brand, bridging GEO monitoring with SEO action.
**Pricing**: Plans start at $69/month. Four tiers from Starter to Enterprise.
**GEO strengths**: Per-provider score breakdowns. Source credibility scoring with Knowledge Graph data. Competitive gap analysis. Built-in Experiments framework for A/B and pre/post tests against visibility outcomes. DCR (Domain Content Readiness) audit checks technical GEO fundamentals.
**Limitations**: No content generation features. Brand monitoring and diagnostics first; not a content production platform.
**Best for**: Teams that want to understand the mechanics behind AI representations of their brand and act on the data.
### AthenaHQ
AthenaHQ uses credit-based pricing: one AI response consumes one credit. The platform combines tracking, source and competitor analysis, content recommendations, and an Athena AI agent.
**Pricing**: Essential is free with 300 credits. Starter is $295/month with 3,600 credits and visibility across nine models. Enterprise pricing is custom.
**GEO strengths**: Pay-for-what-you-use model. Strong GEO optimization focus with expert-augmented recommendations. Human judgment layered on top of automated data.
**Limitations**: Public plan pricing is not displayed, so teams must request a quote and confirm limits during evaluation.
**Best for**: Mid-size to enterprise teams that want hands-on GEO guidance, not just dashboards.
### Writesonic
[Writesonic](https://writesonic.com/generative-engine-optimization-geo) connects visibility tracking, citation analysis, SEO, and content production. Starter, Basic, and Growth track ChatGPT, Gemini, and Google AI Overviews. Enterprise expands coverage to 10 AI platforms.
**Pricing**: Starter begins at $79/month billed annually; Basic is $199/month billed annually. Enterprise is custom.
**GEO strengths**: Broadest engine coverage in the category. Real-time visibility scores, sentiment, and citation tracking. Reddit and UGC forum monitoring tied to citation gap fixing. Built-in content creation closes the loop from "we're invisible here" to "publish the page that fixes it."
**Limitations**: Less depth on competitive benchmarking than purpose-built diagnostic tools. The bundled writing-plus-tracking model can feel diffuse if you only want monitoring.
**Best for**: Content marketing teams that want one platform spanning GEO tracking, citation analysis, and content production.
### Conductor
[Conductor](https://www.conductor.com/) is the enterprise-grade end of the GEO market. Its AI Search Performance product connects AI visibility data with the content driving citations, audience interactions with that content, and the competitive landscape around the category. Conductor publishes the [annual AEO/GEO Benchmarks Report](https://www.conductor.com/academy/aeo-geo-benchmarks-report/), one of the largest cross-industry datasets on AI-driven brand visibility.
**Pricing**: Enterprise custom. Request a current quote and confirm which AI features are included.
**GEO strengths**: Most mature integrated AEO + GEO + SEO platform on the market. Enterprise security, compliance features, and integration depth. Annual benchmark research that informs the broader category.
**Limitations**: Enterprise pricing model not built for startups or lean marketing teams.
**Best for**: Fortune 500 marketing teams with mature content operations and budget for an integrated platform.
## GEO Tools Comparison Table
| Platform | Starting Price | AI Engines | Citation Analysis | Content Creation | Actionable Recs | Best For |
|----------|---------------|------------|-------------------|-----------------|----------------|----------|
| Otterly AI | $29/mo | 6 | Yes (link citations) | No | No | Broad monitoring on a budget |
| Peec AI | $95/mo | 3 (selected) | Yes | No | Yes (Actions roadmap) | Action prioritization |
| friction AI | $69/mo | 4+ | Yes (with credibility scoring) | No | Yes (prioritized + Experiments) | Diagnostic depth |
| AthenaHQ | Free; $295/mo Starter | 5 on Essential; 9 on Starter | Yes | Yes | Yes | Credit-based action workflows |
| Writesonic | $79/mo annual | 3 on Starter; 10 on Enterprise | Yes | Yes | Yes | Content + GEO in one tool |
| Conductor | Enterprise | Multiple | Yes | Yes | Yes | Fortune 500 / regulated |
## How to Choose Your GEO Platform
Five questions to ask before picking a tool.
**1. Do you need content production or pure monitoring?**
Writesonic and Conductor combine monitoring with broader SEO or content workflows. friction AI and Peec emphasize prioritized actions, Otterly offers a lighter monitoring baseline, and AthenaHQ adds content recommendations and action workflows. Compare teh workflow you will use, not just the number of features.
**2. How many AI engines actually matter to your audience?**
If your buyers are mostly using ChatGPT, you don't need 10-engine coverage. If you sell into research, analyst, or enterprise segments, broader coverage (Perplexity, Gemini, Claude, Copilot) matters more.
**3. Are you optimizing for monitoring or action?**
Otterly provides a lightweight monitoring baseline. friction AI and Peec AI surface prioritized actions. AthenaHQ adds credit-based content and action workflows. Review the evidence behind every reccomendation before assigning work.
**4. What's your existing tooling stack?**
If you're already on a major SEO suite (Ahrefs, Semrush, SE Ranking), [their AI visibility add-ons](/blog/best-ai-visibility-tools-compared-2026) may cover enough of the GEO surface to start. If GEO is becoming a primary discipline, a dedicated platform goes deeper.
**5. What's your budget reality?**
AthenaHQ offers a free Essential tier, while published paid self-serve plans in this comparison range from $29 to $495 per month. Conductor and AthenaHQ Enterprise use custom pricing. Match the package to your prompt volume, markets, integrations, and team size.
## GEO vs AEO: Which Tools to Pick
The right framing isn't "GEO tool or AEO tool." It's: what does your team actually need to track and act on?
- **Need answer-engine specific tracking?** Any platform on this list works. The pure-AEO platforms ([Otterly, Profound, Peec, friction AI](/blog/best-aeo-platforms-2026)) go deepest on the answer surface.
- **Need broader generative surface coverage?** Writesonic, Conductor, and friction AI extend beyond pure AEO into entity strength, knowledge graph signals, and content-driven citation building.
- **Need both?** Most teams end up with two tools: a dedicated AEO/GEO platform plus an existing SEO suite that's added AI features. See our [stack composition recipes](/blog/best-ai-visibility-tools-compared-2026) for specific combinations by team type.
## The Category Is Still Maturing
GEO tooling in 2026 is in roughly the same phase that SEO tooling was in 2010. Lots of vendors solving overlapping slices. Pricing models still being tested. Feature sets evolving monthly. The platforms leading today won't necessarily lead a year from now.
What won't change is the underlying shift. It's not about ranking on page 1.
It's about being the answer AI gives across every generative surface where your category lives. The brands that start optimizing for GEO now will compound an advantage over brands that wait for the category to settle.
For background on the underlying discipline, see [AEO explained for 2026](/blog/aeo-explained-guide-2026). For comparison of dedicated AEO platforms specifically, see [best AEO platforms 2026](/blog/best-aeo-platforms-2026). For the broader AI visibility tooling landscape including SEO suites and brand monitors, see [best AI visibility tools compared 2026](/blog/best-ai-visibility-tools-compared-2026). For the integration playbook, see [SEO and AEO working together](/blog/seo-and-aeo-together).
## Frequently Asked Questions
### What's the difference between GEO and AEO tools?
GEO (Generative Engine Optimization) is the broader category. It covers brand presence across all generative AI outputs, including answer engines, content generation, AI agents, and knowledge graph signals. AEO (Answer Engine Optimization) is the subset focused specifically on the question-and-answer surface. Most modern tools do both; the distinction matters mainly for tooling depth in non-question generative surfaces.
### How much should I expect to pay for a GEO tool?
AthenaHQ offers a free Essential tier; published paid self-serve plans start at $29/month. Conductor and AthenaHQ Enterprise use custom pricing. Confirm current prices, engine coverage, and limits directly with each vendor.
### Can I use GEO tools without an existing SEO program?
Yes. GEO tooling is independent of SEO tooling, and a brand new to both disciplines can start with a GEO platform. That said, the integrated workflow ([SEO and AEO together](/blog/seo-and-aeo-together)) produces better results faster because the foundations overlap.
### Which GEO tool covers the most AI engines?
Writesonic Enterprise covers 10 AI platforms, while its lower tiers cover ChatGPT, Gemini, and Google AI Overviews. Otterly includes four engines in its base plans and offers Gemini, Google AI Mode, and Claude as add-ons. Coverage varies by plan, so compare the tier you would actually buy.
### Do I need a separate GEO tool if I already have an AEO tool?
Probably not. The categories overlap heavily, and most "AEO platforms" do GEO work. Check whether your current platform tracks the broader generative surfaces you care about (entity strength, content-driven citations, knowledge graph signals). If yes, you're covered.
### How quickly do GEO tools show measurable results?
There is no universal timeline. Re-run a stable prompt set after each material change, record when pages and third-party sources are updated, and judge progress from repeated measurements rather than a fixed promise.
## Start Tracking Your GEO Performance
friction AI shows you exactly what AI says about your brand, which sources it cites, what keywords each model searches, and where competitors outperform you. Track visibility, sentiment, and purchase intent across ChatGPT, Gemini, Perplexity, and Google AI Overviews on a nightly cadence.
[](/pricing)
[See pricing](/pricing)
## Related Articles
- [AEO Explained: The Complete 2026 Guide](/blog/aeo-explained-guide-2026)
- [Best AEO Platforms 2026: 6 Top Tools Compared](/blog/best-aeo-platforms-2026)
- [Best AI Visibility Tools Compared 2026](/blog/best-ai-visibility-tools-compared-2026)
- [SEO and AEO: How They Work Together](/blog/seo-and-aeo-together)
---
*Pricing figures verified against public vendor pages as of April 2026. GEO tooling pricing changes frequently; check vendor sites for current plans before committing.*
---
# Best AI Visibility Tools Compared 2026: The Full Landscape
# URL: https://www.frictionai.co/blog/best-ai-visibility-tools-compared-2026
# Slug: best-ai-visibility-tools-compared-2026
# Category: Tool Comparisons
# Published: 2026-04-18
# Author: Joao Da Silva, Co-Founder of friction AI
# Keywords: best ai visibility tools 2026, ai visibility tracking, ai visibility platforms, chatgpt visibility tools, ai brand monitoring, ai search visibility tools, llm visibility tracking, ai search optimization tools, generative ai monitoring tools, ai visibility software
# Best AI Visibility Tools Compared 2026: The Full Landscape
Most marketing teams now run at least two AI visibility tools. One that tells them what ChatGPT says. One that tells them what to do about it. Few do both well.
Before evaluating tools, run a free [AI visibility audit](/blog/15-prompt-ai-visibility-audit) on your own brand to know which audit layers (entity recognition, visibility, recommendation) are actually leaking. That gives you criteria to match tool selection to your weakest layer instead of picking blind.
## TL;DR
- **AI visibility tools** track how your brand appears across AI-generated outputs (ChatGPT, Perplexity, Gemini, Google AI Overviews, Claude, Copilot) and help you improve your position.
- The category splits into four buckets: dedicated AEO platforms, SEO suites with AI features, brand monitoring tools, and DIY approaches.
- **Dedicated AEO platforms** (friction AI, Otterly AI, Profound, Peec AI) are deepest on AI-specific signals. Best for teams treating AI visibility as a core discipline.
- **SEO suites with AI features** (Ahrefs Brand Radar, Semrush AI Toolkit, SE Ranking) are good if you already pay for the suite and want AI tracking as an extension.
- **Brand monitoring tools** (Brand24, Mention) cover sentiment and forum mentions but miss the citation and answer-engine layer.
- Most teams end up running two tools: one dedicated AEO platform plus one general monitoring tool. Stack composition matters more than picking a single winner.

## Why "AI Visibility" Is a Real Category Now
ChatGPT, Google AI Overviews, Perplexity, Claude, and Gemini all shape discovery in different contexts. Cross-engine measurement is useful, but each system and prompt set needs to be evaluated on its own terms.
Together these surfaces represent a new demand layer. A buyer asking "what's the best CRM for a 50-person sales team" doesn't see your Google ranking. They see whatever ChatGPT tells them.
The problem? Traditional SEO tools weren't built to monitor this layer. Ahrefs and Semrush track Google rankings. Brand24 and Mention track social and news sentiment. Neither answers the question "what does ChatGPT say about us when a buyer asks?"
AI visiblity tools fill that gap. Some specialize. Some are extensions of existing platforms. Each solves a slightly different slice of the problem.
For background on the underlying discipline, see our [AEO explained guide for 2026](/blog/aeo-explained-guide-2026).
## The Four Categories of AI Visibility Tools
Not every AI visibility tool does the same thing. Before comparing options, decide wich category solves your problem.
### Category 1: Dedicated AEO Platforms
**What they do**: Run prompts on a schedule across multiple AI engines, parse the responses, and track citation share, mention rate, sentiment, and competitive position over time.
**Best for**: Teams treating AI visibility as a primary marketing discipline.
**Trade-off**: Single-purpose tools. You'll likely run one alongside your existing SEO and brand monitoring stack.
### Category 2: SEO Suites with AI Features
**What they do**: Existing SEO platforms (Ahrefs, Semrush, SE Ranking, Conductor) have added AI visibility tracking as features within their broader platform.
**Best for**: Teams already paying for a major SEO suite who want AI tracking as an extension.
**Trade-off**: Less depth than dedicated AEO platforms. Engine coverage is usually narrower. Often bundled into higher-priced enterprise tiers.
### Category 3: Brand Monitoring Tools
**What they do**: Brand24, Mention, Brandwatch, and similar tools track brand mentions across the web, social, news, and forums. Many have added AI-source monitoring as their content sources expand.
**Best for**: Teams that already use a brand monitor and want AI sources folded into the same dashboard.
**Trade-off**: They monitor mentions, not the answer-engine layer specifically. You'll see when AI-generated content mentions you, but not what the AI engines say in real-time when prompted.
### Category 4: DIY / Manual Approaches
**What they do**: Spreadsheets. Custom scripts. Manual prompt batches run weekly. Open-source AI visibility scripts.
**Best for**: Solo founders, very early-stage startups, or teams running a one-time baseline before investing in tooling.
**Trade-off**: Time-intensive and inconsistent. Doesn't scale past one or two brands.
## Category 1: The Best Dedicated AEO Platforms
*Prices last verified on vendor pages: July 22, 2026. Monthly equivalent shown; annual billing may be required.*
The dedicated AEO category is the most active and the most rapidly evolving slice of AI visibility tooling. Six platforms anchor the conversation.
### Otterly AI
Otterly AI includes ChatGPT, Perplexity, Google AI Overviews, and Microsoft Copilot in its base plans. Gemini, Google AI Mode, and Claude are optional add-ons. Its interface is accessible to non-technical marketing teams.
**Pricing**: Lite $29/month (15 prompts), Standard $189/month, Premium $489/month.
**Weaknesses**: The Lite plan's 15-prompt limit is restrictive for serious monitoring. No content creation tools. Limited diagnostic depth on why you're not appearing in AI answers.
**Strongest for**: Marketing teams and agencies that want broad engine coverage and a simple onboarding curve.
### Profound
Enterprise-positioned. Detailed analytics, daily tracking, SOC 2 compliance, SSO, and API access on Enterprise plans.
**Pricing**: Starter $99/month (ChatGPT only), Growth $399/month (3 engines), Enterprise custom.
**Weaknesses**: Expensive. The $99 Starter plan covers ChatGPT only. Multi-engine monitoring starts with Growth at $399/month, while Enterprise pricing is custom.
**Strongest for**: Regulated industries that need compliance and enterprise security.
### friction AI
friction AI focuses on the diagnostic layer of AI visibility. Per-provider score breakdowns, source credibility scoring, search query extraction (which keywords each AI model actually searched when researching your brand), and an Experiments framework for running A/B and pre/post tests against visibility outcomes.
**Pricing**: Starts at $69/month.
**Weaknesses**: No content generation or writing features. Newer platform with a smaller user base than established competitors. Currently focused on diagnostics rather than content production workflows.
**Strongest for**: Teams that want to understand the mechanics of why AI does or doesn't recommend them and act on the data.
### Peec AI
Differentiator is the Actions feature: visibility data clustered into a prioritized roadmap of owned and earned media opportunities. Unlimited seats on every tier.
**Pricing**: Starter $95/month, Pro $245/month, Advanced $495/month, Enterprise custom.
**Weaknesses**: Gemini, Google AI Mode, and Claude require paid add-ons. Lite includes 15 prompts, so wider tracking can raise the total cost quickly.
**Strongest for**: Teams that want fast translation from monitoring data to a to-do list.
### AthenaHQ
Credit-based tracking with source analysis, content recommendations, and action workflows.
**Pricing**: Essential is free with 300 credits. Starter is $295/month with 3,600 credits and visibility across nine models. Enterprise is custom.
**Weaknesses**: Credit-based usage is harder to compare with prompt-based plans. Calculate expected responses and model coverage before choosing a tier.
**Strongest for**: Teams that want a free baseline or a credit-based workflow connecting monitoring to recommendations and actions.
For a direct look at how the two enterprise leaders stack up head-to-head, see our [Profound vs AthenaHQ comparison](/blog/ai-visibility-platform-comparison-2026).
### Writesonic
Writesonic combines GEO monitoring, SEO, and content workflows. Starter, Basic, and Growth track ChatGPT, Gemini, and Google AI Overviews; Enterprise expands coverage to 10 platforms.
**Pricing**: Starter $79/month billed annually; Basic $199/month billed annually; Enterprise custom.
**Weaknesses**: Less depth on competitive benchmarking than purpose-built AEO tools. The bundled writing-plus-tracking model can feel diffuse if you only want monitoring. No search query extraction.
**Strongest for**: Content marketing teams that want tracking and content production in one workflow.
For a deeper head-to-head comparison of these six platforms, see our [best AEO platforms 2026 comparison](/blog/best-aeo-platforms-2026).
## Category 2: SEO Suites with AI Visibility Features
The major SEO platforms have all added some form of AI visibility tracking. Coverage and depth vary widely.
### Ahrefs Brand Radar
[Brand Radar](https://ahrefs.com/brand-radar) tracks brand visibility across Google AI Overviews, Google AI Mode, ChatGPT, Perplexity, Gemini, and Copilot. It reports visibility, share of voice, and brand coverage, with custom prompt tracking available for teams that need a controlled query set.
**Pricing**: Check Ahrefs' current Brand Radar pricing page; packaging can vary by index and subscription.
**Strongest for**: Teams already on Ahrefs who want AI tracking inside the same suite, particularly the search-backed prompt sourcing.
**Limitation**: Total cost adds up fast once you stack the AI bundle on a paid Ahrefs plan. Sampling has been called out as partial in some reviews.
### Semrush AI Visibility Toolkit
[Semrush's AI Visibility Toolkit](https://www.semrush.com/kb/1493-ai-visibility-toolkit) tracks daily brand visibility in ChatGPT Search and Google AI Mode, generates an AI Visibility Score (0-100) benchmarked against competitors, surfaces brand mentions and sentiment, and runs a site audit for AI crawler-blocking technical issues.
**Pricing**: Check Semrush's current AI visibility pricing; packaging and prompt limits change by plan.
**Strongest for**: Existing Semrush customers who want AI visibility data in the same workspace as their SEO and competitive research.
**Limitation**: Engine coverage is narrower than dedicated AEO platforms (ChatGPT Search and Google AI Mode are core; broader engines vary by tier). No search query extraction.
### SE Ranking (AI Visibility Tracker / SE Visible)
[SE Ranking's AI visibility stack](https://seranking.com/ai-visibility-tracker.html) covers Google AI Overviews, Google AI Mode, ChatGPT, Gemini, and Perplexity with brand mention and link tracking, source analysis showing which domains AI cites in overviews, historical SERP data with cached snapshots, and a "No cited" feature that flags competitor mentions where your brand is missing. The standalone [SE Visible product](https://visible.seranking.com/) extends this further as a dedicated AI visibility platform.
**Strongest for**: Mid-market teams that want traditional SEO and AI visibility in the same suite and can validate the current package against their prompt volume.
**Limitation**: Less brand-side diagnostic depth than purpose-built AEO platforms. No search query extraction.
### Conductor (AI Search Performance)
[Conductor](https://www.conductor.com/) positions itself as the most mature enterprise-grade AEO + GEO + SEO platform. Its [AI Search Performance product](https://www.businesswire.com/news/home/20260401188763/en/Conductor-Delivers-Next-Generation-AI-Search-Performance-Introducing-the-Industrys-Only-System-of-Record-for-AEO) connects AI visibility data with the content driving citations, audience interactions with that content, and the competitive landscape around your category. Conductor publishes the [annual AEO/GEO Benchmarks Report](https://www.conductor.com/academy/aeo-geo-benchmarks-report/), one of the largest cross-industry datasets on AI-driven brand visibility.
**Strongest for**: Fortune 500 marketing teams with existing enterprise SEO programs, mature content operations, and budget for an integrated platform.
**Limitation**: Enterprise pricing is custom and requires a sales process. It is not built for startups or lean teams.
(Note: Gauge at withgauge.com is a separate AEO platform, not a Conductor product, despite occasional confusion. It sits closer to the dedicated AEO category at $99/month entry pricing.)
## Category 3: Brand Monitoring Tools With AI Sources
Traditional brand monitors have started ingesting AI-generated content as content sources. They're not built to query the answer engines directly, but they catch downstream AI-generated mentions.
### Brand24
Established social and web mention monitor. Has added AI-generated content sources to its monitoring feed.
**Strongest for**: Teams that already use Brand24 for social and want to fold AI mentions into the same dashboard.
**Limitation**: Doesn't query AI engines on a prompt schedule. You'll catch mentions when AI content gets indexed, not when ChatGPT recommends you in real-time.
### Mention
Similar positioning to Brand24. Real-time web and social monitoring with sentiment analysis. Has expanded source coverage to include AI outputs.
**Strongest for**: PR and comms teams already using Mention.
**Limitation**: Same as Brand24. Mentions, not citations or recommendations.
### Brandwatch
Enterprise social listening platform with deep sentiment analytics. AI-generated content is now in its source mix.
**Strongest for**: Large enterprise comms teams.
**Limitation**: Pricing and complexity overshoot most marketing teams. Built for social listening first.
## Category 4: DIY and Manual Approaches
For teams not yet ready for paid tooling.
### Manual Prompt Baselining
Pick 20 to 30 representative category prompts. Run each one weekly in ChatGPT, Perplexity, Gemini, and Google AI Overviews. Record mentions, citations, and sentiment in a spreadsheet.
**Best for**: Solo founders or very early-stage teams establishing a baseline.
**Limitation**: Doesn't scale. Easy to skip weeks. Hard to spot trends without consistent data structure.
### Open-Source Visibility Scripts
GitHub has a growing collection of open-source scripts that automate prompt batches against AI APIs and parse responses.
**Best for**: Technical teams comfortable maintaining custom code.
**Limitation**: Maintenance burden. API costs add up. No competitive benchmarking out of the box.
## How to Build an AI Visibility Stack
I tested every platform in this guide before shipping friction AI. The stacks below are what I'd actually recommend to a peer, not the setup that maximizes my own product's footprint.
Most teams end up with two tools, not one. The right combination depends on what you already have and what gap you're trying to close.
### Stack A: Solo Founder / Early Startup
- **Manual baseline** (free, weekly spreadsheet)
- Move to **Otterly AI Lite** ($29/month) once you outgrow the manual approach
### Stack B: SEO Team Adding AEO
- **Existing SEO suite** (Ahrefs, Semrush) for traditional SEO
- **friction AI** ($69/month) for AEO diagnostics and search query extraction
### Stack C: Marketing Team With No Existing Stack
- **Otterly AI Standard** ($189/month) for broad AEO monitoring
- **Brand24** for general brand mention monitoring across social and web
### Stack D: Enterprise / Regulated Industry
- **Profound** ($399/month Growth, billed annually) for compliance-grade AEO tracking
- **Brandwatch** for enterprise social listening
- **Conductor** for traditional SEO
### Stack E: Content-Heavy Team
- **Writesonic** ($79/month Starter, billed annually) for combined tracking and content production
- **friction AI** ($69/month) layered on top for diagnostic depth
## How to Choose Your AI Visibility Stack
Three questions to ask before picking tools.
**1. Is AI visibility a core discipline or a side metric?**
If it's core, invest in a dedicated AEO platform. Generic SEO suites with AI features will leave you blind to engine-specific behaviors.
**2. Do you need monitoring or optimization?**
Otterly and Brand24 emphasize monitoring. friction AI and Peec AI surface actions. AthenaHQ connects monitoring with content recommendations and action workflows. Compare the evidence and implementation path behind each recommendation.
**3. How many AI engines actually matter to your audience?**
If your buyers are mostly using ChatGPT, you don't need 10-engine coverage. If you sell into research, analyst, or enterprise segments, Perplexity, Gemini, and Claude all matter and you need broader coverage.
## The AI Visibility Tooling Market Will Consolidate
The current category looks like the SEO tooling market in 2010. Lots of point solutions. Different vendors solving overlapping slices. Pricing models still being tested. By 2028 expect significant consolidation through M&A and feature expansion.
The dedicated AEO platforms will absorb features from brand monitors. SEO suites will close the gap on dedicated AEO tools or partner with them.
For now, picking the right stack matters more than picking the right single tool. Get the right combination of monitoring, diagnostics, and action surface, and you'll cover the demand layer that traditional tools miss.
For the deep comparison of dedicated AEO platforms, see our [best AEO platforms 2026 guide](/blog/best-aeo-platforms-2026). For the underlying discipline, see [AEO explained for 2026](/blog/aeo-explained-guide-2026).
## Frequently Asked Questions
### What's the difference between AI visibility tools and SEO tools?
SEO tools track rankings, backlinks, and organic traffic on traditional search engines like Google and Bing. AI visibility tools track how your brand appears in AI-generated answers from ChatGPT, Perplexity, Gemini, Google AI Overviews, and similar engines. The two surfaces don't fully overlap; you can rank #1 on Google and still be invisible in ChatGPT.
### Do I need a dedicated AI visibility tool, or can I add it to my existing SEO platform?
It depends on how core AI visibility is to your strategy. If it's a side metric, the AI features in Ahrefs, Semrush, or SE Ranking are enough. If it's a primary discipline, dedicated AEO platforms (friction AI, Otterly AI, Profound) go significantly deeper on engine-specific signals, source credibility, and search query extraction.
### How much should I expect to pay?
AthenaHQ offers a free Essential tier. Other published entry plans in this comparison start at $29 to $99 per month, and mid-tier plans range from $189 to $495 per month. Enterprise pricing for Profound, AthenaHQ, and Conductor is custom. Compare the exact engine, prompt or credit, region, and user limits in the tier you would buy.
### Can I track AI visibility for free?
You can baseline manually by running prompts in each engine and recording results in a spreadsheet. That works for a one-time snapshot. For ongoing tracking, free options don't exist at meaningful scale; even open-source scripts incur API costs.
### Which AI engines should my tool cover?
At minimum: ChatGPT, Perplexity, and Google AI Overviews. ChatGPT has the largest user base. Perplexity is heavily used by researchers and analysts. Google AI Overviews now appears across a significant share of high-intent queries. Add Gemini, Claude, and Copilot if you sell into Google Workspace, Anthropic, or Microsoft-heavy environments.
### How often should AI visibility data refresh?
Daily is ideal. Weekly is the practical minimum for catching meaningful changes. Monthly cadence misses too many engine updates and prompt-level shifts. Most paid platforms run on a daily or near-daily cadence.
## Start Tracking Your AI Visibility
friction AI shows you exactly what AI says about your brand, which sources it cites, what keywords each model searches, and where competitors outperform you. Track visibility, sentiment, and purchase intent across ChatGPT, Gemini, Perplexity, and Google AI Overviews on a nightly cadence.
[](/pricing)
[See pricing](/pricing)
## Related Articles
- [Best AEO Platforms 2026: Answer Engine Optimization Tools Compared](/blog/best-aeo-platforms-2026)
- [AEO Explained: The Complete Guide for 2026](/blog/aeo-explained-guide-2026)
- [SEO and AEO: How They Work Together](/blog/seo-and-aeo-together)
- [Best GEO Tools 2026](/blog/best-geo-tools-2026)
---
*Tool feature descriptions reflect publicly available information as of April 2026. AI visibility tooling moves fast; verify vendor pages for current capabilities and pricing before purchasing.*
---
# How to Check Your Brand's AI Visibility (Video Tutorial)
# URL: https://www.frictionai.co/blog/how-to-check-brand-ai-visibility-video-tutorial
# Slug: how-to-check-brand-ai-visibility-video-tutorial
# Category: Monitoring & Measurement
# Published: 2026-04-05
# Author: Joao Da Silva, Co-Founder of friction AI
# Keywords: ai visibility tutorial, check ai visibility, brand ai visibility, ai visibility video, chatgpt brand check, ai brand monitoring tutorial, geo tools tutorial, ai visibility score, friction ai demo, how to check ai visibility
50% of consumers now use AI-powered search, but only 16% of brands track how they perform there ([McKinsey](https://www.mckinsey.com/capabilities/growth-marketing-and-sales/our-insights/new-front-door-to-the-internet-winning-in-the-age-of-ai-search), 2025). Most brands don't know what ChatGPT says about them. They rank well on Google, they run SEO audits, they track share of voice on social. But when a buyer asks Gemini or Perplexity for a recommendation in their category, they have no idea whether they show up, how they're described, or which competitors are quietly winning the answer.
This video tutorial walks through the friction AI onboarding and dashboard, using Puma as the example brand. By the end of the 12-minute walkthrough, you'll know how to set up your own brand, run your first visibility analysis, and read the scores that matter.
> **TL;DR**
> - Checking your brand's AI visibility takes about 15 minutes to set up and runs continuously after that.
> - The onboarding flow covers brand details, market selection, up to 5 competitors, and three prompt types: LLM prompts, search queries, and commerce prompts.
> - The dashboard shows visibility score, sentiment, purchase intent, keywords AI models use to find you, and a prompt-by-prompt breakdown of where you appear and where competitors beat you.
> - Walkthrough video: 12 minutes. Written step-by-step instructions below.
---
## Watch the Full Tutorial
[](https://youtu.be/Tj1UwEm1Xg4)
## Video Chapters
| Timestamp | Section |
|-----------|---------|
| [0:00](https://youtu.be/Tj1UwEm1Xg4?t=0) | Intro: what friction AI does |
| [0:30](https://youtu.be/Tj1UwEm1Xg4?t=30) | Step 1: Add brand details |
| [1:32](https://youtu.be/Tj1UwEm1Xg4?t=92) | Step 2: Select your target market |
| [3:03](https://youtu.be/Tj1UwEm1Xg4?t=183) | Step 3: Add competitors (1-5) |
| [4:34](https://youtu.be/Tj1UwEm1Xg4?t=274) | Step 4: Pick visibility prompts |
| [6:05](https://youtu.be/Tj1UwEm1Xg4?t=365) | LLM prompts vs search queries vs commerce prompts |
| [7:35](https://youtu.be/Tj1UwEm1Xg4?t=455) | Commerce and purchase-intent prompts |
| [9:06](https://youtu.be/Tj1UwEm1Xg4?t=546) | Dashboard tour |
| [10:39](https://youtu.be/Tj1UwEm1Xg4?t=639) | Brand audit section: prompts and recommendations |
| [12:11](https://youtu.be/Tj1UwEm1Xg4?t=731) | Keywords AI uses to search for your brand |
---
## Step 1: Add your brand details
The onboarding starts with three fields: brand name, website, adn category.
The example uses Puma (puma.com). Getting the domain right matters. friction AI uses the domain to verify the brand identity, find the logo, and align the analysis with the correct entity. If you have multiple domains (a .com and regional versions), pick the canonical one that represents the brand globally.
If the logo that appears isn't yours (common with short brand names that collide with others), go back and correct the domain before continuing. Catching this early saves later confusion when the visibility scores reference the wrong entity.
## Step 2: Select your target market
You pick the country where you want the analysis to run. The tutorial uses the UK. This determines which regional AI responses get measured. If your brand sells globally, start with your biggest market and add others later. Running every prompt in every market is expensive and rarely changes the diagnosis.
Markets aren't just about language. The same prompt in different regions can produce different answers because AI models weight local sources, regional news coverage, and country-specific retailers differently.
## Step 3: Add your competitors
Depending on plan tier, you add 1-5 competitors. These aren't decorative. The platform runs the same prompts against your brand and each competitor, then generates gap analysis showing where competitors win visibility, where you win, and which prompts are contested.
Pick competitors your buyers actually consider. A top-of-funnel competitor (big-brand awareness) and a bottom-of-funnel competitor (someone your sales team loses deals to) surface different insights. Don't pick competitors you "should" beat on brand size. Pick the ones you lose deals to.
## Step 4: Pick your prompts
This is where most of the setup work happens. friction AI offers three prompt types, and they measure different things:
**LLM prompts** run against ChatGPT, Claude, Gemini, and Perplexity. These test how the models answer general category questions without doing live web search. Example: "What are the best sneaker brands for running?"
**Search queries** run against Google AI Overviews and Google AI Mode. These include live web retrieval. Example: "Puma running shoes review."
**Commerce prompts** are bottom-of-funnel, buying-intent queries. "Where can I buy Puma running shoes online?" is a commerce prompt. These matter because AI models increasingly handle purchase decisions directly, and being invisible here means losing sales, not just awareness.
You can pick from the recommended prompt library or write your own. Starting with recommended prompts is usually faster because they're calibrated to your category.
## Step 5: Read your dashboard
Once the first analysis runs (takes a few minutes after onboarding completes), the dashboard shows four main sections:
**Visibility score.** How often AI models mention your brand when asked relevant category questions. Expressed as a percentage across all prompts and providers. A score of 60 means your brand appeared in 60% of the responses.
**Sentiment.** How AI models describe your brand when they do mention it. Positive sentiment means AI uses phrases like "high quality," "trusted," "recommended." Negative sentiment means AI describes you with hedge words, complaints, or unfavorable comparisons.
**Purchase intent.** Whether AI models recommend your brand when someone asks a buying-stage question. A brand with high visibility but low purchase intent is known but not preferred.
**Brand audit.** The specific prompts where you appear, the prompts where you don't, and where competitors beat you. This is where you find actionable fixes.
## Step 6: Understand keywords AI uses for your brand
The keywords section shows the search queries AI models run when researching your brand. This is non-obvious and valuable. If ChatGPT searches "Puma running shoes durability review" when a user asks about Puma, and you don't rank on Google for that exact query, your invisible to ChatGPT on that topic.
Bridging AI visibility and SEO happens here. The keywords list tells you exactly which Google search rankings matter for your AI presence, and which ones you're currently losing.
---
## What to expect after your first analysis
The first analysis is rarely flattering. [Gartner](https://www.gartner.com/en/newsroom/press-releases/2024-02-19-gartner-predicts-search-engine-volume-will-drop-25-percent-by-2026) projects a 25% decline in traditional search by 2026, which means the gap keeps widening for brands that don't act. Most brands discover:
- They're invisible on 40-70% of category prompts they assumed they'd win
- Their sentiment is neutral or mixed, not positive
- Competitors they didn't think were AI-native are beating them on purchase intent
- AI models are searching for information about them using queries they don't rank for on Google
That's not a failure signal. It's a diagnosis. The point of the audit is to replace guesswork with specific, fixable gaps. The follow-up work (content, schema, authority signals) is far easier when you know exactly where the gaps are.
---
## Frequently Asked Questions
### How long does the full onboarding take?
About 15 minutes end-to-end. Brand details and market selection take a minute. The longest step is picking prompts, especially if you customize beyond the recommended library. First analysis runs within a few minutes of completing onboarding.
### Do I need technical setup or code changes?
No. Onboarding is form-based. You don't install a pixel, embed a tag, or change your site. friction AI queries AI models externally the same way a user would.
### Can I change competitors or prompts after onboarding?
Yes. The dashboard lets you add, remove, or swap competitors and prompts at any time. Changes apply to future analyses, not historical ones, so you keep the history of what the old configuration showed.
### How often does the analysis run?
Depending on plan tier, analyses run nightly, weekly, or on-demand. Most teams start weekly to watch trends without drowning in daily noise, then move to nightly once they have active optimization work in flight.
### What if the AI models' answers seem to contradict each other?
Expected. ChatGPT and Gemini have different training data, different retrieval strategies, and different preference rankings. The point of monitoring multiple providers is to catch exactly this. friction AI's per-provider breakdown shows which model rates you high, which rates you low, and where the disagreement is.
---
## Related Reading
- [What is GEO? Generative Engine Optimization Guide](/blog/what-is-geo-generative-engine-optimization)
- [How to Measure AI Visibility](/blog/how-to-measure-ai-visibility)
- [What is AI Visibility? Definition, Examples & Why It Matters](/blog/what-does-ai-visibility-mean)
- [How to Improve Visibility in AI Search](/blog/how-to-improve-visibility-in-ai-search)
[](https://www.frictionai.co/pricing)
*Tutorial runtime: 12 minutes 44 seconds. Example brand: Puma. Onboarding flow current as of April 2026. Subsequent UI changes may shift specific labels but the setup flow remains equivalent.*
---
# How to Track Your Brand Visibility in Perplexity (2026 Guide)
# URL: https://www.frictionai.co/blog/track-brand-visibility-perplexity
# Slug: track-brand-visibility-perplexity
# Category: Platform Playbooks
# Published: 2026-04-02
# Author: Joao Da Silva, Co-Founder of friction AI
# Keywords: track brand visibility perplexity, perplexity brand monitoring, perplexity AI tracking, monitor brand mentions perplexity, perplexity visibility tracking, perplexity brand analytics, track perplexity citations, how to track perplexity mentions
# How to Track Your Brand Visibility in Perplexity (2026 Guide)
> **Tracking across multiple AI platforms?** This guide covers Perplexity specifically. For the multi-platform workflow across ChatGPT, Claude, and Perplexity together, see [How to Track AI Brand Mentions Across ChatGPT, Claude & Perplexity](/blog/track-brand-mentions-across-ai-platforms).
**Perplexity brand tracking** is the practice of monitoring how Perplexity mentions, recommends, and cites your brand across its search answers.
Perplexity describes itself as an **AI-powered search engine that searches the web in real time**. Its answers include **citations and links to original sources**.
That makes Perplexity uniquely measurable compared with many chat style AI experiences, but it is important to seperate three different things:
- A **mention** is text in the answer that names your brand.
- A **citation** is a linked source Perplexity uses to support the answer.
- **Referral traffic** only happens if a user clicks a citation link. A citation or mention is not automatically a visit.
This guide covers what to track, how to do it manually, when to automate, and how to connect tracking data to content decisions. It uses a fictional brand called **Planway**, a mid-market project management tool, for illustrative examples.
## Why Perplexity tracking needs its own approach
If you are already [tracking visibility across AI platforms](/blog/how-to-measure-ai-visibility), Perplexity deserves separate treatment because its product mechanics affect what you can measure and how quickly results can change.
### Perplexity searches the web in real time
Perplexity positions itself as a real-time web search experience. That means your visibility can shift after you publish, update, or restructure a page, and it can also shift when competitors publish something new or when the web results Perplexity retrieves change.
From a tracking standpoint, the practical implication is not that results change on a guaranteed schedule, but that **changes can show up quickly enough that infrequent audits can miss meaningful movement**.
### Citations are explicit and link to sources
Perplexity answers include citations with links to the source pages. Do not assume a fixed number of citations per answer, because it varies by query and response.
For brand tracking, citations give you something concrete to measure:
- Which **URLs** Perplexity cites for the prompts that matter to you
- Whether Perplexity is citing **your pages**, competitor pages, or third-party reviews
- Whether your cited pages align with the **narrative** in the answer text
### Traffic is possible, but only via clicks
Perplexity can send referral traffic because citations are clickable links, but it is not automatic:
- **Citations can create referral traffic only when users click them.**
- A **mention** in the answer is still valuable for positioning, but it is not a visit unless the user clicks through somewhere.
This is why Perplexity tracking usually combines two views: what Perplexity says and cites, and what traffic you actually receive.
## Perplexity crawlers and what they mean for tracking
Perplexity documents two relevant crawlers:
- **PerplexityBot** indexes pages for Perplexity search results.
- **Perplexity-User** can fetch a page in response to a user request.
This matters when you're diagnosing visibility drops or inconsistencies:
- If you are seeing citations to a page, it may be because it is indexed and retrieved, or because it can be fetched on demand for a specific user request.
- If your pages are not showing up, you may need to check crawl accessibility, indexability, and whether your content is competitive for the underlying web results that Perplexity is drawing from.
Official references:
- https://www.perplexity.ai/help-center/en/articles/10352155-what-is-perplexity
- https://www.perplexity.ai/help-center/en/articles/10352895-how-does-perplexity-work
- https://docs.perplexity.ai/docs/resources/perplexity-crawlers
## Tracking on Perplexity vs ChatGPT
Many teams start with ChatGPT monitoring and then try to apply the same workflow to Perplexity. The overlap is partial.
| Dimension | Perplexity | ChatGPT |
|---|---|---|
| **Search behavior** | Searches the web as part of its answer process | ChatGPT Search may search automatically, depending on the query and experience |
| **Citations** | Search answers include linked citations | Search answers may include inline citations |
| **Measurable traffic** | Possible when users click citations | Possible when a search answer includes a link and the user clicks |
| **Useful tracking fields** | Mentions, recommendations, citations, cited URLs, competitor sources | Mentions, recommendations, citations when shown, and positioning |
The practical difference is consistency of the source inspection workflow. Perplexity is built around linked citations, while the citations available in ChatGPT depend on the search experience used for that answer.
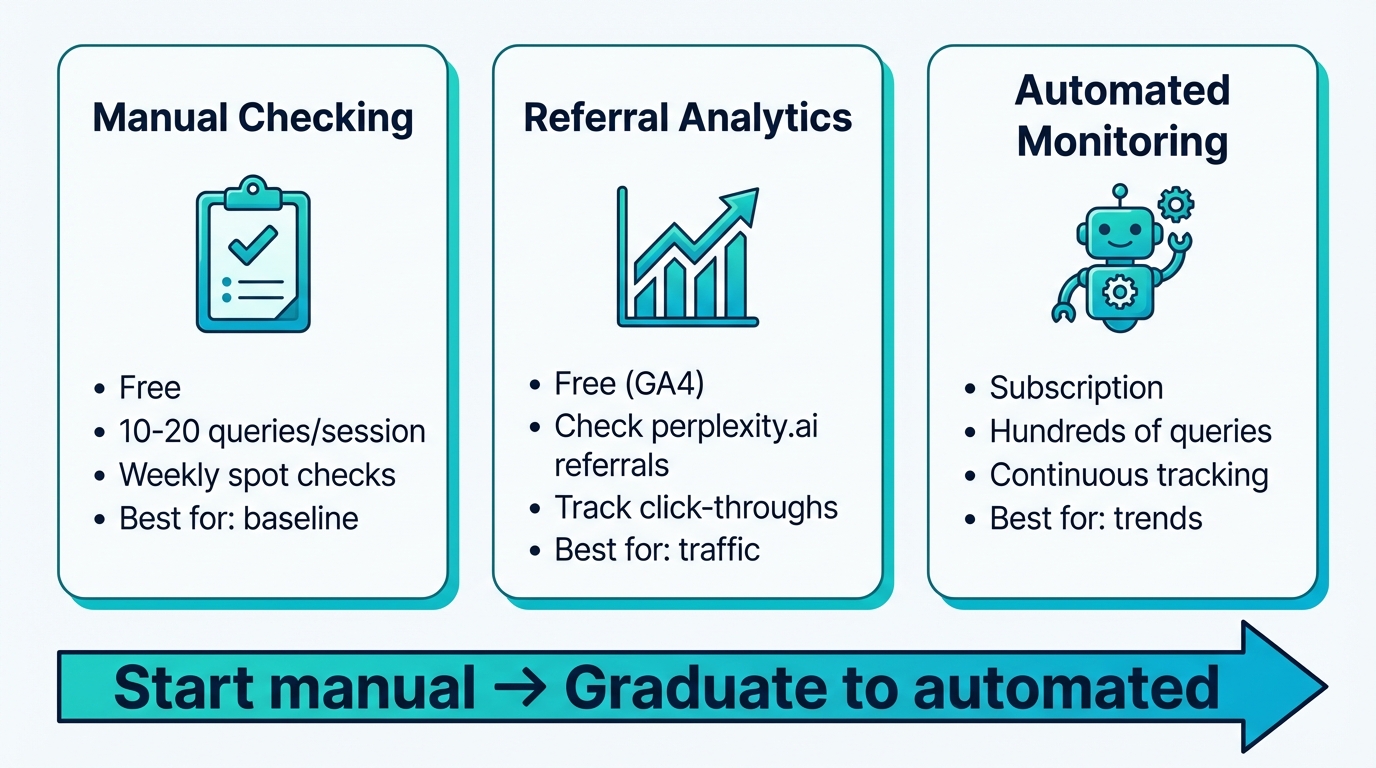
## What to track in Perplexity
Use the fictional brand Planway as a mental model for how each metric works.
### 1) Brand mentions
Track whether Perplexity names your brand in the answer text.
Why it matters:
- Mentions reflect **positioning**. Perplexity might cite you without naming you in the narrative, or name you without citing your site.
Illustrative example:
- Query: "What are the best project management tools for remote teams?"
- Outcome: Planway might be in a cited source list because a relevant article was used, but the answer text might recommend other tools by name. That is a **citation without a mention**.
### 2) Citations and cited URLs
Track which of your pages are cited and in which prompt contexts.
What to record:
- The cited **URL**
- Whether it is a **blog post**, comparison page, documentation page, homepage, or third-party coverage
- Whether the cited page matches the **intent** of the query
Why URL-level tracking matters:
- It tells you what Perplexity is using as evidence.
- It exposes concentration risk where most citations come from a single page.
Important correction to avoid over-interpreting:
- A citation is not the same as a recommendation.
- A citation can send traffic only when a user clicks it.
### 3) Competitor share of voice
When your brand appears, capture who else appears and how often.
Track at two levels:
- **Answer text**: which brands are named as recommendations or alternatives
- **Citations**: which domains and URLs are used as sources
This helps you separate two different problems:
- You are not being mentioned because competitors are being recommended.
- You are not being cited because competitor pages are supplying the source material.
### 4) Positioning and tone
Perplexity may describe your brand neutrally, favorably, or critically depending on the sources retrieved and the synthesis.
Track simple labels that your team can apply consistently, for example:
- Positive recommendation
- Neutral description
- Mixed
- Negative caution
Do not force precision that is not present. The goal is consistency over time, not perfect sentiment scoring.
### 5) Prompt coverage by journey stage
Perplexity visibility varies heavily by query type. Organize prompts into categories so you can see where you are strong and where you are absent.
Recommended categories:
- **Brand definition queries**: "What is Planway?" "What does Planway do?"
- **Category comparisons**: "Best project management tools" "Top PM platforms 2026"
- **Purchase intent questions**: "Is Planway worth it?" "Should I switch to Planway?"
- **Alternatives**: "Asana alternatives" "Monday.com alternatives"
- **Use-case queries**: "Best tool for sprint planning" "Best tool for remote sprint teams"
These categories also make it easier to assign ownership: product marketing often owns brand definition and purchase intent, while content and SEO often own category and use-case coverage.
## Manual tracking and where it breaks down
Manual checks are still the fastest way to get an initial picture.
A simple workflow:
1. Create a list of prompts across the five categories above.
2. Run each prompt in Perplexity.
3. Record:
- Answer date
- Whether your brand is mentioned
- Whether your site is cited
- Which URL is cited
- Which competitors are mentioned or cited
Illustrative sample spreadsheet rows for Planway:
| Prompt | Planway mentioned? | Planway cited? | Cited URL | Competitors mentioned |
|---|---|---|---|---|
| "Best PM tools for remote teams" | No | Yes | planway.com/blog/async-collab | Asana, Monday, ClickUp |
| "Planway vs Asana" | Yes | Yes | planway.com/compare/asana | Asana, Monday |
| "Asana alternatives" | Yes | No | n/a | Monday, ClickUp, Notion |
| "What is Planway?" | Yes | Yes | planway.com/about | n/a |
| "Best tool for sprint planning" | No | No | n/a | Jira, Linear, Shortcut |
How to interpret this pattern:
- Planway is present on branded and comparison queries.
- Planway is weak on category and use-case prompts.
- The cited URLs suggest which content types are currently doing the work.
Why manual tracking breaks down:
- Prompt sets grow fast once you include products, subcategories, and geographies.
- Comparing results over time becomes error-prone.
- You will miss changes unless you run checks regularly.
Manual tracking is best for:
- Initial baseline creation
- Investigating a sudden change you noticed elsewhere (for example, a traffic spike from Perplexity referrals)
- Reviewing how your brand is positioned in high stakes queries
## Measuring Perplexity referral traffic in analytics
Because Perplexity citations are links, you can measure traffic when users click them.
In Google Analytics 4:
- Look at **Traffic acquisition** and filter **source/medium** for entries containing "perplexity".
What this tells you:
- Which landing pages received visits from Perplexity
- Whether Perplexity is contributing meaningful sessions over time
What it does not tell you by itself:
- Which prompt produced the click
- Whether Perplexity mentioned your brand in the answer text
- How often you were cited without being clicked
Use analytics as a complementary signal, not a complete visibility score.
## Automated tracking options
As prompt volumes rise, automation becomes the only practical way to maintain a consistant view.
When evaluating tools for Perplexity monitoring, look for:
- **Perplexity as a distinct provider**, not merged into a generic bucket that hides citation mechanics
- **Citation-level outputs** including cited URLs, not only brand text mentions
- **Prompt-level history** so you can compare the same question over time
- **Competitor tracking** on the same prompt set
- **Exportability** so marketing and SEO teams can act on it in their existing workflows
Tools in this space include [friction AI](https://frictionai.co), Otterly, and Profound. Capabilities vary by product and plan, so validate the specific Perplexity outputs you need before you commit.
If your team has engineering resources, the **Perplexity API** can be used to build internal tracking pipelines, but you still need to define prompts, normalize outputs, and maintain a change log.
## Setting up a Perplexity tracking workflow
A workable workflow connects three parts: prompts, measurement cadence, and action rules.
### Choose your prompts
Start with 15 to 25 prompts across the five categories. Keep them stable for an initial baseline period, then expand.
Guidelines:
- Include your highest value category and use-case queries, not only branded prompts.
- Add a small number of uncertain prompts where you suspect competitors are stronger. Those gaps often create the clearest roadmap.
Illustrative example:
- Planway tracks "best tool for sprint planning" and finds no mention and no citations. That signals a content and positioning gap rather than a brand awareness gap.
### Set a cadence that matches how fast you need to react
Avoid hard rules like weekly minimum or daily ideal. Instead choose based on:
- How competitive your category is
- How often you publish or update content
- How quickly you need to detect displacement on priority prompts
A common approach is:
- Higher frequency checks for a small set of high value prompts
- Lower frequency checks for a broader prompt library
### Establish a baseline before you change content
Run your prompt set for a baseline window long enough to compare against, then document:
- Mention rate by prompt category
- Citation presence and which URLs are cited
- Competitor presence patterns
- Any early relationship between citations and referral traffic
### Monitor for shifts that require action
Watch for:
- **New coverage**: your brand or pages appear where they did not before
- **Loss of coverage**: you disappear from prompts you previously owned
- **Competitor source replacement**: the answer text still includes you, but citations shift to competitor pages, or the reverse
## Turning tracking into action
Use tracking signals to decide what to build, fix, or update. These are decision patterns rather than universal rules.
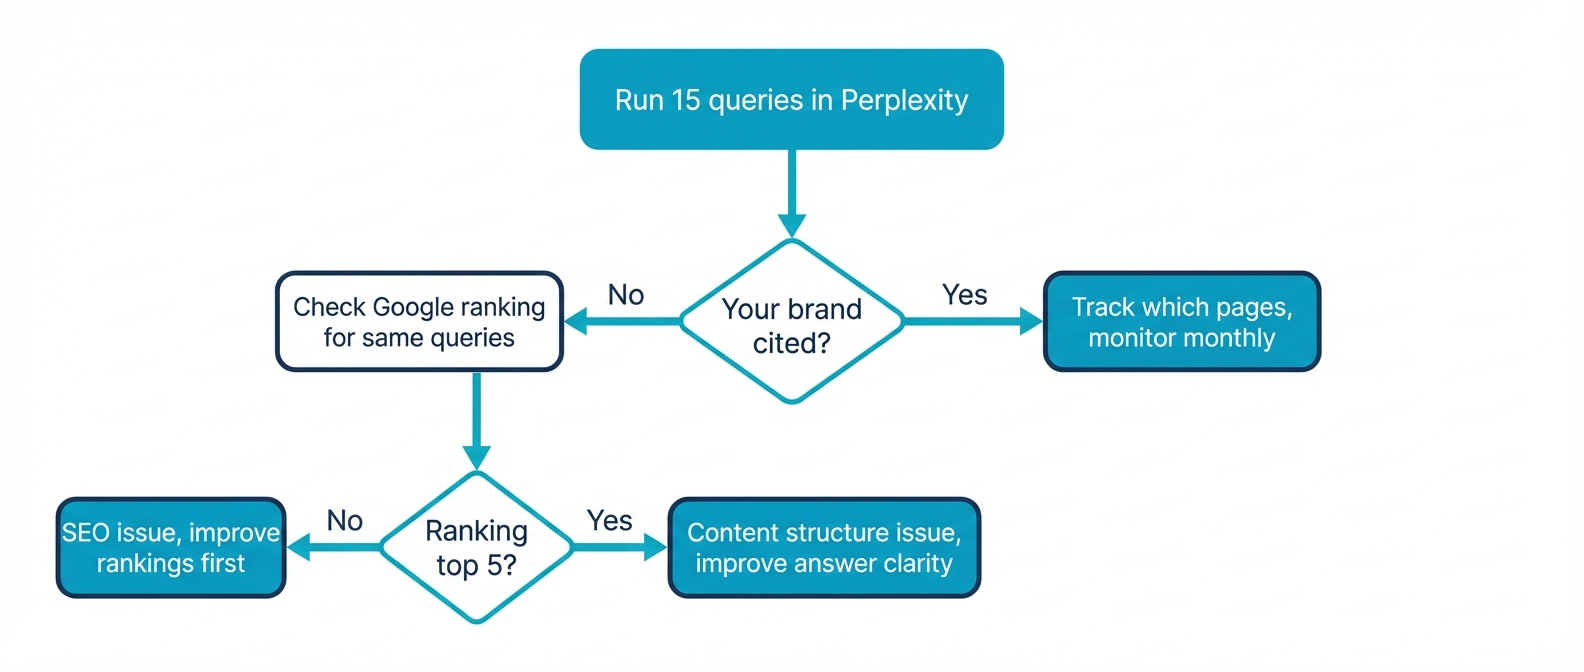
### If you are not being cited at all
Likely causes to investigate:
- Crawl accessibility and indexability issues
- Missing content for the specific query intent
- Your pages are not competitive in the underlying web results Perplexity retrieves
What to do:
- Start with the fundamentals in [How to get cited and mentioned in Perplexity AI](/blog/perplexity-seo-how-to-rank).
- Create intent-matched pages for your priority use cases and comparisons rather than only broad thought leadership.
### If you are cited but not mentioned
What it might mean:
- Your page is useful as background, but other brands are more directly framed as solutions in the narrative.
What to do:
- Review the cited competitor sources in the same answer to see what they make easy for Perplexity to extract: definitions, comparisons, constraints, and plain-language positioning.
- Update the cited page so it clearly answers the query intent and states your relevance without forcing marketing claims.
### If you are mentioned but your site is not cited
What it might mean:
- Perplexity is relying on third-party sources to describe you.
What to do:
- Identify which third-party pages are being cited and whether they are accurate.
- Publish or improve pages that are appropriate sources for the queries where you want first-party citations, such as comparison pages, pricing explainers, integration docs, and use-case guides.
### If your citations are concentrated on one page
Why it is risky:
- A single page becoming the source for most citations creates a fragile visibility profile.
What to do:
- Build supporting pages for adjacent intents so you have multiple credible sources across prompts.
- Strengthen internal linking so Perplexity can reach relevant pages from the cited hub content.
### Hypothetical example: estimating impact without inventing results
If Planway improves a use-case page and begins earning citations on a prompt that previously had none, you might later see an increase in Perplexity referral sessions to that page. The size of that increase depends on user behavior and how often users click citations, so treat analytics changes as confirmation signals, not guaranteed outcomes.
For more on connecting citations to sources over time, see [How to monitor when AI platforms cite your brand](/blog/ai-citation-tracking-how-to-monitor-ai-sources).
## Frequently asked questions
### What metrics should I track for Perplexity visibility?
Track:
- Brand mentions in the answer text
- Citations to your domain and the specific cited URLs
- Competitor presence in both answer text and citations
- Positioning and tone labels you can apply consistently
Use referral traffic as a supplemental metric since clicks are required for visits.
### How do I measure share of voice in Perplexity?
Use a stable prompt set for your category and record, per prompt:
- Which brands are mentioned in the answer text
- Which domains and URLs are cited
Share of voice can be summarized as the proportion of prompts where your brand is mentioned or cited compared with competitors, but keep the underlying per-prompt details so you can act on the drivers.
### Can I track Perplexity citations in Google Analytics?
You can measure **referral traffic from Perplexity** in GA4 by filtering traffic acquisition source/medium for "perplexity". This captures clicks from citations, not total mentions or total citations.
### What is the difference between PerplexityBot and Perplexity-User?
Perplexity documents:
- **PerplexityBot** for indexing pages for Perplexity search results
- **Perplexity-User** for fetching a page in response to a user request
This distinction is useful when diagnosing whether a page can be retrieved and used as a source.
### When should I automate Perplexity tracking?
Automate when:
- Your prompt set is large enough that manual checks become inconsistent
- You need prompt-level history and competitor comparisons
- You want to monitor cited URLs over time rather than only mentions
## CTA: track Perplexity and other AI providers with consistent prompt sets
If you need a repeatable workflow across Perplexity plus other AI providers, friction AI supports multi-provider tracking with prompt-level monitoring and citation-oriented analysis. Validate that the features match your reporting needs and team workflow before adopting any platform.
[](https://www.frictionai.co/pricing)
Last verified: July 26, 2026
---
# AI Brand Health Audit: How to Assess Your AI Presence
# URL: https://www.frictionai.co/blog/ai-brand-health-audit
# Slug: ai-brand-health-audit
# Category: Monitoring & Measurement
# Published: 2026-03-29
# Author: Joao Da Silva, Co-Founder of friction AI
# Keywords: AI brand health audit, AI brand audit, AI presence assessment, AI brand health check, audit AI visibility, AI brand scorecard, brand health AI, AI brand analysis, AI visibility audit, brand AI assessment
**An AI brand health audit** is a systematic assessment of how AI platforms like ChatGPT, Perplexity, Gemini, and Google's AI features perceive, describe, and recommend your brand. It evaluates whether AI-generated answers about your brand are accurate, positive, and frequent enough to support your business goals, giving you a clear picture of your brand's standing in the AI-driven discovery channel.
> **TL;DR:** An AI brand health audit checks how ChatGPT, Perplexity, Gemini, and Google AI describe and recommend your brand. It's how you catch gaps before they compound.
> - [72% of organizations have adopted at least one AI tool (McKinsey, 2024)](https://www.mckinsey.com/capabilities/quantumblack/our-insights/the-state-of-ai)
> - Audit five dimensions: visibility, accuracy, sentiment, competitive position, citations
> - Establish a baseline now so you're measuring progress, not guessing
## What Is an AI Brand Health Audit?
Your brand has a reputation in AI. Whether you've shaped it or not, AI platforms are already answering questions about your company, products, and category. An AI brand health audit tells you what those answers look like.
This isn't a one-time curiosity exercise. AI platforms are increasingly where your customers go before they buy. [A 2024 survey from McKinsey](https://www.mckinsey.com/capabilities/quantumblack/our-insights/the-state-of-ai) reported that 72% of organizations had adopted at least one AI tool, and consumer adoption of AI assistants for product research continues to climb.
If a potential customer asks ChatGPT "What's the best [your category] tool?" and your brand isn't mentioned, or worse, its mentioned with negative framing, that's a problem you need to know about. An AI brand health audit surfaces these issues before they compound.
The audit also establishes a baseline. You can't improve what you dont measure. Once you've documented your current AI brand health, you can track progress as you optimize your entity signals, content, and web presence.
## The 5 Dimensions of AI Brand Health
A comprehensive audit evaluates your brand across five distinct dimensions. Each captures a different aspect of how AI platforms interact with your brand.
### Visibility
Visibility measures how often your brand appears in AI-generated answers. When users ask questions in your category, does your brand show up?
This goes beyond a binary yes or no. You need to know your visibility rate: out of 100 relevant prompts, how many produce a response that mentions your brand? You also need to know your position within those responses. Being mentioned first carries more weight than being listed fifth.
Track visibility across multiple AI platforms. Your brand might be well-represented in ChatGPT but absent from Perplexity, or strong in Google AI Overviews but missing from Gemini. Each platform draws from different data sources, so visibility gaps are common and platform-specific.
### Accuracy
Accuracy measures whether AI platforms describe your brand correctly. This includes your product capabilities, pricing, company size, founding date, leadership team, and competitive positioning.
AI hallucination is a documented problem. [Research published by Stanford's Institute for Human-Centered AI](https://hai.stanford.edu/) has shown that LLMs can generate plausible but incorrect statements about real entities, including brands. Your audit needs to catch these inaccuracies.
Test accuracy by asking AI platforms factual questions about your brand: "What does [your brand] do?", "How much does [your brand] cost?", "Who founded [your brand]?" Compare every answer against reality. Flag any inaccuracies and assess there severity. A wrong founding year is minor. A wrong description of your core product is critical.
### Sentiment
Sentiment captures the emotional framing AI platforms use when discussing your brand. Is the language positive, neutral, or negative? Does the AI recommend your brand enthusiastically, or does it hedge with caveats and qualifiers?
Pay attention to subtle sentiment signals. There's a meaningful difference between "HubSpot is a popular CRM" and "HubSpot is widely regarded as the best CRM for small businesses." Both are positive, but the second carries a stronger endorsement.
Also check sentiment in competitive contexts.
When your brand appears alongside competitors, how does the AI frame the comparison? Are you positioned as the leader, an alternative, or an afterthought?
### Citation Rate
Citation rate measures how often AI platforms link back to your content as a source. This applies primarily to platforms with source attribution: Perplexity, Google AI Overviews, AI Mode, and Claude (which sometimes cites sources).
A high citation rate means AI platforms aren't only mentioning your brand but actively referencing your content as authoritative. This drives direct traffic and reinforces your brand's expertise positioning.
Track which specific pages on your site get cited most often. This tells you what content formats and topics AI platforms consider most valuable from your domain.
### Recommendation Rate
Recommendation rate is the most commercially important dimension. It measures how often AI platforms recommend your brand when users express purchase intent or ask for advice.
This differs from visibility. Your brand might be mentioned in an informational response ("companies in this space include...") without being recommended ("I'd recommend..."). The recommendation rate captures the higher-value interactions where AI platforms actively steer users toward your brand.
Test with purchase-intent prompts: "What's the best [category] tool?", "Which [category] product should I buy?", "What do you recommend for [problem]?" Your recommendation rate is the percentage of these prompts where your brand appears as a suggested option.
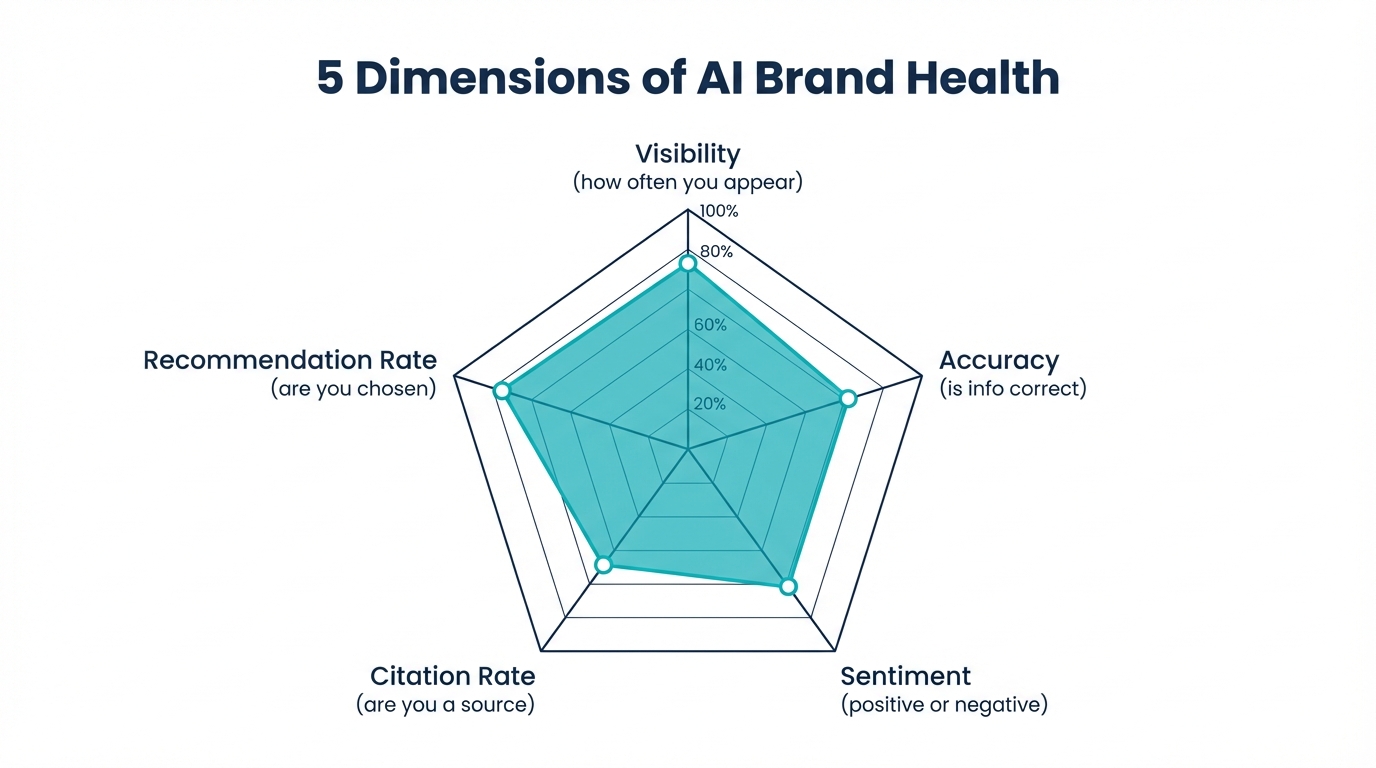
## See It in Action
Watch how to run a quick AI brand visibility check:
[](https://youtu.be/Tj1UwEm1Xg4)
## Step-by-Step Audit Framework
Follow this process to run a complete AI brand health audit.
### Step 1: Define Your Prompt Library
Create 30-50 prompts across four categories:
- **Brand-specific prompts** (10-15): "What is [your brand]?", "Is [your brand] good?", "Tell me about [your brand]"
- **Category prompts** (10-15): "Best [your category] tool", "Top [your category] companies"
- **Comparison prompts** (5-10): "[Your brand] vs [competitor]", "Compare [your brand] and [competitor]"
- **Problem/solution prompts** (5-10): "How to solve [problem your brand addresses]", "Best way to [task your brand helps with]"
### Step 2: Run Prompts Across Platforms
Execute every prompt on ChatGPT, Perplexity, Gemini, and Google AI Overviews. Run each prompt at least twice to account for response variation. Log the complete response for each.
### Step 3: Score Each Dimension
For each response, evaluate and score the five dimensions. Use the scorecard framework below. Calculate averages per dimension and per platform.
### Step 4: Identify Critical Gaps
Look for patterns in your scoring. Common gap patterns include:
- High visibility, low recommendation rate (you're known but not preferred)
- Low visibility on specific platforms (platform-specific entity gaps)
- Accuracy issues with specific facts (outdated or incorrect training data)
- Negative sentiment in competitive comparisons (competitors positioned above you)
### Step 5: Build Your Action Plan
Prioritize fixes by business impact. Accuracy issues should be addressed first, since incorrect information about your brand causes immediate harm. Then focus on visibility and recommendation rate, which drive revenue outcomes. Sentiment improvements often follow naturally from the other optimizations.
### Step 6: Re-Audit Monthly
AI platforms update their models and data sources regularly. A single audit gives you a snapshot. Monthly re-audits track your progress and catch regressions early.
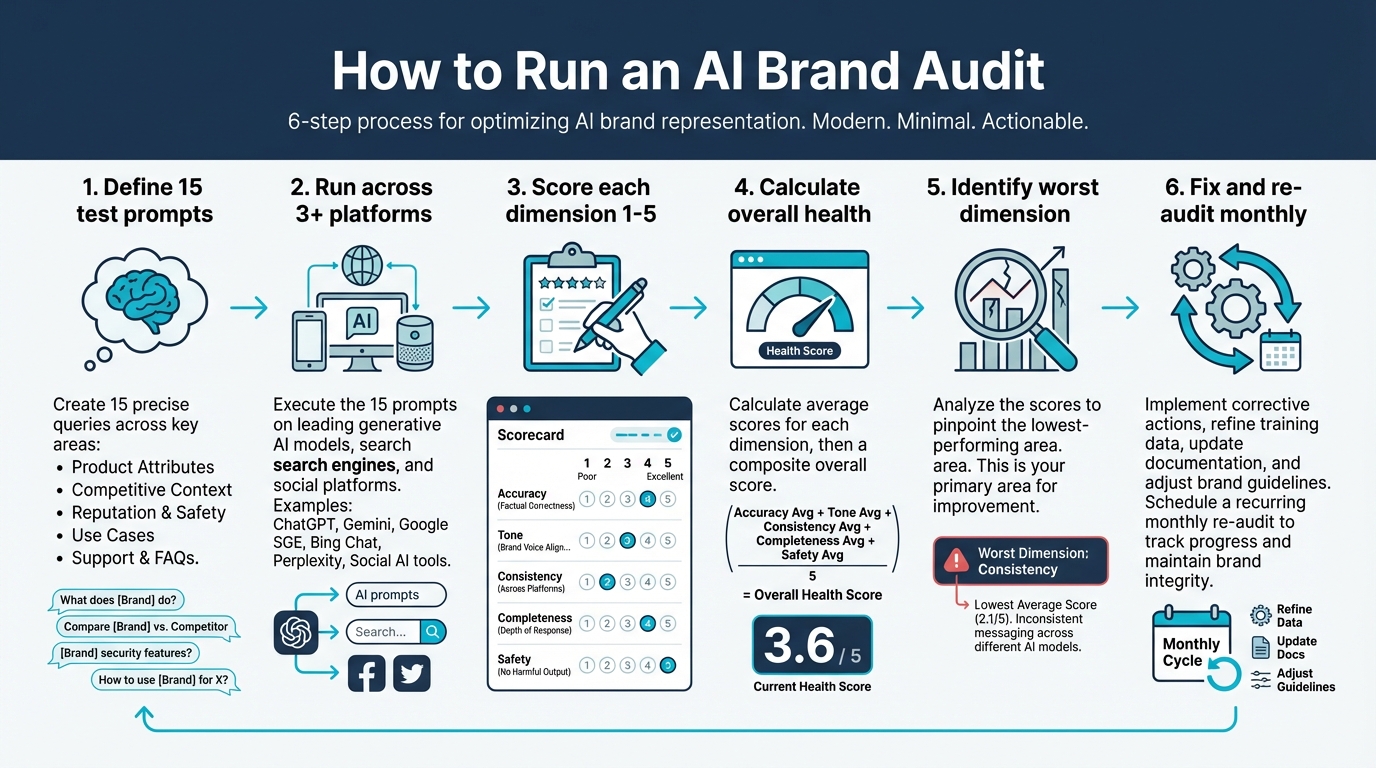
## AI Brand Health Scorecard
Use this scoring framework to evaluate each dimension of your AI brand health.
| Dimension | Score 1 (Poor) | Score 2 (Below Average) | Score 3 (Average) | Score 4 (Good) | Score 5 (Excellent) |
|---|---|---|---|---|---|
| Visibility | Not mentioned in any prompts | Mentioned in <20% of prompts | Mentioned in 20-50% of prompts | Mentioned in 50-75% of prompts | Mentioned in 75%+ of prompts |
| Accuracy | Multiple critical errors | 1-2 critical errors or many minor errors | No critical errors, several minor errors | No critical errors, 1-2 minor errors | Fully accurate across all responses |
| Sentiment | Negative framing or warnings | Neutral with caveats | Neutral, factual descriptions | Positive framing, some endorsement | Strong endorsement language |
| Citation Rate | Never cited as a source | Cited in <10% of responses | Cited in 10-25% of responses | Cited in 25-50% of responses | Cited in 50%+ of responses |
| Recommendation Rate | Never recommended | Recommended in <10% of intent prompts | Recommended in 10-30% of intent prompts | Recommended in 30-60% of intent prompts | Recommended in 60%+ of intent prompts |
**Interpreting your aggregate score:**
- **5-10 points**: Your AI brand health needs urgent attention. AI platforms are either ignoring your brand or misrepresenting it.
- **11-15 points**: You have foundational presence but significant gaps. Focus on the lowest-scoring dimensions first.
- **16-20 points**: Solid baseline. Targeted optimization can push you into a leadership position.
- **21-25 points**: Strong AI brand health. Maintain your position and monitor for regressions.
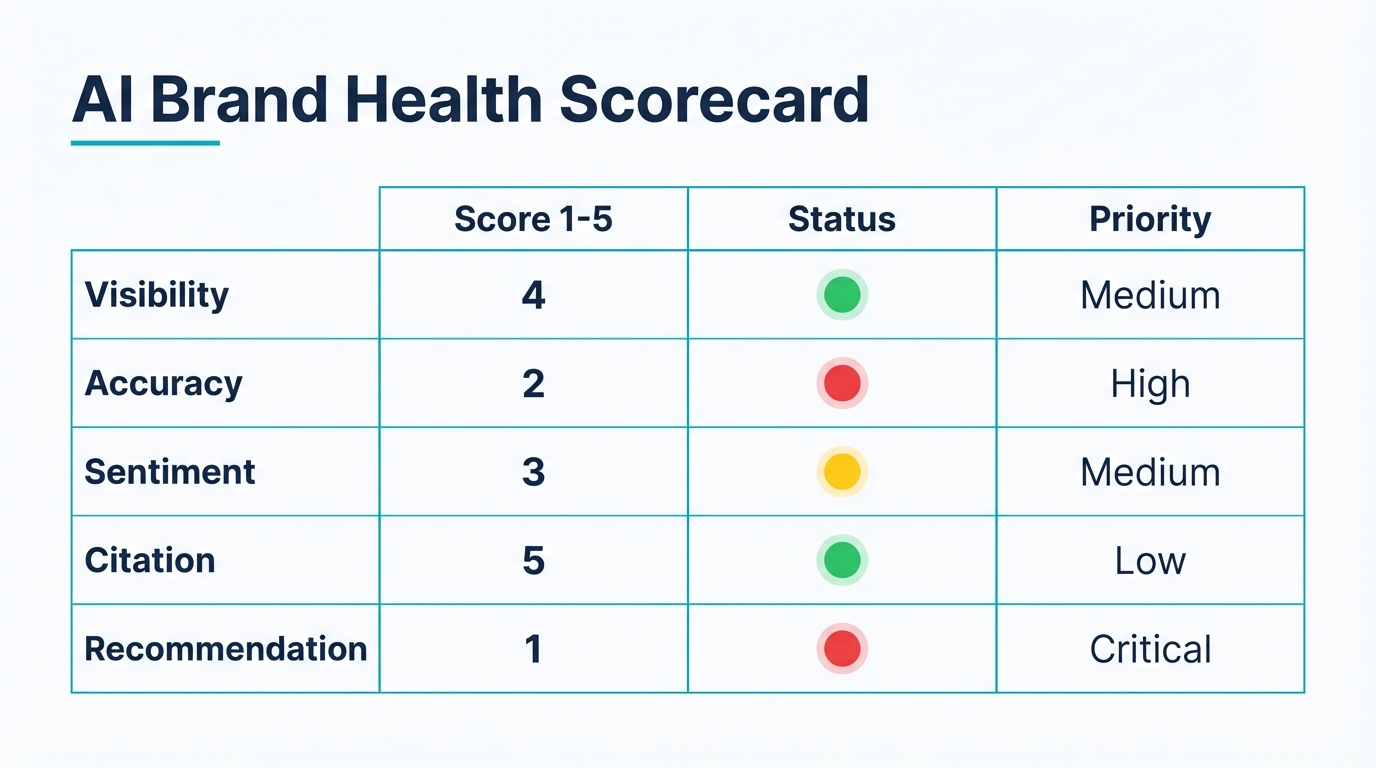
## Tools for Automating Your Audit
Manual auditing works for a first-pass assessment, but it has hard limits. Running 40+ prompts across four platforms, scoring each response across five dimensions, and repeating this monthly is time-intensive and prone to inconsistency.
friction AI automates the entire AI brand health audit process. The platform monitors your brand across ChatGPT, Perplexity, Gemini, and Google's AI features continuously. Instead of running manual prompts, you get a live dashboard showing your visibility, sentiment, recommendation rate, and competitive positioning.
The platform's competitive intelligence feature lets you benchmark your AI brand health against specific competitors. You see exactly where you lead, where you trail, and what's changing over time.
For teams running their first audit, the manual framework above gives you a solid baseline. For ongoing monitoring and competitive tracking, automated tooling becomes a requirement. The brands that treat AI brand health as a continuous metric rather than a one-time project are the ones that maintain and grow their positions.
## Related Articles
- [What Is AI Sentiment?](/blog/what-is-ai-sentiment)
- [How to Measure AI Visibility](/blog/how-to-measure-ai-visibility)
- [How to Control What AI Says About Your Brand](/blog/how-to-control-what-ai-says-about-your-brand)
[](https://www.frictionai.co/pricing)
---
# Perplexity SEO: How to Rank in Perplexity Search (2026)
# URL: https://www.frictionai.co/blog/perplexity-seo-how-to-rank
# Slug: perplexity-seo-how-to-rank
# Category: Platform Playbooks
# Published: 2026-03-29
# Author: Joao Da Silva, Co-Founder of friction AI
# Keywords: Perplexity SEO, rank in Perplexity, Perplexity search optimization, Perplexity ranking signals, optimize for Perplexity, Perplexity AI SEO, Perplexity search ranking, Perplexity citation, Perplexity SEO guide, Perplexity SEO 2026
**Perplexity SEO** is the practice of optimizing your content to appear as a cited source in Perplexity AI's search results. Unlike ChatGPT or Gemini, Perplexity functions as a search engine first, crawling the web in real time and citing every source it uses, making it the most transparent AI search platform for brands tracking their visibility.
> **TL;DR:** Perplexity SEO is about earning inline citations inside real-time AI answers. The platform crawls the web with PerplexityBot, retrieves current sources through a RAG pipeline, and links every claim back. Ranking depends on source freshness, authority, and specificity, not static training data.
> - Perplexity processes hundreds of millions of queries ([Perplexity docs](https://docs.perplexity.ai/))
> - Citations are clickable, making Perplexity the most transparent AI platform
> - Focus Modes and Pro responses expand your citation opportunities
## How Perplexity's Search Engine Works
Perplexity operates differently from other AI platforms. Understanding its architecture is the foundation for optimizing your presence on it.
### Real-Time Web Crawling
Perplexity doesn't rely on static training data for its search responses. It crawls the web in real time using its own bot, [PerplexityBot](https://docs.perplexity.ai/guides/perplexitybot), which visits pages, indexes content, and feeds current information into its response generation.
This real-time approach means your content's current state matters, not what it looked like six months ago when a language model was being trained. If you publish a new comparison guide today, Perplexity can discover, index, and cite it within days.
### The Citation Model
Perplexity's defining feature is inline citations. Every claim in a Perplexity response links back to a source. Users see numbered citations throughout the response, and can click through to the original pages.
This is a significant difference from ChatGPT or Gemini, which may mention brands without linking to any source. On Perplexity, if your content appears, users can reach your site directly. That makes Perplexity citations a measurable, traffic-driving asset.
According to [Perplexity's own documentation](https://docs.perplexity.ai/), the platform processes hundreds of millions of queries and serves millions of users. Its audience skews toward researchers, professionals, and information-intensive searchers who value sourced answers.
### Response Generation Pipeline
When a user asks Perplexity a question, the system follows a retrieval-augmented generation (RAG) pipeline. First, it formulates search queries based on the user's prompt. Then it retrieves relevant pages from across the web. The language model synthesizes the retrieved content into a coherent answer, attributing specific claims to specific sources.
The retrieval step is where your content either makes the cut or gets passed over. Perplexity selects sources based on relevance, authority, and the specificity of the information they provide.
### Perplexity Pro and Focus Modes
Perplexity offers different search modes that affect how sources are selected. The default search casts a wide net. Focus modes narrow retrieval to specific source types: Academic, Writing, YouTube, Reddit, and more. If your content is relevant to academic or professional queries, understanding which focus modes your audience uses helps you target your optimization.
Perplexity Pro uses more advanced models and deeper retrieval, pulling from more sources and producing longer, more detailed responses. Pro responses tend to cite more sources per answer, increasing the opportunities for your content to appear.
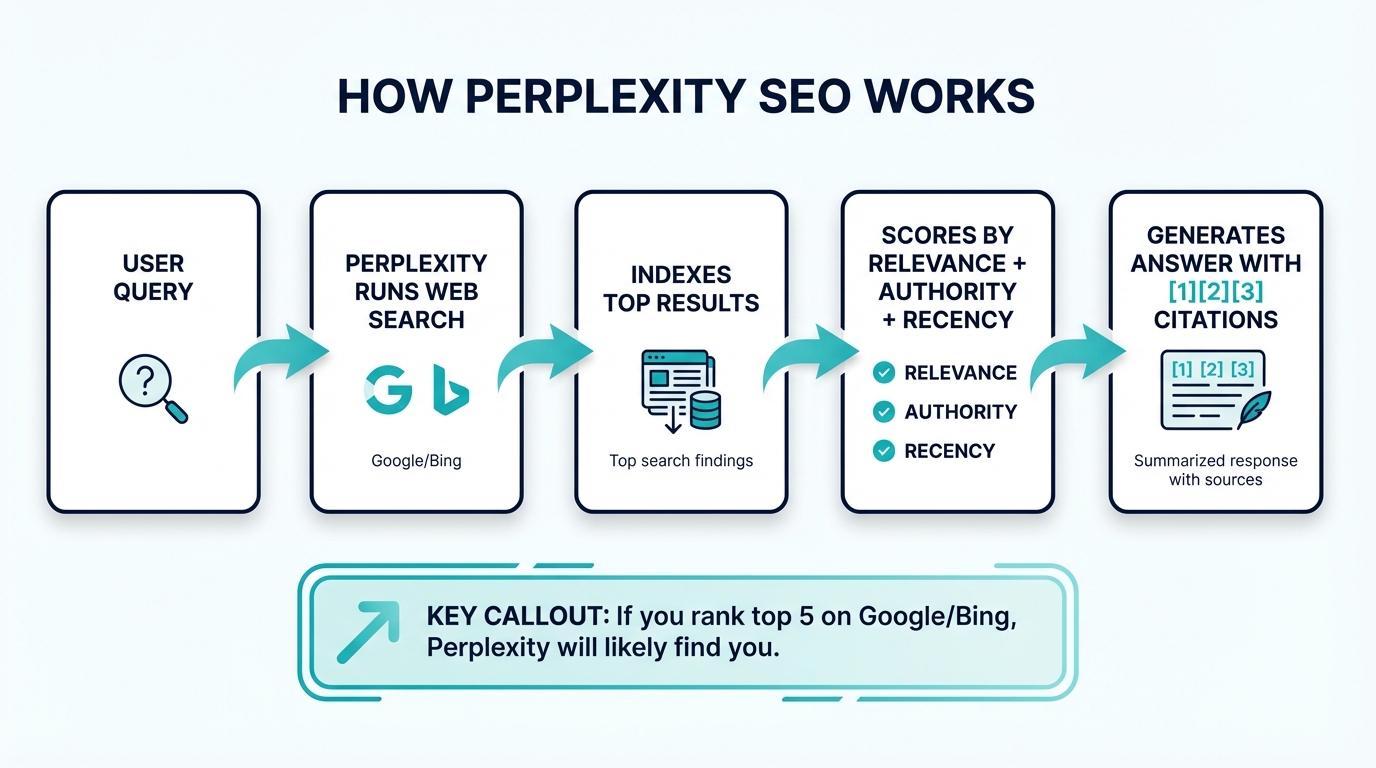
## Perplexity Ranking Signals
Perplexity hasn't published a formal ranking algorithm, but consistent patterns emerge from analysis of its citation behavior.
### Source Freshness
Because Perplexity crawls the web in real time, fresh content has a direct advantage. A guide updated this month will be preferred over an identical guide last updated in 2024. Perplexity's results frequently include recent publications, and its interface highlights publication dates when available.
Maintain visible "last updated" dates on your content. Refresh statistics, examples, and comparisons regularly.
### Domain Authority
High-authority domains appear more frequently in Perplexity citations. This aligns with how the platform's retrieval system evaluates source credibility. A claim from a well-known industry publication or a high-authority brand site will be preferred over the same claim on a low-authority blog.
Your existing domain authority, built through traditional SEO, directly supports your Perplexity visibility. According to [a study from Surfer SEO](https://surferseo.com/blog/ai-overviews-study/), high-authority domains are disproportionately represented in AI-generated citations across platforms, including Perplexity.
### Content Specificity
Perplexity cites content that makes specific, attributable claims. "Our survey of 1,200 marketers found that 67% increased their AI budget in 2025" gets cited. "Many marketers are increasing budgets" doesn't.
Each citation in a Perplexity response links to a source because the model pulled a specific piece of information from that source.
Your content needs to contain those specific, citable data points.
### Structural Clarity
Content with clear headings, comparison tables, numbered lists, and well-organized sections is easier for Perplexity's retrieval system to parse and extract information from. Dense, unstructured prose is harder for the system to work with.
### Topical Relevance and Depth
Perplexity prefers pages that cover a topic thoroughly rather than pages that touch on it briefly. A comprehensive guide to a subject will be cited more frequently than a surface-level overview, because the comprehensive guide provides more citable claims across more subtopics within a query's scope.
## Perplexity SEO vs ChatGPT SEO
Both platforms are AI-powered, but they require different optimization approaches.
| Dimension | Perplexity SEO | ChatGPT SEO |
|---|---|---|
| Search method | Real-time web crawling via PerplexityBot | Bing index (browsing mode) + training data |
| Citation style | Always cited, inline numbered references | Occasional citations in browsing mode, none in default |
| Traffic potential | Direct clicks from inline citations | Limited, mostly brand awareness |
| Content freshness | High impact (real-time crawl) | Moderate (browsing) to low (training data) |
| Crawler control | PerplexityBot in robots.txt | GPTBot in robots.txt |
| Transparency | Full source visibility for every claim | Opaque in default mode, partial in browsing |
| User intent | Research-heavy, detail-oriented queries | Conversational, broad questions |
| Optimization speed | Days to weeks (real-time indexing) | Weeks to months (Bing indexing) to unknown (training data) |
The biggest practical difference: Perplexity citations drive clicks. Every source is linked and visible to the user. ChatGPT mentions may drive awareness but rarely drive direct traffic unless the user is in browsing mode and clicks a citation.
This makes Perplexity SEO more directly measurable than ChatGPT SEO. You can track referral traffic from perplexity.ai in your analytics and tie it to specific pages.
## SEO Tactics Specific to Perplexity
Here's what to prioritize for Perplexity visibility, ranked by impact.
### Publish Original Data and Research
Original data is the single highest-impact tactic for Perplexity SEO. When Perplexity needs to answer a question with a specific statistic or data point, it cites the primary source. Be that primary source.
Publish survey results, benchmark data, proprietary analysis, and case studies with real numbers. Content built on original data gets cited repeatedly across different queries, because the data point is unique to your content.
### Build Comprehensive Comparison Content
Perplexity users frequently ask comparison questions. "What's the difference between X and Y?" "Which CRM is best for small teams?" "How does [your category] pricing compare?"
Create detailed comparison pages with structured tables, feature breakdowns, and specific evaluation criteria. These pages align with a high volume of Perplexity queries and provide the structured information that Perplexity's citation model prefers.
### Create FAQ-Style Content Structures
Perplexity excels at answering specific questions. Pages structured around frequently asked questions, with clear question headings and direct answers, match Perplexity's query-response pattern. The platform can extract a specific answer from your FAQ and cite it for the relevant question.
### Keep Content Current
This bears repeating because its more impactful on Perplexity than on any other AI platform. Perplexity's real-time crawl means it can access and cite your content as soon as it's published or updated. Set a monthly cadence for reviewing your highest-traffic pages and updating any stale information.
### Define Your Expertise Clearly
Your about page, author bios, and content bylines establish your site's authority on specific topics. Perplexity's retrieval system considers topical authority when selecting sources. If your site demonstrates deep expertise in a specific domain through extensive, authoritative coverage, your content in that domain will be cited more frequently.
### Write for Researchers
Perplexity's user base skews toward research-oriented queries. These users want depth, evidence, and sourced claims. They're not looking for surface-level overviews. Write content that satisfies a researcher's expectations: thorough analysis, supporting evidence, and clear methodology.
## Technical Requirements for Perplexity
Getting your technical setup right ensures Perplexity can access and index your content without friction.
### Robots.txt Configuration
Check your robots.txt file for PerplexityBot directives. If you want Perplexity to index your content (and you should, if you're reading this), make sure you're not blocking PerplexityBot. Perplexity [documents its bot behavior](https://docs.perplexity.ai/guides/perplexitybot) and respects robots.txt rules.
If your robots.txt blocks PerplexityBot, your content won't appear in Perplexity results regardless of its quality. Check this first.
### Page Load Performance
PerplexityBot, like any crawler, has timeouts. If your pages load slowly, the crawler may not fully index your content. Standard web performance best practices apply: optimize images, minimize render-blocking resources, and ensure server response times are under one second.
### Crawlable Content
Content rendered through client-side JavaScript can be difficult for crawlers to access. Ensure your critical content is available in the initial HTML response or rendered server-side. Test by viewing your page's source (not the rendered DOM) to confirm your key content is present.
### Sitemap and Internal Linking
A current XML sitemap helps PerplexityBot discover your pages. Strong internal linking between related pages reinforces topical relationships and helps the crawler understand your site's content architecture.
### Structured Data
While Perplexity's retrieval doesn't depend on schema markup the way Google's featured snippets do, structured data provides additional signals about your content's topic, type, and attributes. Implementing FAQ, HowTo, and Product schema adds machine-readable context that can inform retrieval decisions.
## How to check whether your brand appears in Perplexity
Build a small prompt set before changing the site. Include category prompts, problem-based prompts, comparisons, and questions that should cite your own research or documentation.
For each prompt, record whether the brand is mentioned, where it appears, which pages Perplexity cites, and whether the description is accurate. Run each prompt more than once and save the date. This separates a one-off response from a repeatable visibility pattern.
Use [Perplexity brand tracking](/blog/track-brand-visibility-perplexity) for ongoing measurement. Use the optimization steps below when the cited pages or missing topics explain why the brand is absent.
## Tracking Your Perplexity SEO Results
Perplexity is the most trackable AI search platform, thanks to it's transparent citation model.
For a full framework covering metrics, baseline methodology, and analytics integration, see our [Perplexity brand tracking guide](/blog/track-brand-visibility-perplexity).
### Referral Traffic
Monitor your analytics for traffic from perplexity.ai. This direct referral metric tells you how many users click through from Perplexity citations to your site. In Google Analytics 4, check the referral source report and filter for perplexity.ai.
The traffic volume may be modest compared to Google organic, but pay attention to engagement metrics. Perplexity referral traffic often shows higher time on page and lower bounce rates, because users arriving from Perplexity are typically in research mode with specific intent.
### Citation Monitoring
Track which of your pages Perplexity cites and for which queries. You can do this manually by running your target queries through Perplexity and documenting the results, or use an AI visibility platform that automates this monitoring.
Build a query set of 20-40 questions that represent your target audience's research behavior. Run these monthly and track citation presence and position over time.
### Competitive Citation Analysis
Run competitor queries through Perplexity and document which brands get cited. If a competitor appears as a source for queries relevant to your category and you don't, that gap tells you where to create or improve content.
Track your citation share of voice: across your query set, what percentage of citations point to your content versus competitors? This metric reveals your competitive position on Perplexity specifically.
### Page-Level Performance
Identify which of your pages get cited most frequently on Perplexity. These high-performing pages can serve as templates for future content. Analyze what they have in common: format, depth, data density, and structure. Apply those patterns to other pages.
### AI Visibility Platforms
Manual tracking works for small-scale monitoring but becomes impractical as your query set and competitive tracking needs grow. Dedicated AI visibility platforms can automate Perplexity monitoring alongside other AI search engines, providing consistent tracking over time. For a full comparison, see [What is Generative Engine Optimization?](/blog/what-is-geo-generative-engine-optimization).
## Related Articles
- [How to Appear in Perplexity AI](/blog/perplexity-seo-how-to-rank)
- [AI Citation Tracking: How to Monitor AI Sources](/blog/ai-citation-tracking-how-to-monitor-ai-sources)
- [What is Generative Engine Optimization?](/blog/what-is-geo-generative-engine-optimization)
[](https://www.frictionai.co/pricing)
---
# AI Search Optimization: How to Get Found in AI-Powered Search (2026)
# URL: https://www.frictionai.co/blog/ai-search-optimization-guide
# Slug: ai-search-optimization-guide
# Category: AEO & GEO Guides
# Published: 2026-03-29
# Author: Joao Da Silva, Co-Founder of friction AI
# Keywords: AI search optimization, AI search ranking factors, optimize for AI search, AI search strategy, AI search visibility, AI powered search optimization, AI search 2026, get found in AI search, AI search ranking, AI search guide
**AI search optimization** is the practice of structuring your brand's content, [authority signals](/blog/building-brand-authority-ai-platforms-recognize), and digital presence so that AI-powered search platforms, including Google AI Overviews, ChatGPT, Perplexity, and Gemini, surface, cite, and recommend your brand in their generated responses. It extends traditional search optimization into a new category of discovery where synthesized answers replace clickable links.
> **TL;DR:** AI search optimization gets your brand mentioned in AI-generated answers on ChatGPT, Perplexity, Gemini, and Google AI Overviews. It's a new layer on top of SEO, not a replacement.
> - [Authoritative citations boost visibility in generative engine outputs by up to 40% (Princeton GEO study)](https://arxiv.org/abs/2311.09735)
> - Seven ranking factors, from source authority to entity clarity to content freshness
> - AI picks one answer, there's no page two
## What is AI Search Optimization?
Traditional SEO got your pages ranked in a list. AI search optimization gets your brand mentioned in a conversation.
The distinction matters becuase AI search engines don't send users to ten blue links. They construct an answer by pulling from multiple sources, synthesizing the information, and presenting a unified response. Your brand either makes it into that response or it doesn't. There's no "page two" to scroll to.
This shift has been accelerating since Google launched AI Overviews (originally Search Generative Experience) in 2023, and as ChatGPT's browsing mode, Perplexity's real-time search, and Gemini's integrated AI became mainstream alternatives to traditional search. [Data from Similarweb](https://www.similarweb.com/blog/insights/ai-news/chatgpt-perplexity-growth-2024/) shows AI search platforms collectively growing usage month over month, pulling query volume away from traditional search.
AI search optimization isn't a replacement for SEO. It's an additional layer. Your existing SEO work feeds into AI retrieval systems, but AI search requires distinct tactics around entity clarity, source authority, content structure, and third-party validation that traditional keyword optimization alone won't cover.
## 7 AI Search Ranking Factors
AI search engines don't publish ranking algorithms the way Google shares its Search Quality Rater Guidelines. But through research, testing, and analysis of AI-generated responses, clear patterns emerge. Here are the seven factors with the strongest influence on AI search visibility.
### 1. Source Authority and Trust
AI systems prioritize information from sources they can trust. Domain authority, editorial reputation, and a track record of accurate, well-sourced content all contribute to whether your pages make it through the retrieval stage.
Research from the [GEO paper published by Princeton and collaborating universities](https://arxiv.org/abs/2311.09735) confirmed that adding authoritative citations to content increased visibility in generative engine outputs by up to 40%. The AI's trust in your content correlates with the trust signals your domain carries.
### 2. Entity Clarity and Consistency
AI models work with entities, discrete concepts with defined attributes and relationships. If your brand is a clear entity with consistent attributes across your website, Wikipedia, Crunchbase, LinkedIn, and industry databases, AI systems can confidently include you in relevant responses.
Inconsistent brand descriptions, conflicting information across platforms, or vague positioning creates ambiguity that AI models resolve by omitting you from responses.
### 3. Content Freshness
Platforms like Perplexity crawl the web in real time. Google AI Overviews pull from the fresh search index. ChatGPT's browsing mode retrieves current pages. Across the board, stale content loses to current content.
This doesn't mean you need to publish daily. It means your core content, comparison pages, pricing data, feature descriptions, and industry statistics, needs regular updates with visible publication dates.
### 4. Factual Specificity
AI models favor content with concrete, verifiable claims over vague assertions. "Our platform processes 2.4 million queries per month across 47 markets" gets cited. "Our industry-leading platform delivers exceptional results" doesn't.
Audit your highest-value pages for vague marketing language. Replace it with specific numbers, timelines, methodologies, and measurable outcomes.
### 5. Structured Content Format
Clear heading hierarchies, comparison tables, definition paragraphs, and logically organized sections all improve the odds that a retrieval system will surface your content and that the synthesis model will incorporate it accurately.
The [Nielsen Norman Group's research on how AI models process content](https://www.nngroup.com/articles/ai-information-scent/) supports what practitioners see in practice: well-structured content is parsed more reliably and cited more frequently.
### 6. Third-Party Consensus
When multiple independent sources mention your brand positively, AI systems gain confidence in recommending you. A product mentioned favorably by TechCrunch, G2 reviewers, and three independent bloggers carries more weight than a product promoted only on its own website.
This consensus signal makes earned media, product reviews, and genuine community presence direct inputs to AI search visiblity.
### 7. Query-Answer Alignment
AI search queries tend to be conversational and specific. "What's the best accounting software for freelancers?" rather than "accounting software." Content that directly addresses these specific, natural-language queries is more likely to be retrieved and synthesized.
Map your content to the actual questions your target audience asks AI search engines, not the short-tail keywords from your traditional SEO playbook.
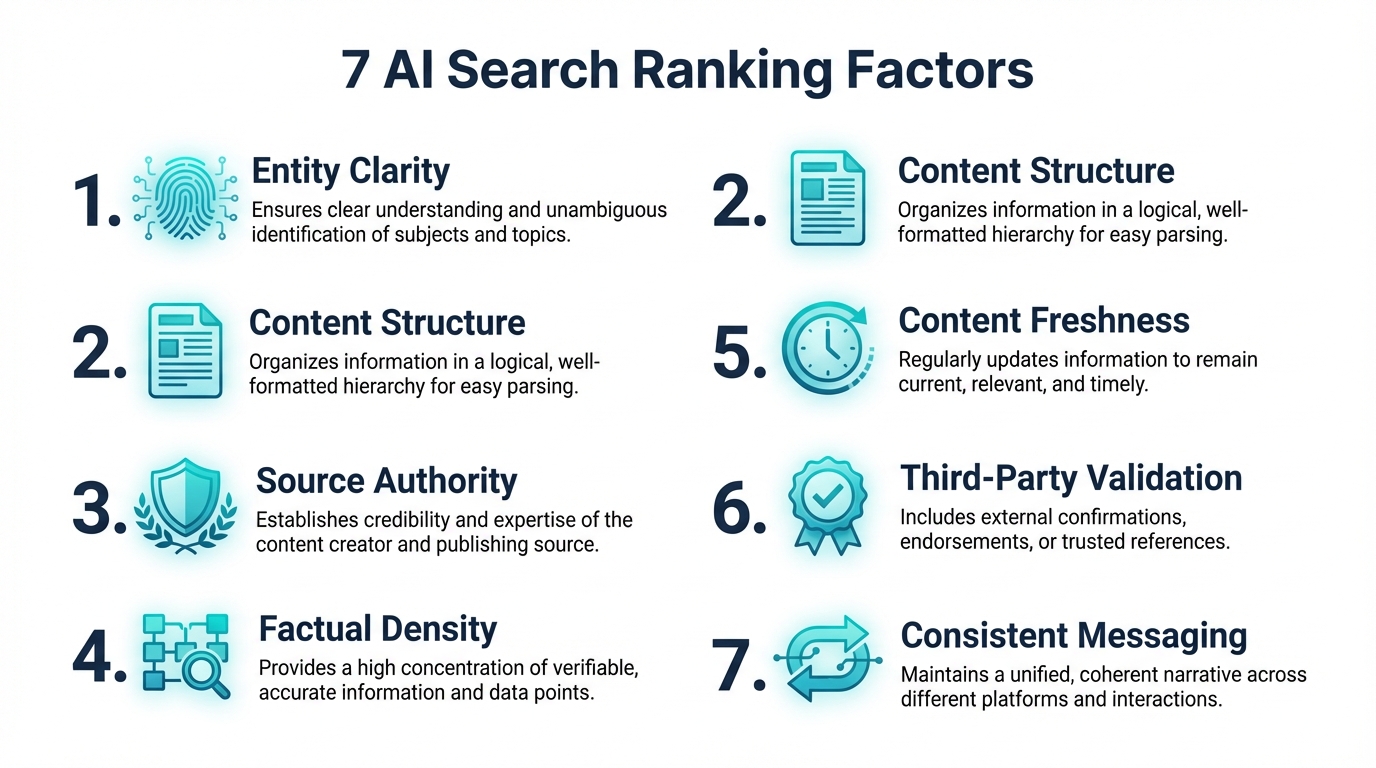
## Platform-by-Platform Optimization
Each AI search platform has unique retrieval mechanics. Optimizing across all of them requires understanding these differences.
### Google AI Overviews
Google AI Overviews sit at the top of search results for many queries, synthesizing information from Google's own search index into a generated summary.
Optimization for AI Overviews builds directly on traditional Google SEO. Pages that rank in the top 10 organic results are the primary source pool for AI Overviews. According to [a study by Zyppy](https://zyppy.com/seo/ai-overview-study/), approximately 99.5% of URLs cited in AI Overviews also appeared in the top 10 organic results.
Focus on strong on-page SEO, clear entity definitions, and structured content for your target queries. Schema markup (FAQ, HowTo, Product) helps Google's systems understand and extract your content for AI Overview synthesis.
### ChatGPT
ChatGPT operates in two modes: generating from training data and browsing the web in real time via Bing's index. Your optimization strategy needs to address both.
For training-data influence, build a strong, consistant brand presence across high-authority sources that are likely included in OpenAI's training corpus, including Wikipedia, major publications, and established industry sites.
For browsing-mode visibility, optimize your Bing presence. Submit your sitemap to [Bing Webmaster Tools](https://www.bing.com/webmasters/about), monitor your Bing rankings, and ensure your content loads properly for Bing's crawler.
### Perplexity
Perplexity AI is a search-first platform that crawls the web in real time and cites every source it uses. This makes it the most transparent AI search engine for tracking your visibility.
Perplexity's crawler ([PerplexityBot](https://docs.perplexity.ai/guides/perplexitybot)) respects robots.txt. Make sure you're not blocking it. Focus on creating content with specific, citable claims, because Perplexity's citation model rewards content it can attribute a distinct piece of information to.
Technical content with clear data points, step-by-step processes, and comparison tables performs well on Perplexity. The platform's users tend to ask detailed, research-oriented questions.
### Gemini
Google's Gemini integrates with Google's broader ecosystem, including Search, Workspace, and Android. It draws from Google's search index and knowledge graph.
Optimization for Gemini overlaps heavily with Google AI Overviews. Strong organic rankings, clear entity presence in Google's Knowledge Graph, and well-structured content are the primary levers. Ensure your Google Business Profile (if applicable) is complete and accurate, as Gemini pulls from this data for local and business-related queries.
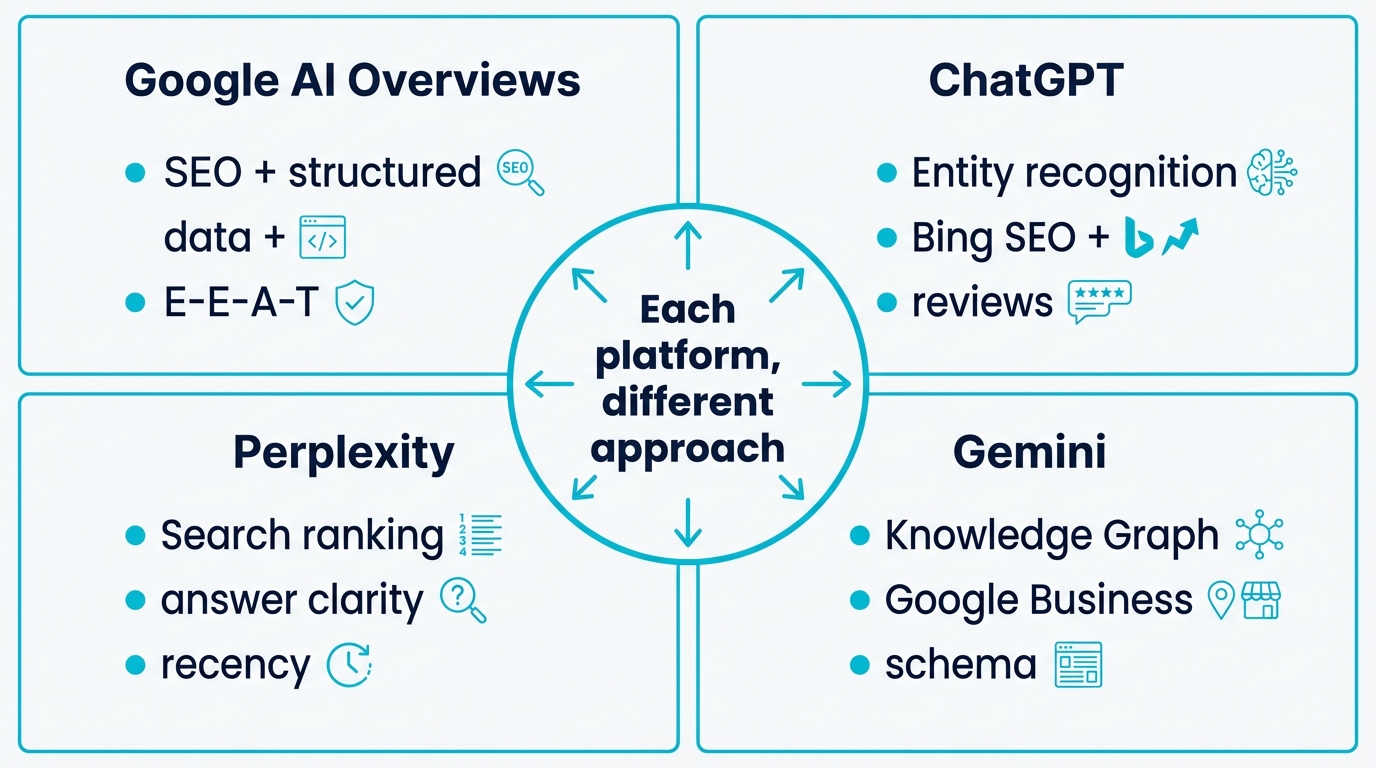
## Common AI Search Optimization Mistakes
Knowing what not to do saves time and prevents wasted effort.
### Treating AI Search as a Keyword Game
Stuffing conversational keywords into your content won't fool AI retrieval systems. These systems evaluate content quality, source authority, and factual accuracy, not keyword density. Focus on creating genuinely useful content that answers real questions.
### Ignoring Bing
Many brands optimize exclusively for Google and treat Bing as an afterthought. Since ChatGPT and Microsoft Copilot both use Bing's index, this blind spot directly reduces your visibility on two major AI platforms.
### Publishing Without Data
Generic thought leadership without supporting data rarely gets cited by AI systems. If you're publishing opinion pieces, supplement them with original research, specific examples, and verifiable claims that give AI models something concrete to reference.
### Neglecting Entity Consistency
If your brand description says one thing on your website, something different on LinkedIn, and something else on Crunchbase, AI models face conflicting information. This ambiguity reduces the likelihood of confident recommendations. Audit your brand presence across platforms and align your messaging.
### Blocking AI Crawlers
Some brands block AI crawlers (GPTBot, PerplexityBot, ClaudeBot) in their robots.txt out of concern about training data usage.
This is a legitimate choice, but understand the tradeoff: blocking these crawlers can reduce your visibility in the associated AI platforms. Make the decision deliberately, not by default.
### Optimizing Once and Walking Away
AI search is not a set-and-forget channel. Models get updated, retrieval indexes refresh, and competitor content evolves. Brands that treat AI search optimization as a one-time project will see their visibility erode as others continue optimizing.
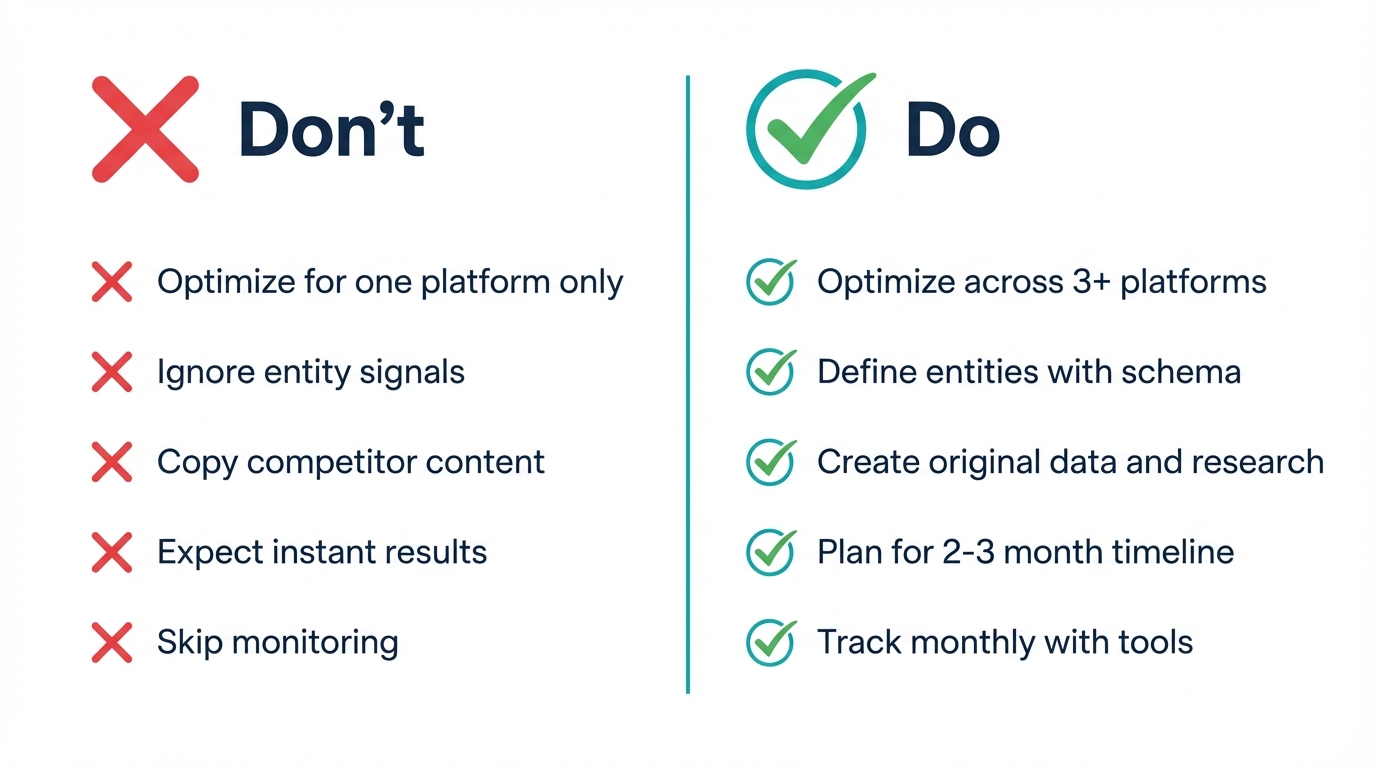
## How to Measure AI Search Performance
Measurement is the biggest challenge in AI search optimization. Traditional analytics weren't built for this channel.
### Core Metrics
**Citation rate** tracks how often your content is cited as a source in AI-generated responses. This is most directly measurable on Perplexity, which always shows source citations.
**Brand mention rate** measures how often your brand name appears in AI responses to relevant queries, whether or not a citation link is included. This captures training-data mentions where no link is provided.
**Recommendation rate** specifically tracks responses where the AI recommends your product or service. This is the highest-intent signal.
**AI share of voice** measures your brand's mention presence relative to competitors across AI search platforms. If five brands compete in your category, what percentage of AI mentions does each capture?
### Building a Query Set
Create a list of 30-50 queries that represent how your target audience would ask AI search engines about your category, product type, and use cases. Run these queries monthly across ChatGPT, Perplexity, Gemini, and Google AI Overviews. Track which brands appear, in what context, and whether citations point to your content.
### Referral Traffic
Monitor your analytics for referral traffic from AI platforms. ChatGPT (chatgpt.com), Perplexity (perplexity.ai), and Google AI Overviews (via Google organic, though harder to isolate) can all drive visitors. The volume may be modest compared to traditional search, but the intent is typically high.
### Automated Monitoring
Manual testing gives you insight but doesn't scale. AI visibility platforms can automate query monitoring, track metrics over time, and alert you to changes in your competitive position across AI search engines.
For industry-specific guidance, see our guide on [AI search optimization for SaaS](/for-saas).
## Related Articles
- [AEO Explained: Complete Guide for 2026](/blog/aeo-explained-guide-2026)
- [What is Generative Engine Optimization?](/blog/what-is-geo-generative-engine-optimization)
- [How to Improve Visibility in AI Search](/blog/how-to-improve-visibility-in-ai-search)
[](https://www.frictionai.co/pricing)
---
# Structured Data for AI Search: What Schema Can and Cannot Do
# URL: https://www.frictionai.co/blog/structured-data-for-ai-search
# Slug: structured-data-for-ai-search
# Category: AEO & GEO Guides
# Published: 2026-03-29
# Author: Joao Da Silva, Co-Founder of friction AI
# Keywords: structured data for AI search, schema markup for AI visibility, structured data for LLMs, Schema.org AI, JSON-LD for AI, structured data AI optimization, schema markup AI search, AI structured data guide, schema for ChatGPT, structured data SEO AI
# Structured Data for AI Search: What Schema Can and Cannot Do
Structured data refers to Schema.org markup, often implemented as JSON-LD, that helps search systems interpret key information about a page and its entities. It can support eligible rich results in Google Search and can make it easier for other systems to parse page meaning, but it is not a guaranteed path to being cited in AI answers.
Google explicitly states there is no special Schema.org markup required for AI Overviews or AI Mode. Structured data should be treated as semantic markup that clarifies what is already visible on the page, not as an AI ranking shortcut. It must match the visible content, and you should only use types like Organization, Article, Product, and SoftwareApplication when they accurately describe the page.
## What structured data can and cannot do for AI search
**What it can do**
- Help search systems understand eligible information on a page and enable supported rich results where applicable.
- Reduce ambiguity about entities and page attributes by providing explicit machine readable statements that match visible content.
- Improve consistency across your site when the same entities appear across multiple pages.
**What it cannot do**
- It does not guarantee inclusion or citation in AI Overviews, AI Mode, or other AI generated answers.
- There is no dedicated AI schema. Adding more markup does not automatically produce more AI visibility.
- It cannot safely contradict, expand, or “upgrade” what the page actually shows. If the content is not visible, the markup should not claim it.
Official references:
- https://developers.google.com/search/docs/appearance/ai-features
- https://developers.google.com/search/docs/appearance/structured-data
## Which Schema types to prioritize
Not all schema types are equally useful. Prioritize types that accurately describe your page and that you can keep consistent across your site.
### Organization schema
Use Organization markup when the page is truly describing your organization and the properties you include are reflected in visible content such as your About, Contact, and brand pages.
Typical properties teams maintain:
- `name`, `url`, `logo`, `description`
- `foundingDate` (only if it is stated on the site)
- `sameAs` (links to official profiles that represent your organization)
- `contactPoint`, `areaServed` (only if supported by visible copy)
Important constraint: do not treat `sameAs` as a place to list every directory. Include only legitimate profiles that are about your organization and that you control or that clearly represent you. If your site does not visibly support a claim, do not add it to JSON-LD.
### Article schema
Use Article markup on pages that are clearly articles, such as blog posts, news, or editorial content. Article markup can help search systems understand the basic facts of a piece: title, author, publisher, and dates.
Include only what is true and visible, commonly:
- `headline`
- `author` (with a real author page if you have one)
- `datePublished`, `dateModified` (only if displayed or otherwise clearly presented on the page)
- `publisher`
- `image`
- `description`
- `mainEntityOfPage`
Reminder: structured data can help search systems understand information, but it does not guarantee AI citations.
### Product schema
Use Product markup only on pages that are actually product detail pages, where the product being described is the visible focus of the page. Follow Google’s Product structured data guidance and keep every property aligned with what users can see.
Official reference:
- https://developers.google.com/search/docs/appearance/structured-data/product
If your page is describing software that is offered as a product, make sure the page content supports the type you pick. If it is a software product page, SoftwareApplication can be appropriate, but only when it accurately describes the visible entity and content.
### SoftwareApplication schema
SoftwareApplication is appropriate when the page is about a specific software application and includes the kind of details users expect such as what it does, platform, and offer details where applicable. Use it only if the page is visibly a software application page and the properties you provide match the page.
If you are unsure whether Product or SoftwareApplication fits better, choose the one that best matches the visible page intent and the entity you are describing, and don't force both unless it is truly justified by what the page presents.
### FAQPage and HowTo schema: use with current Google limits in mind
Google’s support has changed:
- **HowTo rich results are deprecated** in Google Search.
- **FAQ rich results are generally limited** to authoritative government and health sites.
Official reference:
- https://developers.google.com/search/blog/2023/08/howto-faq-changes
That does not mean you should never use these types, but it does mean you should not add them expecting Google rich results, and you should be extra strict about matching visible on page content.
If you include FAQPage markup:
- Use it only on genuine FAQ pages where the questions and answers are visible to users.
- Keep answers accurate, non promotional, and consistent with the page.
If you include HowTo markup:
- Only use it when the page is a real step by step instructional guide with visible steps.
- Do not add it as an “AI formatting” trick, especially given Google’s deprecation of HowTo rich results.
## JSON-LD examples you can adapt safely
These examples are best treated as semantic markup patterns. Adjust them to match your real pages and remove any fields you cannot support with visible content.
### Organization schema example
```json
{
"@context": "https://schema.org",
"@type": "Organization",
"name": "Your Brand Name",
"url": "https://www.yourbrand.com",
"logo": "https://www.yourbrand.com/logo.png",
"description": "One-sentence description of what your brand does and who it serves.",
"foundingDate": "2020-01-15",
"founder": {
"@type": "Person",
"name": "Founder Name"
},
"sameAs": [
"https://www.linkedin.com/company/yourbrand",
"https://twitter.com/yourbrand",
"https://en.wikipedia.org/wiki/Your_Brand"
],
"contactPoint": {
"@type": "ContactPoint",
"contactType": "customer service",
"email": "support@yourbrand.com",
"url": "https://www.yourbrand.com/contact"
},
"areaServed": "US",
"knowsAbout": [
"Your primary topic",
"Your secondary topic",
"Your tertiary topic"
]
}
```
Notes for safe implementation:
- Do not add a Wikipedia or Wikidata URL unless it is real and about your organization.
- Include `foundingDate` and `founder` only if those details are shown on the site.
- Use `knowsAbout` only when it reflects what your organization demonstrably covers across the site.
### FAQPage schema example
```json
{
"@context": "https://schema.org",
"@type": "FAQPage",
"mainEntity": [
{
"@type": "Question",
"name": "What does your brand do?",
"acceptedAnswer": {
"@type": "Answer",
"text": "Clear, concise answer that a system could extract and present directly."
}
},
{
"@type": "Question",
"name": "How does your product compare to alternatives?",
"acceptedAnswer": {
"@type": "Answer",
"text": "Factual comparison that reflects what your page actually states and supports."
}
}
]
}
```
Given current Google limitations on FAQ rich results, implement FAQPage markup primarily to clarify page semantics, not as a promise of enhanced search appearance. Ensure every Q and A is visible on the page and kept up to date.
### Article schema example
```json
{
"@context": "https://schema.org",
"@type": "Article",
"headline": "Your Article Title",
"author": {
"@type": "Person",
"name": "Author Name",
"url": "https://www.yourbrand.com/team/author-name",
"jobTitle": "Author's Title",
"worksFor": {
"@type": "Organization",
"name": "Your Brand Name"
}
},
"datePublished": "2026-03-15",
"dateModified": "2026-03-28",
"publisher": {
"@type": "Organization",
"name": "Your Brand Name",
"logo": {
"@type": "ImageObject",
"url": "https://www.yourbrand.com/logo.png"
}
},
"description": "Meta description that summarizes the article's key takeaway.",
"image": "https://www.yourbrand.com/images/article-image.jpg",
"mainEntityOfPage": "https://www.yourbrand.com/blog/article-slug"
}
```
Only include `dateModified` if you actually track and display meaningful updates. For author markup, make sure the author identity and role are supported by visible bylines and author pages where possible.
## How Google uses structured data, and what that implies for AI features
Google’s structured data documentation is clear about its core role: structured data helps Google understand eligible information and enable supported rich results. It does not guarantee ranking improvements, and it does not guarantee that any AI feature will cite your page.
For AI Overviews and AI Mode specifically, Google states there is no special markup required. The practical takeaway is that your markup strategy should focus on:
- Accuracy and consistency with the visible page
- Choosing schema types that genuinely match the page intent
- Maintaining the markup as your content changes
References:
- https://developers.google.com/search/docs/appearance/ai-features
- https://developers.google.com/search/docs/appearance/structured-data
## Implementation rules that prevent the most common failures
### Keep markup aligned with visible content
Structured data must match what users can see. If you add properties that are not supported by the page, you risk confusing systems that compare markup with page text and UI elements. Keep a simple internal rule: if a user cannot verify it on the page, do not mark it up on that page.
### Use the right type for the page, not the outcome you want
Do not add Product markup to a marketing homepage that does not present a specific product in a product detail format. Do not add Article markup to landing pages. Use Organization markup where your organization is actually described, typically your homepage and About pages.
### Avoid “invisible expansions” of your claims
Do not use schema to sneak in extra features, awards, pricing, ratings, or comparisons that are not on the page. This can create internal inconsistency across your site and can undermine trust signals.
### Keep URLs stable and correct
Common issues that break markup usefulness:
- Wrong canonical URLs in `mainEntityOfPage`
- Broken `sameAs` links
- Logo URL that redirects or 404s
- Author URLs that do not exist
### Maintain dates and authorship responsibly
Dates can be useful when they reflect real publishing and update behavior. Avoid mechanically updating `dateModified` without meaningful revisions. If your site uses author pages, keep author names consistent across bylines and schema.
## Testing and validation workflow
Use two validators and then confirm the markup in the rendered page.
1. **Google Rich Results Test**
https://search.google.com/test/rich-results
Useful for syntax issues and Google eligible structured data validations.
2. **Schema.org Validator**
https://validator.schema.org/
Useful for broader Schema.org validation beyond what Google supports.
3. **Confirm in the page source**
Check that the `